Coder’s Vacation : OMG! JavaScript Libraries Spilled EVERYWHERE! Series #001

NOTE: All parts of this series and my other series can be found on my series links page.

I sat down a few days ago on this trip to get a simple project setup, instead something else happened. It is my fault, entirely my fault. I could have stayed focused on a single library but instead I’ve let them explode. They’re everywhere now in my project!  😮  I’ve learned a great deal about breaking and fixing things though when working with testing frameworks and Node.js. All of this being rooted in my exceedingly simple project called NameFactory on Github. Here’s a few of the things I’ve stumbled through over the course of figuring out these testing frameworks.

vows.js (while chillin’ at Phils Coffee)
Phils Coffee, a staunch cup indeed!

Phils Coffee, a staunch cup indeed!

If you aren’t familiar with vows, here’s the brief description. Vows is a node.js testing framework that is built around the notion of BDD, Behavior Driven Development. The other important thing to note, is vows.js was built specifically to test asynchronous code. It can test others, but it is more oriented toward asynchronous code. Vows also runs tests in parallel, which thinking about that it takes the random order execution and ups the game even further by running them this way. It can really tighten up code execution and regression that things will indeed work in many different conditions. Building for web scale on the internet, that’s something we definitely need!  🙂

To install vows, it follows your standard pattern with npm:

npm install vows

When I installed it I really bit the bullet and went for a global install.

sudo npm install -g vows

From there I spun up a really simple example that is shown on the vows.js site:

var vows = require('vows'),
    assert = require('assert');

vows.describe('Division by Zero').addBatch({
    'when dividing a number by zero': {
        topic: function () { return 42 / 0 },

        'we get Infinity': function (topic) {
            assert.equal (topic, Infinity);
        }
    },
    'but when dividing zero by zero': {
        topic: function () { return 0 / 0 },

        'we get a value which': {
            'is not a number': function (topic) {
                assert.isNaN (topic);
            },
            'is not equal to itself': function (topic) {
                assert.notEqual (topic, topic);
            }
        }
    }
}).run();

From this example you run the tests by executing the code with the following command:

node division-by-zero-test.js

This is all fine, but I’d rather be using the vows test runnner. To do that you’ll need to, instead of *.run(); call the *.export(); function instead. At this point I started scratching my head a bit and looking for parallels between my understanding of BDD and testing and what vows is doing. So I read further and came up with a few observations.

In vows the convention is to have one test suite per file and have the subject match the name. This makes sense to me, that’s how I’ve generally done similar things with Ruby, C# and the like. You end up with something like this for setting the subject and adding the various test suites:

var suite = vows.describe('subject');

suite.addBatch({/* run 1st */}).addBatch({/* 2nd */}).addBatch({/* 3rd */});

suite.addBatch({
   'A context': {
        topic: function () {/* Do something async */},
        'I am a vow': function (topic) {
            /* Test the result of this topic */
        }
    },
   'Another context': {
        topic: function () {/* Do something else async */},
        'I am another vow': function (topic) {
            /* Test the result of this topic */
        },
        'I am another sub-context vow': function (topic) {
            /* Test the result of the topic */
        },
        'And another sub-context': {
            /* Executed when the tests above finish running */
        }
    }
});

Each of the topics are the thing that is being tested with the secondary element of each test being the test to verify the topic. Each of these things are run asynchronously, in parallel, so be sure to keep that in mind when using this framework. However note, in the sub-context tests above the sub-context happens in order. This can be used in various ways, but be sure to not abuse this execution model to avoid the asynchronous nature of JavaScript, I’ve only been working with vows for a few days and have already seen code snippets on the web that have done exactly that!

So this is the first part in a series where I’ll just cover all sorts of JavaScript libraries. It took a Coder’s Vacation however to get me started on this series, enjoy.
Coder’s Vacation : My Slide Deck for the Upcoming HTML 5 Developers Conference

Continuously Kicking Ass

Continuously Kicking Ass

Web development isn’t always easy. Really, there isn’t a form of application development that is easy, there’s a lot of steps, tools, and other traps to coding. One of the best unifying ways to insure that all this complexity doesn’t kick your ass, is to implement continuous integration & delivery practices. I’m going to cover that in a talk this Monday at the HTML 5 Developers Conference in San Francisco. As a precursor to the talk, here’s my slide deck… which I’ll admit isn’t the whole kit and kaboodle, because I will haz codez so subscribe and those I’ll be publishing during this Coder’s Vacation of mine.

NOTE: Pending on levels of connectivity, I’ll be showing a number of details, examples and a little code on implementing continuous integration for JavaScript, specifically with vows and Node.js elements.

Cheers!

Coder’s Vacation : #RICON2012 Photos So Far…

All of these images can be viewed here: http://adronhall.smugmug.com/Software/Meetups-N-Conferences/RICON-2012

San Franciscans heading to work, to RICON and wherever they want to.

San Franciscans heading to work, to RICON and wherever they want to.

RICON 2012 SWAG.

RICON 2012 SWAG.

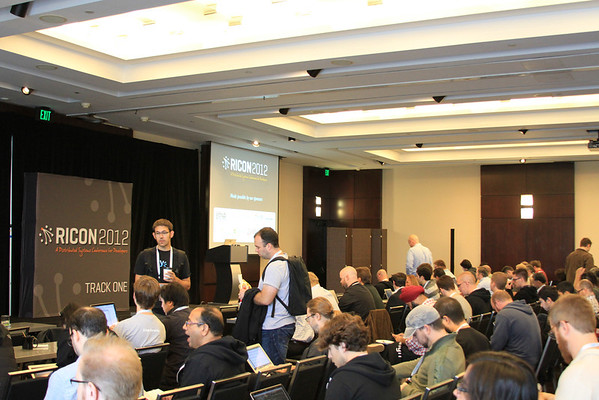
Main Room Filling Up...

Main Room Filling Up…

...and filling up some more.

…and filling up some more.

Basho Crew taking care of conf biz...

Basho Crew taking care of conf biz…

...handling the room.

…handling the room.

The Basho team including Tom Santero @tsantero, Shanley Kane @shanley, and others rocked putting things together and getting everything to us attendees and making sure we headed off like herded cats in appropriate paths to the sessions. Great job! You guys rocked it!

Mark kicking things off...

Mark kicking things off…

All of this hard work setup for a great conference experience with content and more (see my previous blog entry for more). But I digress, on to more pictures. To the right Mark Phillips @pharkmillups kicking off the conference. Below is Don Rippert @djrippert giving an intro, where he pointed out a very important notion, “…this big movement isn’t about cloud or nosql, the movement is about distributed systems…”.

Dan Rippert Basho CEO

Dan Rippert @djrippert Basho CEO

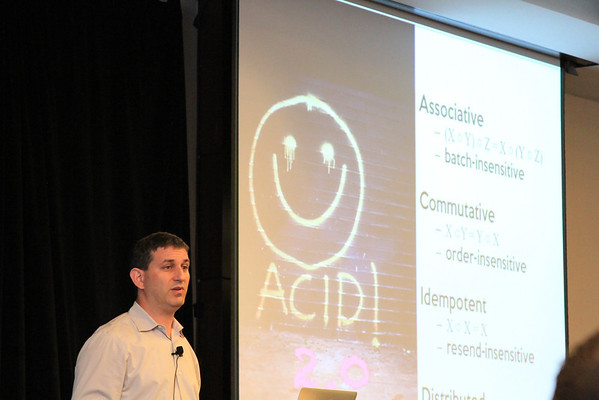
Talking ACID. Absolutely great talk by Joseph Hellerstein, Professor, UC Berkeley

Talking ACID. Absolutely great talk by Joseph Hellerstein @joe_hellerstein, Professor, UC Berkeley

Portland Representing, Selena Marie Handling the Postgresql Preso

Portland Representing, Selena Marie @selenamarie Handling the Postgresql Preso

Amber handling the logistics, thanks for finding my hoodie when it disappeared!

Amber @amberishikawa, thx for finding my hoodie when it disappeared!

Portland Basho Office Representing, Eric Redmond, database guy @coderoshi

Portland Basho Office Representing, Eric Redmond, database guy @coderoshi

George Reese @georegereese & James Urquhart @jamesurquhart

George Reese @georegereese & James Urquhart @jamesurquhart

George & James, when not at baseball games or thrashing some guitar do some distributed computing system things over at Enstratus. Both of these guys write some seriously solid material, so hit the google and do a search on these guys, then read their books & articles. Cheers guys, good to catch up!

Coder’s Vacation : Getting Some Names…

Actual Live Status of the NameFactory Project

One of the things I’ve started working on is a #PhatData (re: my renamed version of big data) sample. So far what I’ve created is a JavaScript Application that works something like this. (The actual build status is shown to the right here in the “build status” image)

Step #1: Continuous Integration

The first thing I did was setup a solid node.js project that works on Travis CI (Continuous Integration). This is a pretty quick process. First create a directory and add an appropriate .gitignore and README.md file.

$ mkdir NameFactory
$ cd NameFactory/
$ git init
Initialized empty Git repository in /Users/adron/coderz/NameFactory/.git/
$ git remote add origin git@github.com:Adron/NameFactory.git
$ mate README.md
$ mate .gitignore

The mate command is merely textmate, use whatever you’d like though to create the files. I also use Sublime 2 and other things, textmate just happens to be the poison I often choose from the command line. The .gitignore has the following to take care of WebStorm and other files that might pop up.

*.idea
.idea
idea
.DS_Store
*.DS_Store

lib-cov
*.seed
*.log
*.csv
*.dat
*.out
*.pid
*.gz

pids
logs
results

node_modules
npm-debug.log

The README.md I just put the following in. You don’t really need this, but I’m showing you what should be put in a minimal project. In addition to being a good practice, we’ll need the README.md file for plugging in Travis CI in a few steps.

Name Factory
===
Description: This is JavaScript Node.js Project for generating random names.

Commit those files.

$ git add -A
$ git commit -m 'Adding gitignore and README.md.'
[master (root-commit) 14b1cf8] Adding gitignore and README.md.
 2 files changed, 23 insertions(+)
 create mode 100644 .gitignore
 create mode 100644 README.md
$

Once that is added there are some other files needed for Travis CI that I’ll add before flipping on the actual CI project on the Travis CI Website. First add a .travis.yml file to the project.

language: node_js

# test on two node.js versions: 0.6 and 0.8
node_js:
  -- 0.6
  -- 0.8

The packages file should look like this.

{
  "author": "Adron Hall <adronhall@gmail.com>",
  "name": "NameFactory",
  "description": "A library that creates randomly generated names for insert into various databases.",
  "version": "0.0.1",
  "homepage": "https://github.com/Adron/NameFactory/wiki&quot;,
  "main": "./lib/names",
  "repository": {
    "type": "git",
    "url": "git@github.com:Adron/NameFactory.git"
  },
  "scripts": {
    "test": "vows --spec"
  },
  "engines": {
    "node": ">= 0.4"
  },
  "dependencies": {},
  "devDependencies": {
    "vows": "0.6.x"
  }
}

At this point add a few tests that you know pass. I added the following examples from the vows site (this is the default example on the site).

var vows = require('vows'),
    assert = require('assert');

// Create a Test Suite
vows.describe('Division by Zero').addBatch({
    'when dividing a number by zero': {
        topic: function () { return 42 / 0 },

        'we get Infinity': function (topic) {
            assert.equal (topic, Infinity);
        }
    },
    'but when dividing zero by zero': {
        topic: function () { return 0 / 0 },

        'we get a value which': {
            'is not a number': function (topic) {
                assert.isNaN (topic);
            },
            'is not equal to itself': function (topic) {
                assert.notEqual (topic, topic);
            }
        }
    }
}).run();

…now make sure the tests run ok…

$ node test/names_object_should_exist.js
··· ✓ OK » 3 honored (0.003s)
$

So that’ll get the continuous integration via Travis-CI for NameFactory up and running, with a Github NameFactory Repository that is ready for the name generation code to be added. For my next blog entry I’ll leap into some generation strategies, dig up some good name lists (if you know of any, leave a comment w/ a link), and work on figuring out the fastest way to generate names.

Once that’s done, it’s time to setup some distributed databases. Shout it

Coder’s Vacation : #RICON2012 Shreds the House!

Here I am on day #3 of my Coder’s Vacation and RICON is happening today. This is a new conference put together by the fine folks at Basho, maker of Riak (which note, is a link to the project on Github because Basho is awesome like that, they roll all open source like). However, it’s a little different and way more honest than most conferences put on by a company. Sure, there’s talk about Basho and Riak and such, but overall the conference is about distributed systems. The byline of the conference, “A Distributed Systems Conference for Developers” is not a lie. It’s hard core about systems, data and getting things built by and for people who have ideas and know about how to put these things together. To summarize RICON in one phrase, it is “BAD ASS!” Hit up the #ricon2012 twitter stream for more on this.

Conference Kick Off:

Don Rippert of Basho (CEO) took the stage and brought up one of those points, that many in the industry take for granted, but it is rarely spoke. He pointed out, and I’m paraphrasing here, that the cloud, cloud computing, nosql and all these other things really amount to one giant shift i computing. That giant shift is a move to a better way combining things together through distributed systems. Simply put focusing on nosql or cloud or whatever word that marketing and the media latches onto is just a distraction. The real focus comes down to distributed systems. Sometimes, the smartest thing to state is the obvious thing, because nobody else is pointing it out. That simple thing brings about a greater realization of what is important versus what is just noise.

That leaves me with the question though, are we as an industry starting to get it? I think that’s a good question.

Joseph Hellerstein, Professor, UC Berkeley

…with a little about him from the RICON site:

Joseph M. Hellerstein is a Chancellor’s Professor of Computer Science at the University of California, Berkeley, whose work focuses on data-centric systems and the way they drive computing. He is an ACM Fellow, an Alfred P. Sloan Research Fellow and the recipient of two ACM-SIGMOD “Test of Time” awards for his research. In 2010, Fortune Magazine included him in their list of 50 smartest people in technology, and MIT’s Technology Review magazine included his Bloom language for cloud computing on their TR10 list of the 10 technologies “most likely to change our world”. A past research lab director for Intel, Hellerstein maintains an active role in the high tech industry, currently serving on the technical advisory boards of a number of computing and Internet companies including EMC, SurveyMonkey, Platfora and Captricity.

I also really enjoyed his talk. He took a correlation between distributed systems, data and the British Empire. Correlating things, especially complex and advanced things to something like the British Empire just adds an entertaining twist to it all. Again, a description from the RICON 2012 Site:

Conventional distributed systems wisdom dictates that perfect consistency is too expensive to guarantee in general, and consistency mechanisms—if you use them at all—should be reserved for infrequent, small-scale, mission-critical tasks. Like most design maxims, these ideas are not so easy to translate into practice; all kinds of unavoidable tactical questions pop up, e.g.:

– Exactly where in my multifaceted system is loose consistency “good enough” to meet application needs?

– How do I know that my “mission-critical” software isn’t tainted by my “best effort” components?

– How do I ensure that my design maxims are maintained as software and developer teams evolve?

Until recently, answers to these questions have been more a matter of folklore than mathematics. (One way to tell the difference: a good answer is enforceable by a compiler.)

In this talk, I will describe the CALM Theorem that links Consistency And Logical Monotonicity, and discuss how it can inform distributed software development. I’ll also give a taste of Bloom, a “disorderly” distributed programming language whose compiler can automatically answer questions like the ones above. Along the way, I’ll try to shed light on side questions like “Should Paxos exist?” and “Causality: What is it good for?”

More updates, and the code for my #PhatData Project are coming up. So subscribe, stay tuned, keep reading it’ll be up soon. Cheers!