Thrashing Code Metal Monday for Week of February 6th, 2017

This is the first of many of a series that is starting today. Thrashing Code Metal Monday’s picks for heavy tunes to code to. Ya know, if you can handle it.

With that introduction, may the thrashing code begin!

Top 3 for Spotify

https://embed.spotify.com/follow/1/?uri=spotify%3Aartist%3A5ctFffJBdJe8PZL7W7NeML&size=detail&theme=dark https://embed.spotify.com/follow/1/?uri=spotify%3Aartist%3A67ZMMtA88DDO0gTuRrzGjn&size=detail&theme=darkhttps://embed.spotify.com/follow/1/?uri=spotify%3Aartist%3A3dnH7fdVm2X07MK6Fkbhbt&size=detail&theme=dark

Top 3 Videos for Youtube

Data Diluvium Design Ideas

This post includes a collection of my thoughts on design and architecture of a data generation service project I’ve started called Data Diluvium. I’m very open to changes, new ideas, or completely different paradigms around these plans altogether. You can jump into the conversation thread. What kind of data do you often need? What systems do you want it inserted into?

Breakdown of Article Ideas:

  • Collected Systems API – This API service idea revolves around a request that accepts a schema type for a particular database type, an export source for inserting the data into, and generating an amount of data per the requested amount. The response then initiates that data generation, while responding with a received message and confirmation based on what it has received.
  • Individual Request API – This API service idea (thanks to Dave Curylo for this one, posted in the thread) revolves around the generation of data, requested at end points for a particular type of random data generation.

Alright, time to dive deeper into each of these.

Collected Systems APIs

  • https://datadiluvium.com/schema/generate – This API end point would take a schema with the various properties needed. For any that aren’t set, a default would be set. The generation process would then randomize, generate, and insert this data into any destination source specified. Here are some prospective examples I’ve created:

    A very basic sample JSON schema

    [
      {
        "schema": "relational",
        "database": "text"
      }
    ]
    

    In this particular example, I’ve created the simplist schema that could be sent into the service. For this particular situation I’d have (currently not decided yet) defaults that would randomly create a table, with a single column, and generate one element of data in that table. Other properties could be set, which would give control over the structure created in which to insert the data into. An example would be the following.

    [
      {
        "schema": "relational",
        "database": "postgresql",
        "structure": [
          {
            "table": "Users",
            "columns": [
              {"name": "id", "type": "uuid"},
              {"name": "firstname", "type": "firstname"},
              {"name": "lastname", "type": "lastname"},
              {"name": "email_address", "type": "email"}
            ]
          },
          {
            "table": "Addresses",
            "columns": [
              {"name": "id", "type": "uuid"},
              {"name": "street", "type": "address"},
              {"name": "city", "type": "city"},
              {"name": "state", "type": "state"},
              {"name": "postalcode", "type": "zip"}
            ]
          },
          {
            "table": "Transactions",
            "columns": [
              { "name": "id", "type": "uuid" },
              { "name": "transaction", "type": "money" },
              { "name": "stamp", "type": "date" }
            ]
          }
        ]
      }
    ]
    

    In this example, the properties included are three tables; Users, Addresses, and Transactions. In the first table, Users, the columsn would be; id, firstname, lastname, and email_address. Each of these then have a type property which sets the type of data to be generated for the columns. The same type of set of properties is then included for the Addressesand Transactions tables and their respective columns.

    Some additional questions remain, such as if the tables exist in the database, would the insertion build SQL to create the tables? Should it be assumed that the tables exist already and have the appropriate settings set to insert the data into the tables? Again, a great thing to discuss on the thread here.

  • https://datadiluvium.com/schema/validate – This could be used to validate a schema request body. Simply submit a schema and a validation response would be returned with “Valid” or “Invalid”. In the case of an invalid response, a list of prospective and known errors would be returned.

These two API end points focus around building out large data to test systemic environments and the respective construction of those environments. The actual generation of the data is assumed for this API service and the individual generation of data is discussed below in the individual request APIs.

Individual Request APIs

The following API calls could be implemented with fairly straight forward random data generation. A number can easily be randomized and returned, a word can be chosen from a dictionary, and a city returned from a list of cities. The following are prospective API calls to return data of this type.

The next level of complexity for data generation would be the slightly structured data generation. Instead of having an arbitrary list of addresses, we could or would prospectively generate one. But on the other hand, maybe we should just randomly create actual addresses that can be validated against an actual real address? That seems to have the possiblity of issues in the real world in spite of the fact all the addresses out there in the world are basically publicly accessible data. But questioning how or what the data would or could actually represent will be a great thing to discuss in the thread.

The next level of data generation complexity would be to generate sentences and other related data. This could be done a number of ways. If we wanted to have it generate intelligent sentences that made sense, it would take a little bit more work then for example generating lorum ipsum.

TLDR;

This blog entry just details the starting point of features for the Data Diluvium Project. If you’d like to jump into the project too, let me know. I’m generally working on the project during the weekends and a little during the week. There’s already a building project base that I’m starting with. If you’re interested in writing some F#, check out the work Dave Curylo has done here. I’ve been pondering breaking it out to another project and sticking to the idea of microservice but with F# for the work he put in. Anyway if you’ve got ideas on how to generate data, how you’d like to use it in your applications, or other related ideas please dive into the conversation on the Github Thread here.

The Data Diluvium, Getting Started

Welcome to the first of more than a few blog entries on Data Diluvium. Data Diluvium is a project I’ve started focused around generating data for the purposes of testing, capacity, or whatever other needs might arise.

Definition of data

  1. : factual information (as measurements or statistics) used as a basis for reasoning, discussion, or calculation
  2. : information output by a sensing device or organ that includes both useful and irrelevant or redundant information and must be processed to be meaningful
  3. : information in numerical form that can be digitally transmitted or processed

Definition of deluge which is the English version of the latin diluvium.

  1. a : an overflowing of the land by water. b : a drenching rain “a deluge causing mudslides in the area”.
  2. : an overwhelming amount or number

…thus Data Diluvium.

The idea is to build a data generation service. Something that will generate random data in usable chunks; name generation, addresses, and related data. To get a wide range of use out of this capability I needed to build a web service application and a respective CLI (Command Line Interface) to go along with the web application.

A Microservice is Born!

The web service is going to generate pseudo-random data around name, addresses, phone numbers, and location. Over the course of this series I’ll add more data generation types and implement a schema for the actual data generation. This web service will be created based on microservice architectural and design ideas. However in the early stages of this effort I’ll keep it simple and will stick to implementing a minimally viable product (MVP). From here on out I’ll refer to this project as the Data Diluvium project.

Microservice Client CLI

For the client side, I want to provide a CLI in which to interface with the microservice itself. With this CLI I want to be able to provide basic configuration or passed parameters that will allow me to take the generated data and pass it directly into terminal output, out to a file, or prospectively as things develop directly into databases of various kinds themselves.

The Tooling & Language

Overall this could be built in a number of technology stacks. I could use Node.js, .NET, Java, Erlang, or Go to build both the CLI and the microservice. With the multitude of choices it can be somewhat difficult picking the right stack to get things done as quickly, efficiently, well organized, and cleanly as possible. For this particular effort I’m going to go with Go to implement the microservice and the CLI.

Why Go you might ask? For the CLI, I’d want a cleanly built, fast, and responsive CLI that I can setup on any machine with minimal fuss. For Node.js for instance, one doesn’t get a built executable, but instead a kind of morass of tooling, and preinstallation software required. For Java and .NET one ends up with a great array of tooling to build a microservice and CLI, but the knowledge and time just to setup the initial development environments leads me away from those. With Erlang, maybe a day in the future, since it is indeed hugely and almost mystically powerful (yes, I just wrote mystically, it sounds appropriate).

Kick Off

First things first, I need the projects themselves. Here are the steps I took to get some basic parts building together for the two projects. The first step was simply to create two directories for each of these projects, one I named Data Diluviumand one Colligere. Inside both of those directories I put together a basic structure for each of these folders.

Basic Project Files

The frame of each included the following:

  • I created a folder titled .github and placed the following files: CONTRIBUTING.md, ISSUE_TEMPLATE.md, and PULL_REQUEST.md.
  • Next the standard .gitignore file with the following contents. This is the basic file Github starts a Go project with if selected during the creation of the repository. It has the minor addition of .DS_Store to keep that OS-X file out of the repository and the .idea director to keep out the IntelliJ, WebStorm, or Goland IDE (or any Jetbrains IDE) settings directory.
# Compiled Object files, Static and Dynamic libs (Shared Objects)
*.o
*.a
*.so

# Folders
_obj
_test

# Architecture specific extensions/prefixes
*.[568vq]
[568vq].out

*.cgo1.go
*.cgo2.c
_cgo_defun.c
_cgo_gotypes.go
_cgo_export.*

_testmain.go

*.exe
*.test
*.prof

.DS_Store
.idea
  • I added the LICENSE file with the standard Apache 2.0 license legalese.
  • Finally the README.md.

Build Files

It is important at this stage to create a build and get that build passing with some basic element of code. At this point I need some basic executing code and the respective build configuration files. For this I’ll create three files and name them respectively: main.go, codeship-steps.yml, and codeship-services.yml. In addition to the code, since I was going to be pulling in dependencies I’d need something to handle that, which I went ahead and chose glide.

I installed glide with the following commands on my OS-X machine, but since I am doing a lot of development on my new Leopard WS machine I installed glide with the curl command below.

Install with brew.

brew update
brew install glide

The curl installation step.

curl https://glide.sh/get | sh

With glide installed I ran the default initialization command glide create to get a glide.yaml and glide.lock file setup. Running this command will display the following via the CLI.

$ glide create
[INFO]  Generating a YAML configuration file and guessing the dependencies
[INFO]  Attempting to import from other package managers (use --skip-import to skip)
[INFO]  Scanning code to look for dependencies
[INFO]  --> Found reference to github.com/Masterminds/semver
[INFO]  --> Found reference to github.com/Masterminds/vcs
[INFO]  --> Found reference to github.com/codegangsta/cli
[INFO]  --> Found reference to gopkg.in/yaml.v2
[INFO]  Writing configuration file (glide.yaml)
[INFO]  Would you like Glide to help you find ways to improve your glide.yaml configuration?
[INFO]  If you want to revisit this step you can use the config-wizard command at any time.
[INFO]  Yes (Y) or No (N)?
n
[INFO]  You can now edit the glide.yaml file. Consider:
[INFO]  --> Using versions and ranges. See https://glide.sh/docs/versions/
[INFO]  --> Adding additional metadata. See https://glide.sh/docs/glide.yaml/
[INFO]  --> Running the config-wizard command to improve the versions in your configuration

I then ran glide get github.com/icrowley/fake to get the fake library I would need. The glide.yaml and glide.lock looked like this after I pulled in this library.

glide.yaml

package: github.com/adron/datadiluvium
import:
- package: github.com/icrowley/fake

glide.lock

hash: 2fd78ca8369405d5998e65ea4cfce94c6599e878c36fec39b85fd385552392d7
updated: 2017-01-09T01:04:18.134993358-08:00
imports:
- name: github.com/icrowley/fake
  version: 84bff6d01560fb0b5a396ba29534e93fd00d09c6
testImports: []

If you’re curious about the hash, and related properties of this file check out the glide README.md, it’s useful in understanding what’s stored here.

At this point, it was time to actually sling some Go code! At this point, I do indeed mean sling some too. Splat!

Some Go Code

In the main.go file I wrote some basic Go code just to have something to build. I wanted a little bit more than just a Hello World! code sample so I added a little bit more. I did some research and found the Fake library written by Dmitry Afanasyev from Ulyanovsk, Russia. I used Go get to pull that into the project and then added an import after package main with the various bits of code I’d want for my getting started code.

package main

import (
    "encoding/json"
    "fmt"
    "io/ioutil"
    "os"
    "github.com/icrowley/fake"
    "time"
)

The other libraries I knew I would need for various other output, date stamps, and other library features I’d want. Then I went to coding, my first sample of working code to prove out key functionality of the libraries looked like this.

type Page struct {
    Title string `json:"title"`
    Schema   string `json:"schema"`
}

func (p Page) toString() string {
    return toJson(p)
}

func toJson(p interface{}) string {
    bytes, err := json.Marshal(p)
    if err != nil {
        fmt.Println(err.Error())
        os.Exit(1)
    }
    return string(bytes)
}

func main() {
    pages := getPages()
    for _, p := range pages {
        fmt.Println(p.toString())
    }

    fmt.Println(toJson(pages))

    fmt.Println("\nSome Russian Random Data")
    fake.SetLang("ru")
    fmt.Println(fake.FirstName())
    fmt.Println(fake.FullName())

    fmt.Println("\n\n\nSome English Random Data")
    fake.SetLang("en")
    fmt.Println(fake.FirstName())
    fmt.Println(fake.FullName())

    thisMany := 10
    counter := 1
    t := time.Now().Format(time.RFC850)

    fmt.Println("\n\n\nPrinting", thisMany)

      for i := 0; i < thisMany; i++ {
      fmt.Println(counter, fake.FirstName())
      counter += 1
      fake.FirstName()
      }

    fmt.Println("Start Time: ", t)
    t = time.Now().Format(time.RFC850)
    fmt.Println("End Time: ", t)
}

func getPages() []Page {
    raw, err := ioutil.ReadFile("./deluge.json")
    if err != nil {
        fmt.Println(err.Error())
        os.Exit(1)
    }

    var c []Page
    json.Unmarshal(raw, &c)
    return c
}

Now, this all was a small mess at this point. I know I needed to get it cleaned up. However the priority at this point is to get a build working that will provide a trusted basis to continue work from. Since I intend to use this to teach, for everyday testing, and hopefully to gain contributors (want to help?) it needs to have a good build, end of story.

Continuous Integration Build

At this point I have the main.go file executing with some Go code that pulls together some functionality on random data generation, file I/O (at least reading) with a JSON file for config, and displaying this out the console. So far, so good.

I’ve decided to use Codeship for this particular project. They’re a service provider the specializes in continuous integration and delivery services, and I might add that they’re good at it (* Also note declarations, etc at the bottom of this blog entry).

Two significant reasons I like to use Codeship are: remote builds & deploys with Docker and local builds with Docker. Having that combination is very effective, providing the capability to effectively to builds that include systemic deployments to my own local machine in addition to combining efforts with a prospective team together via the remote build.

CI Service Setup at Codeship

To setup the repository on Codeship for Docker support I went through these steps.

First select create new project. This is up on the Select Project bar or if you’ve just signed up it is available as the default screen when navigating to builds. Codeship just added Gitlab as a repository option recently, which I opted for the Data Diluvium Client, Colligere, using Gitlab just to test it out. At this time I really like my experience with Gitlab, but that’s for another blog entry, for now, onward!
codeship01

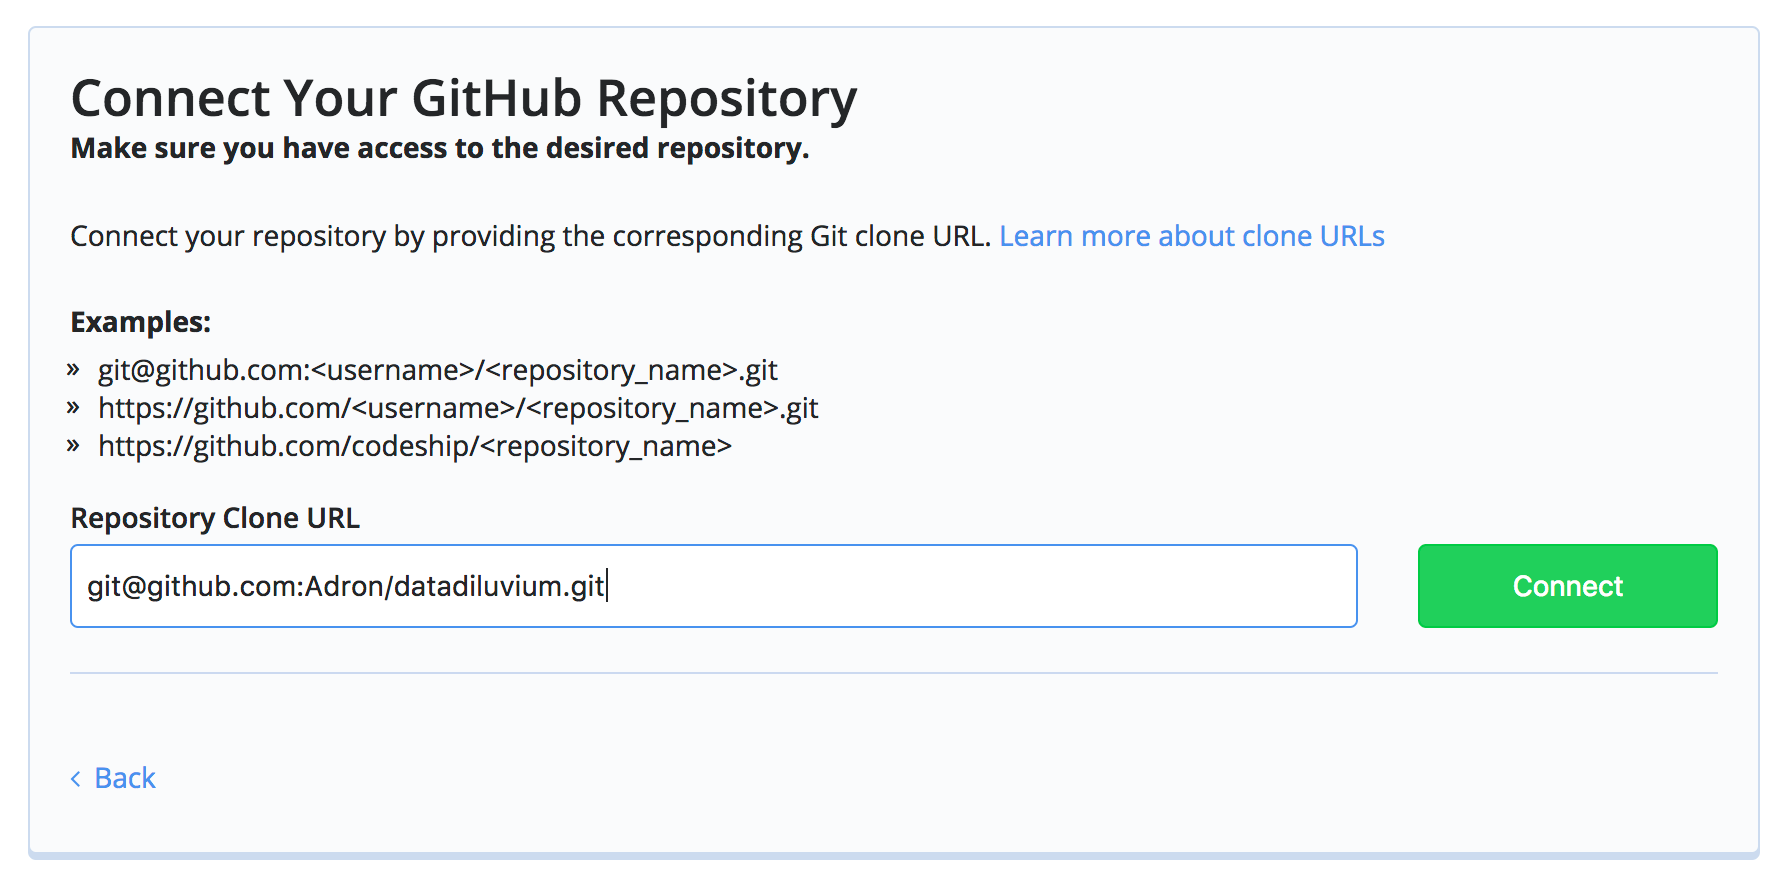
Next enter the path for the git repo.
codeship02

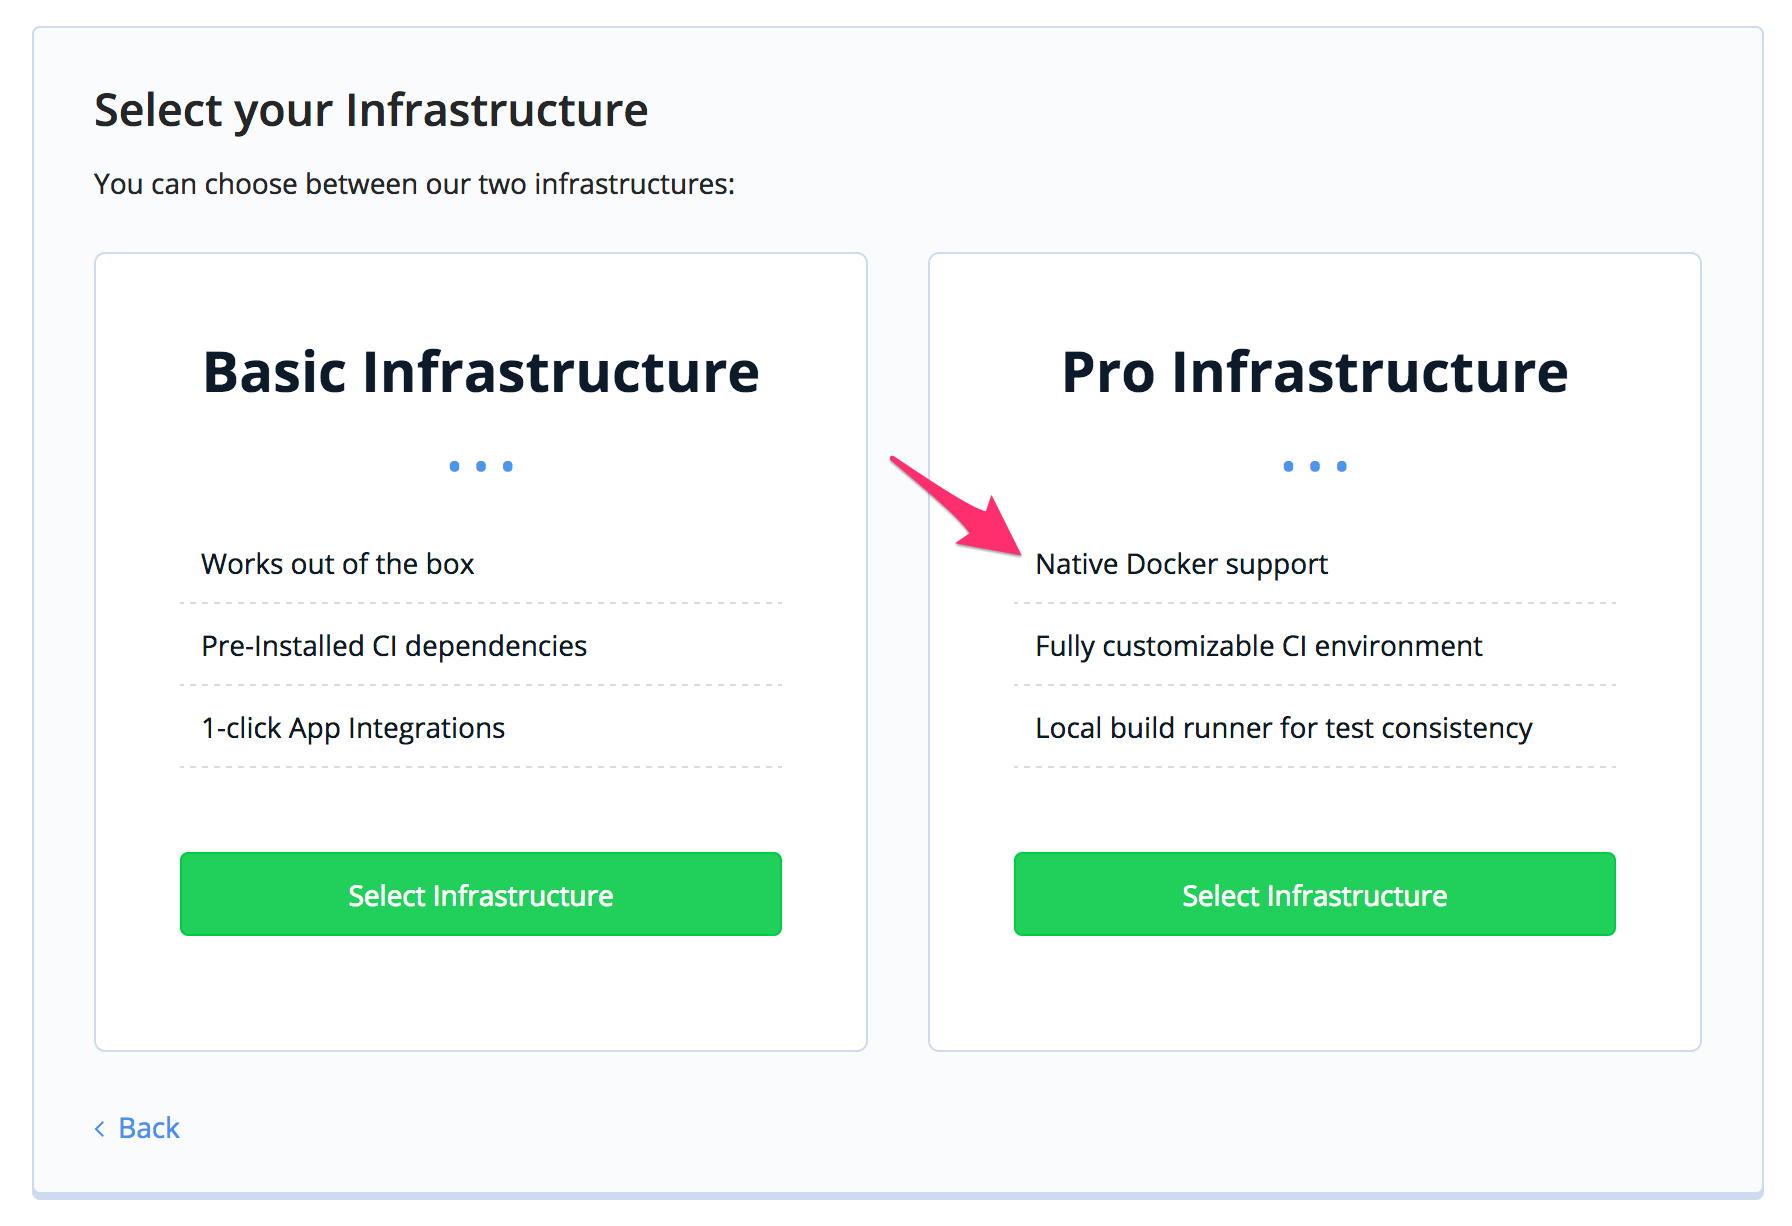
Select pro infrastructure. This will provide Docker capabilities.
codeship03

Then it is time to setup the Docker configuration and yaml files for the build. The page at this point on Codeship has some links and such, for the two yaml files needed, but I’ll describe them here in detail a bit. In the image below a quick review of each element of the page: (1), the project settings, which will navigate to an area to setup notification, configure and add team members, repository details or reconnecting to a different repository, and general settings, which can be navigated to via (2), and (3) lists the current project the settings are displaying and available for changing.

codeship

Once the build project is setup in Codeship there are two files that are needed in the repository itself. Both of these files are simple yaml files. Each are given a default name of codeship-steps.yaml and codeship-services.yaml.

The codeship-steps.yaml file has the following steps listed for this project. I’ve associated these to a service called deluge_svc which will be defined in the codeship-services.yaml file. Then the commands, in order, are go clean, go test ./..., and go build.

- name: deluge
  service: deluge_svc
  command: go clean
- name: deluge_tests
  service: deluge_svc
  command: go test ./...
- name: deluge_build
  service: deluge_svc
  command: go build

The next file is codeship-services.yaml and has the following contents.

deluge_svc:
  build:
    image: deluge
    dockerfile_path: Dockerfile

This simply gives the service a name, which in this case is deluge_svc and then points to which Docker image will be used and which Dockerfile will build that image. Here I’ve just placed Dockerfile as the file, and next will put together the Dockerfile.

Dockerfile

The Dockerfile I put together is based off of the official golang image, with the tag specific for the 1.7.4-alpine build. The Alpine build is basically a Linux image that is about ~10MB, maybe a little more or a little less depending on what needs to be added to the image to run the service.

In the case of the Data Diluvium App I’ve added a few things that will be needed in order to get the build working. The complete Dockerfile is below, but below that I’ll break out what is going on and what I needed to do to implement this Docker image to run as a container for the build (and by proxy any production use of the same image).

FROM golang:1.7.4-alpine

ENV GOPATH /go

RUN mkdir /app && \
    apk add --update curl && \
    rm -rf /var/cache/apk/*

ADD . /app/
WORKDIR /app
RUN apk update && apk upgrade && \
  apk add --no-cache git && \
  curl https://glide.sh/get | sh

RUN glide up && go get github.com/icrowley/fake && \
  go build
CMD ["/app/datadiluvium"]

The first part of the file sets the official golang image and immediately after that I set the actual $GOPATH environment variable on the image.

FROM golang:1.7.4-alpine

ENV GOPATH /go

Next, I install curl with Alpine’s apk and clear out the apk cache.

RUN mkdir /app && \
    apk add --update curl && \
    rm -rf /var/cache/apk/*

Next are some very specific steps, which I’m not sure really meet a good practice, but it’s what I needed to do in the moment to get things working. The first steps here is simply adding the app directory, then setting it as the WORKDIR. Next I update apk again and upgrade the cache before installing glide. I’m not sure if this is absolutely necessary but I was running into errors and things not executing until I broke apart this section from the aforementioned section.

ADD . /app/
WORKDIR /app
RUN apk update && apk upgrade && \
  apk add --no-cache git && \
  curl https://glide.sh/get | sh

With glide installed it was time to grab the dependencies for the Docker image with glide up and for some reason, even though it’s in the glide yaml file I still had to specifically call out the go get github.com/icrowley/fake library before executing the go build step.

UN glide up && go get github.com/icrowley/fake && \
  go build
CMD ["/app/datadiluvium"]

With that done, I could then finally run a build that encompassed all elements of what I’ve built so far. I did this simple with a jet steps command and realized I’d missed the steps needed to actually install the jet CLI. Since this first build I was working on, was actually on Ubuntu Linux, I followed these steps for getting the Jet CLI installed.

curl -SLO "https://s3.amazonaws.com/codeship-jet-releases/1.15.4/jet-linux_amd64_1.15.4.tar.gz"
sudo tar -xaC /usr/local/bin -f jet-linux_amd64_1.15.4.tar.gz
sudo chmod +x /usr/local/bin/jet

However there is a brew cask that can be used to install jet with too. It’s a one line command.

brew cask install jet

Ok, that should get those following along with a running build too. There is of course the prereq of having git and docker installed too, I’ll admit I keep making the mistake of assuming those things are installed everywhere. So if you hit a hiccup at this point, it may be because those two things need installed – which likely will have caused errors far before this.

With jet steps running the build locally, I can now navigate to Codeship and check out the build when I commit all of this work.

git add -A
git commit -m 'First code all wrapped up.'
git push origin master

…and that’s it for this entry. Hope that’s useful for getting your own Go project started. If you’re interested, definitely ping me if you’d like to work on Data Diluvium some too. I’m looking for help.

Cheers! -Adron

Declarations & References

  • Codeship – I’ve worked for Codeship providing technical writing and good coding fun with the crew there. They’re not currently paying me, but I will likely do more work for them, so take that into account when judging my judgement of their products. As always, I’m not into any shill work and wanted you dear reader, to have full clarity into my use of the tech. Cheerio!
  • Collected Links – Codeship, Data Diluvium, Data Diluvium Github Project, Colligere.
Buying a Leopard!

system76-smallJanuary 24th, 2017 UPDATE: After I wrote this, I spoke with the System 76 team and I’m getting the chance to go out and tour their Denver Headquarters. This happened well after I made my purchase, which all of the following was written after. But just for full transparency, I’ve added this note. Also, I’m aiming to get a full write up of my System76 trip put together with Denver tidbits and more! Until then, here’s the review…
In the trailing days of 2016, after having moved to Redmond, Washington I sat working at my desktop workstation. This workstation, which still exists, is a iMac with an i7, 16GB RAM, 256 GB SSD, and a 1GB Video Card with a 1TB secondary drive. The machine is a 27” all in one style design, and the screen is rather beautiful. But as I did a build and tried to run Transport Tycoon at the same time in the background the machine sputtered a bit. It was definitely maxed out doing this Go code build, putting together a Docker image build, and spinning it up for go live at the same time my game ran in the background. I thought, this machine has served me extremely well, at over 5 years old it had surpassed the standard 5 year lifespan of peak Apple oomf. At the moment, I thought, maybe it’s time to dig into a serious machine with some premium hardware again.

In that moment I thought about the last dedicated, custom built, super powerful workstation machine I had. It was a powerful machine, nice form factor, and easily drove two giant 27” screens. However this machine had lived and finished it’s useful life over 6 years before 2016 had even started. But it was a sweet machine, that offered a lot of productive gaming and code writing efficiencies. It was thus, time to get in gear and get a machine again.

Immediately I thought through a few of the key features I wanted and other prerequisites of purchase.

  1. Enough RAM and processor power to drive my aforementioned gaming, docker, and code building scenario with ease.
  2. SSD drive of at least 1TB with at least a beefy 8GB Video Card.
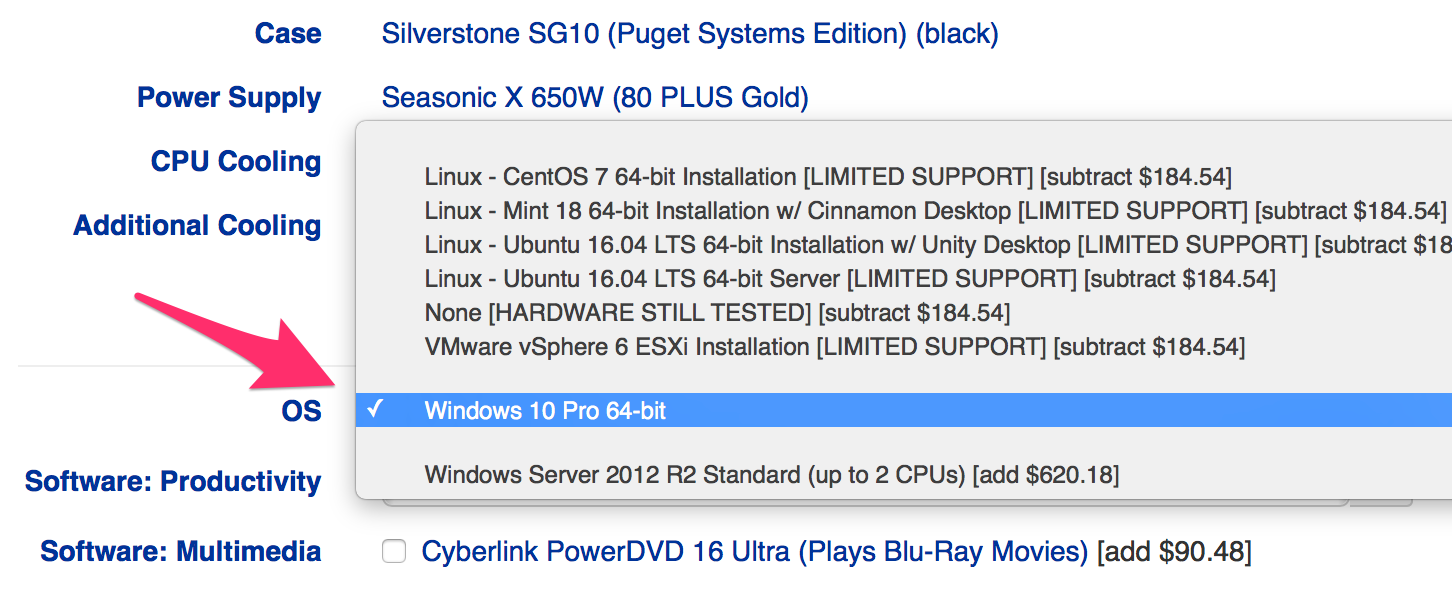
  3. It needed to run, with full support, not-Windows. Ubuntu would be fine, but if any Linux was installed from factory or at least fully supported on the hardware I put together, that would suffice.
  4. If I were to buy it from a company, it had to be a company that wasn’t some myopic afterthought of 50s era suburbia (i.e. I didn’t really want to deal with Dell or Alienware again after the XPS 13 situation). This definitely narrowed down the options.

I started digging into hardware specifications and looking into form factors, cases, and all the various parts I’d need for a solid machine. In parallel I started checking out several companies.

  • System76 – Located in Denver, I was curious about this company and had been following them for some time. I had seen a few of the laptops over the years but had never seen or used any of their desktops.
  • Los Alamos Computers which is now LAC Portland! – Holy smokes, I had not realized this company moved. They definitely meet the 4th criteria above.
  • Puget Systems is a company located somewhere in the Puget Sound area and used to be called Puget Sound Systems. After digging I found they are located in a suburb of Seattle, in a town called Auburn. I didn’t want to rule them out so I kept them on the list and started researching.
  • Penguin Computing is another one of the companies, and kidn of a mainstay of Linux machines. They were a must have in the run up.
  • Think Penguin is another I dove into.
  • Emperor Linux is another company I found specializing in Linux machines.
  • Zareason was another, that specialized in Linux machines.

First Decision > Build or Buy?

I wrangled hardware specifications and the idea of building my own machine for some time. I came to the conclusion that the time versus money investment for me was on the side of buying a built machine. This first decision was pretty easy, but educating myself on the latest hardware was eye opening and a lot of fun. In the end however, better to let a builder get it done right instead of me creating a catastrophe for myself and nuking a whole weekend!

Decision Buy!

Second Decision > Who should I buy from?

I dug through each of the computer builders previously mentioned. I scouted out where they were located, what the general process was they used to build the machines, what testing, what involvement in the community they have, and finally a cost and parts review.

Each of the builders has a lot of positives in regards to Linux, the only one that I was hesitant about at first in regards to Linux was Puget Computing. Because by default the machines come with Windows 10. However after asking around and reviewing other reviews online, I came to find they do have Linux and a solid skill set around Linux. Puget remained a leader in the selection process.

pugetsystems

I went through Los Alamos Computers, which I realized are now LAC Portland (Win for Portland!), then Penguin, Think Penguin, and Emperor Linux. All had great skills and ethos around Linux. LAC definitely had the preeminently preferable choice in physical location (I mean, I do love Portland!), but each were short in either their customer facing desktop options. Albeit for a company or other reason, I’d likely buy a Thinkpad or other computing platform running Linux from them. But for this scenario each were disqualified for my personal workstation.

The last two I started checking out were Zareason and System76. I had been following what System76 for a while and a few things had caught my eye on their site. It led me to realize that they’re located out of Denver. Being a transit nerd, one of their website video photo coffee shop scenes had the RTD Light Rail passing in the background. But all things aside I started checking out cases and hardware that each builder puts in a box.

  • Berkely BARTZareason had several cases as shown below. With each of these I checked out the hardware options.

  • SounderNext up I checked out a number of Puget Systems.

  • RTD Light RailNext I started looking at System76 machines.

Challenge: Extra nerd credit if you guess why I used each of those pictures for each of those companies!

After working through and reviewing prices, features, hardware, and options things were close. I started reviewing location and what I could derive about each company’s community involvement in Linux, how they’re involved locally, and what the word is about those companies in their respective communities. Out of the three, I ended up not finding any customers to talk to about Zareason. For Puget, I found one friend that had a box purchased from a few years ago, and for System76 I actually found 2 different feedback bits from users within an hour or so of diffing around.

Kenny Spence @tekjava – Kenny and I have known each other for more years than I’m going to count. We got to meetup here in Seattle recently and he showed me his System76 laptop. The build quality was good and the overall review he gave me was a +1. Before this he’d mentioned in Twitter DM convo that this was the case, and I’d taken his word for it back then.

Dev Shop X – A group of individuals I reached out to I had met 3 years ago at the Portland @OSBridge Conference. I spoke to them again and found they were still using the System76 machines with no real complaints. They’d also bought the XPS 13 laptops well before the model I did and had a few complaints. With a short conversation we ended with them offering a +1for System76.

With the reviews from trusted sources, seeing the involvement and related culture of System76 I decided that they would be the builder of choice.

Decision System76 Leopard WS!

Leopard Workstation

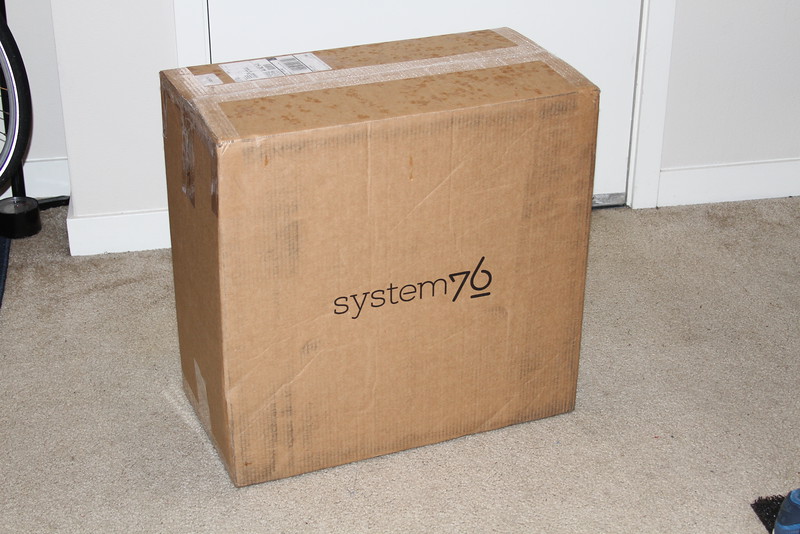
With the decision made, I pulled the trigger on the purchase. In spite of the holiday season, I still received the machine in short order. It arrived at my door via UPS in a box, ya know, like a computer does when its shipped somewhere. 😉

system76-leopard-01

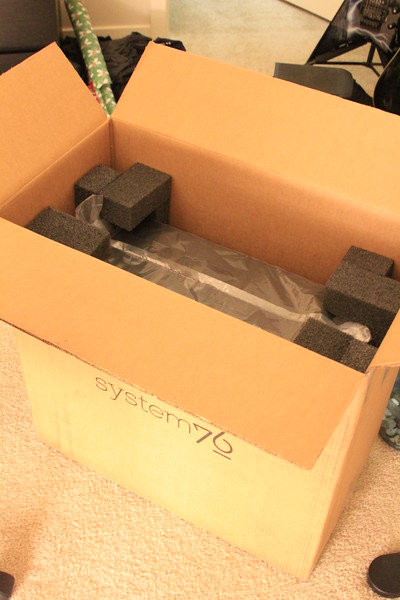
I cleared off the desk next, and dug into the box.

system76-leopard-02

system76-leopard-03

The computer was packaged cleanly and neatly with minimal waste compared to some I’ve seen. So far so good. I pulled pieces gently from the box. The first thing I extracted was the static bag which had all of the extra cords and respective attachments that had come with various parts of the computer hardware that were unnecessary. Another plus in my opinion, as many would likely not notice this having not built computers themselves, nor even cared, but I’m glad to have the extra pieces for this or other things I might need them for.

system76-leopard-04

The next thing I pulled out of the box was a thank you letter envelope with cool sticker and related swag.

system76-leopard-05

Stickers!

system76-leopard-07

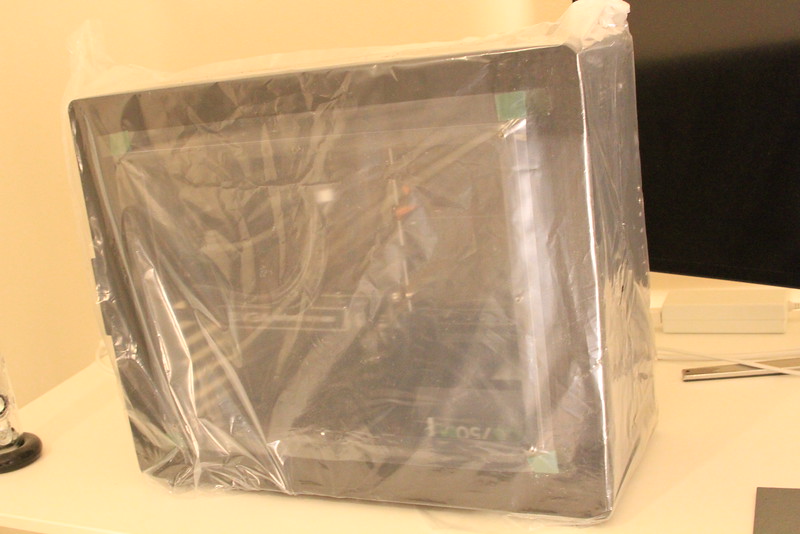
That was it for peripheral things just floating around in the box. Next, out came the computer itself.

system76-leopard-06

It was wrapped in a static free bag itself. As it should be. I did notice a strange ink like bit of dusted debris in and around the box. I’m not really sure, and still am not sure today what exactly it was. I cleaned it up immediately. It wasn’t excessive, but was leaving slight marks on the white table which required a little scrubbing to remove.

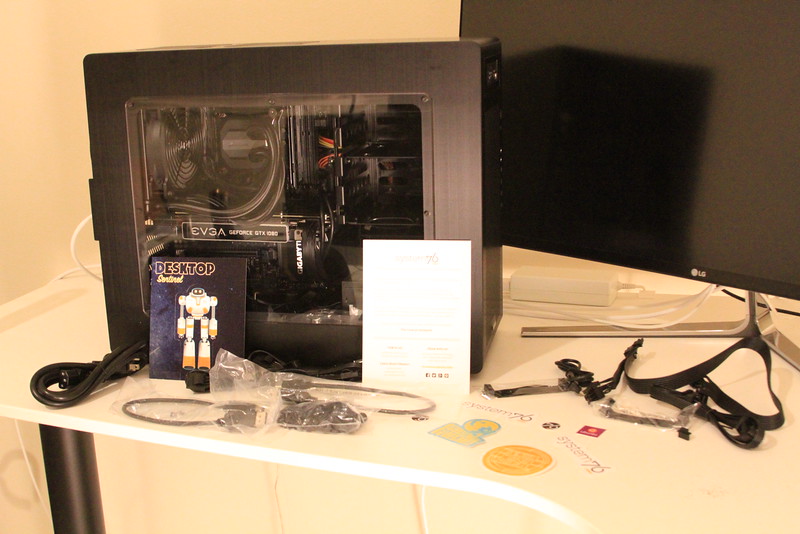
After all things were removed from the box I removed them from envelopes and static free bags and placed them on the desk for a simple shot of all the parts in the box.

system76-leopard-08

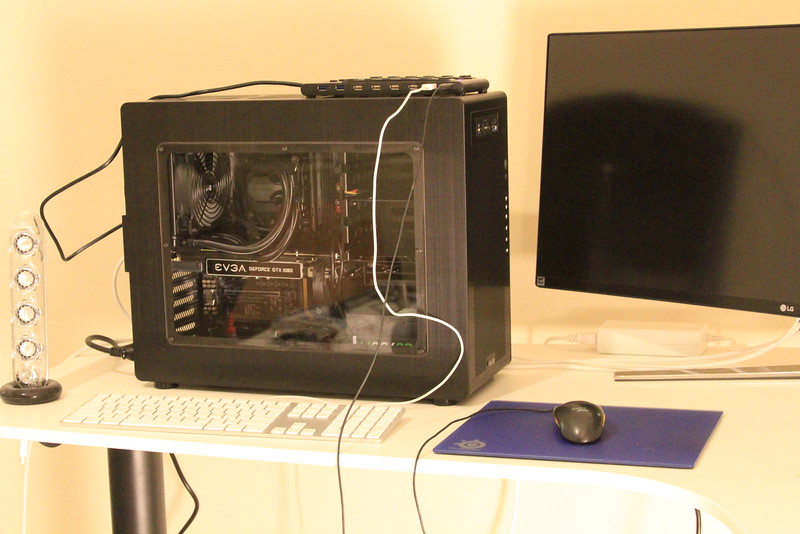
Next I went through the steps of desk cleanup again and then connected my 28 port USB Hub, Razor Mouse, and a keyboard to the machine. It was finally time to boot this machine up!

system76-leopard-09

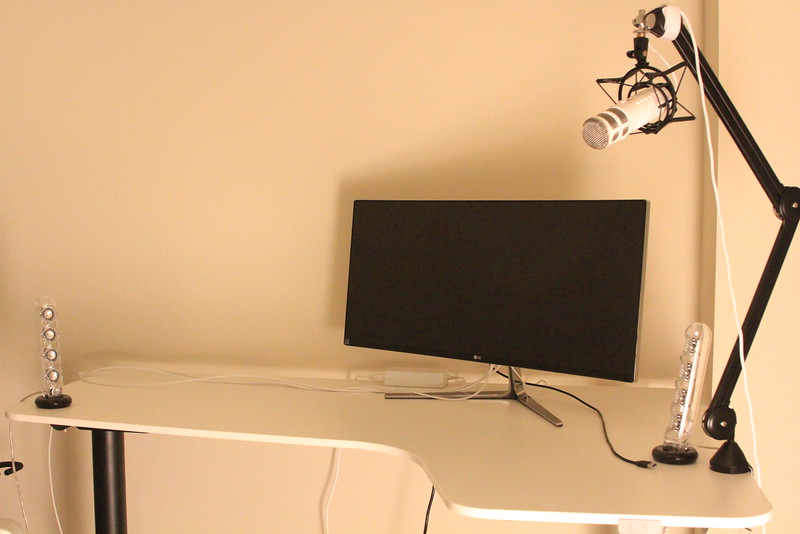
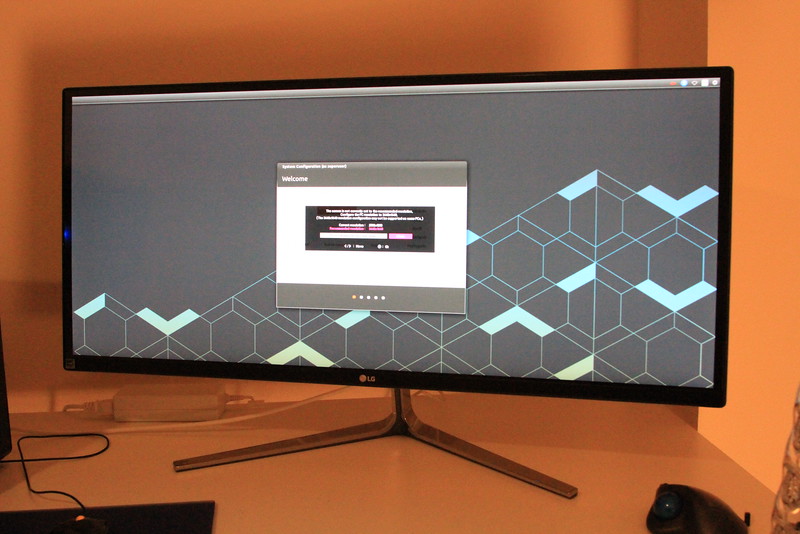
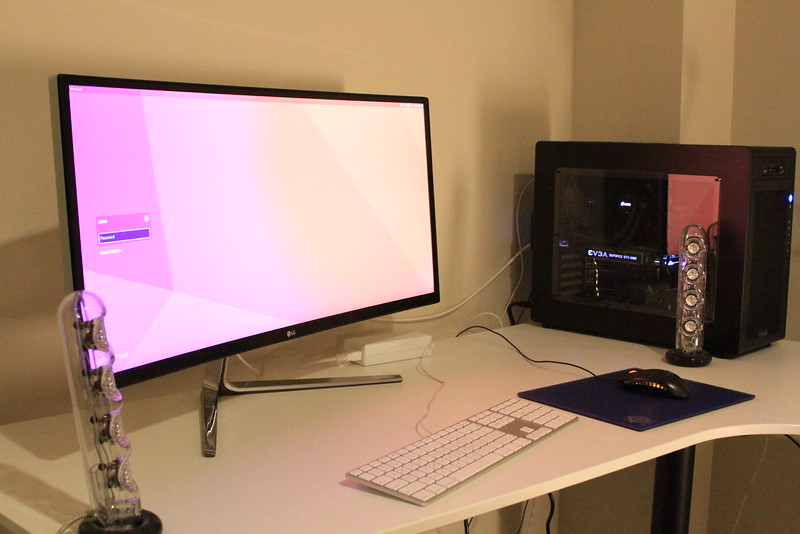
As for the screen which you see, it’s an LG 34” Extra Wide Screen monitor with slight curved view to it. Yes, it’s awesome, and yes it actually makes it relatively easy to not need dual monitors.

BOOTING!

system76-leopard-10

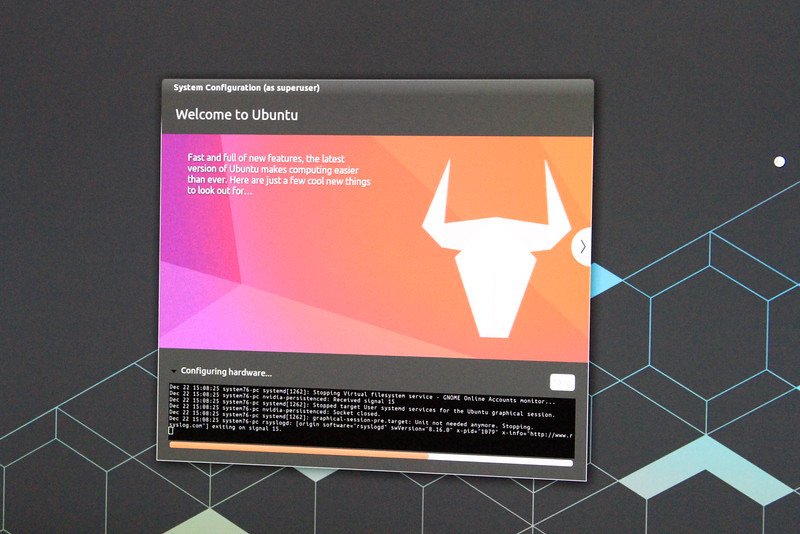
Ubuntu started, monitor fussing.

system76-leopard-11

I toyed around and had for whatever reason plugged in the HDMI, when I should have used the other monitor connection. It immediately provided more resolution options when I changed the connection and the monitor and related elements detected appropriately!

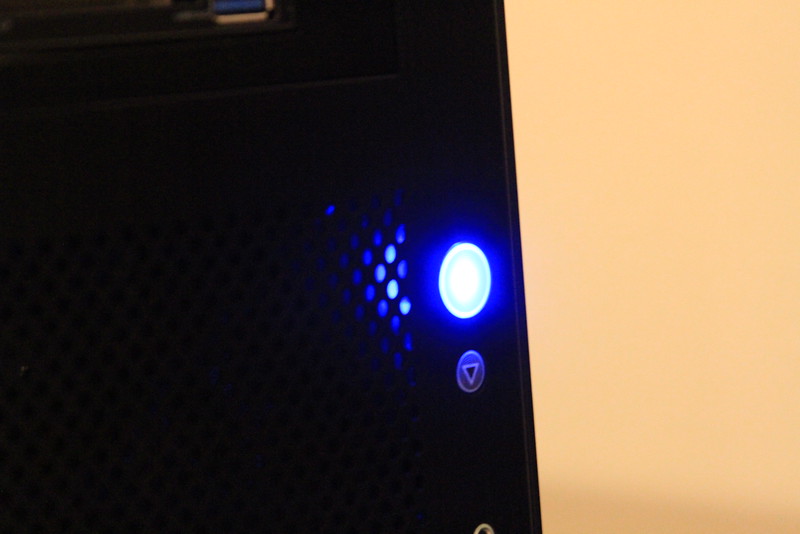
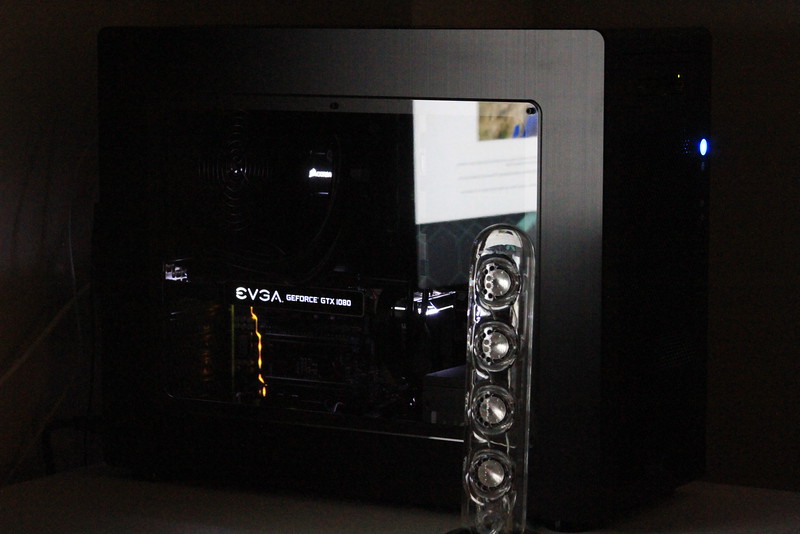
On the side of the machine is a clear window cut through the case to view the internals. The cords were managed well and overall build was very clean. Upon boot up the graphics card immediately lit up too. The nice blue tone provided a nice light within the room.

system76-leopard-12

Ubuntu booted up cleanly, and I might crazy bloody fast.

system76-leopard-13

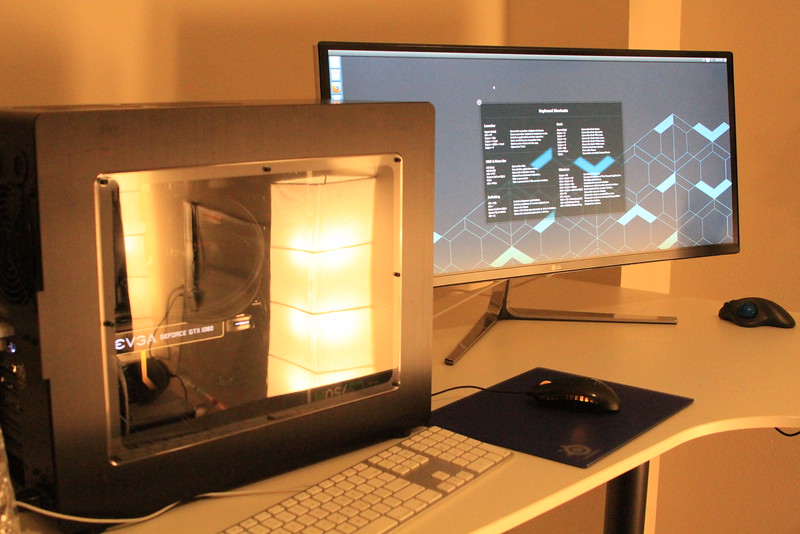
Here’s a non-flash shot of the machine and monitor side by side.

system76-leopard-14

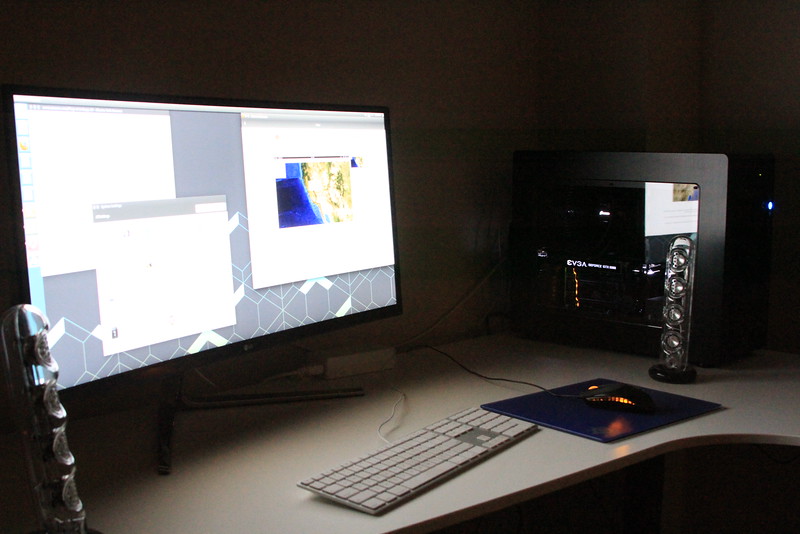
I then changed the respective positioning and the lighting, as you can see actually changed dramatically just by repositioning the hardware and the rear light I was shooting with.

system76-leopard-15

Lights off shot. The widow is beautiful!

system76-leopard-16

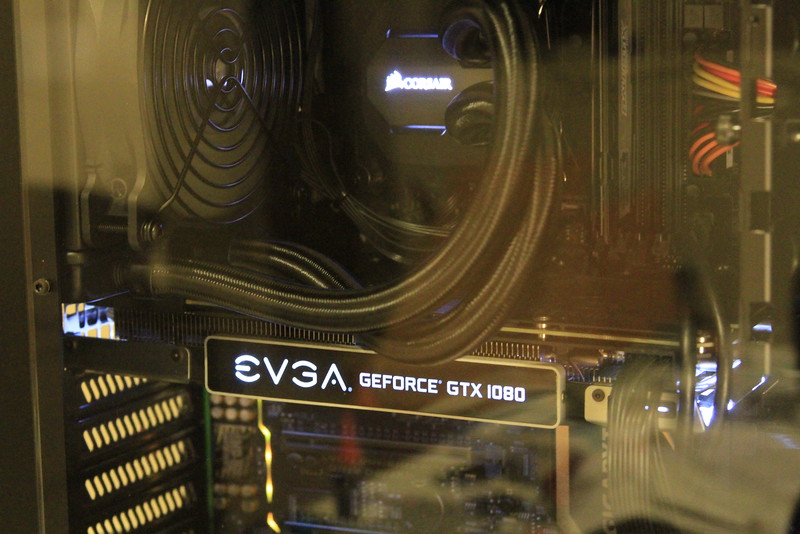
A slightly closer shot of the GTX 1080 humming away inside.

system76-leopard-17

The Ubuntu on Leopard WS Review

So far I’ve done a ton of coding & game playing on the machine. Here’s a break down of some specifics and some respective comments with a full read on the specifications of the machine.

  • Ubuntu 16.10 (64-bit)
  • 4.0 GHz i7-6850K (3.6 up to 4.0 GHz – 15 MB Cache – 6 Cores – 12 threads)
  • High Performance Self-Contained Liquid Cooler
  • 32 GB Quad Channel DDR4 at 2400MHz (2× 16 GB)
  • 8 GB GTX 1080 with 2560 CUDA Cores
  • Chipset Intel® X99
  • Front: 2× USB 3.0 Type-A, 1× USB 2.0 Type-A, 1× eSATA
  • Rear: 3× USB 3.0 Type-A, 1× USB 3.1 Type-A, 1× USB 3.1 Type-C, 4× USB 2.0, Type-A, 1× PS/2
  • Gigabit Ethernet, optional Intel® Wireless-AC (a/b/g/n/ac)
  • GTX 1080: DVI-D, HDMI, 3× Display Port
  • Audio Front: Headphone Jack, Mic Jack
  • Audio Rear: 8 channel (HDMI, S/PDIF), Mic Jack, Line In, Line Out
  • Power Supply 750 W 80+ Certified (80% or greater power efficiency)
  • Dimensions 15.8″ × 8.3″ × 19.5″ (40.13 × 21.08 × 49.53cm)

Gaming

Using Steam I downloaded several games including my latest addiction Transport Tycoon. The others included Warhammer 40k: Dawn of War, Stronghold 3, Stellaris, Sid Meier’s Civ V, Master of Orion, and Cities: Skylines. Each of these games I loaded up and played for at least 20-30 minutes, with every graphics detail maxed out and full audio feature enabled. Where the option existed to run it at full resolution of 3440×1440 I ran the game at that resolution.

Not a blip, stir, or flake out of any sort. The color was solid (which obviously is also largely the monitor) and being able to move around these games in their respective 3d worlds was exception. All the while the speed of elapsed time in games like Transport Tycoon and Cities: Skylines barely slowed at all no matter how massive the city or layout was.

At this point I’ve also added about 16 hours of Transport Tycoon play to this, and I’ve built absurdly extensive layouts (100s of trains plus massively grown cities) and this processor and video card handles it. The aforementioned previous desktop easily choked to 1/10th the speed of this beast while running the game.

More on the gaming elements of this machine in the coming days.

Coding

I used Jetbrains Toolbox to download IntelliJ, Webstorm, CLion, DataGrip, Project Rider, and RubyMine. I dug around for some sample projects and slung together some basic “hello world!” apps to build with each of the IDEs. All built at absurd rates, but nothing real specific as I didn’t load any large projects just yet.

One of the things I did do was load Go so that I could continue work on the Data Diluvium Project that I’ve started (Repo on Github). To hack around with Go I also installed Atom and Visual Studio Code. Both editors on this particular machine were screaming fast and with the 34” display, I could easily have both to test out features side by side. Albeit, that makes shortcut combos a nightmare! DON’T DO THIS AT HOME!

Build time for the C, Go, and C# Projects I tried out were all crazy fast, but I’m holding off posting any results as I want to get some more apples to apples comparisons put together before posting. I’m also aiming to post versus some other hardware just so there are some baselines in which to compare the build times against.

More on the coding and related projects in the coming days too.

Important Software

You may think, if you’re not an Ubuntu or Linux user, what about all the other stuff like office software and … big long list goes here. Well, most of the software that we use is either available or a comparable product is available on Linux these days. There’s really not many things that keep me – or would keep anybody tied to – OS-X/MacOS or Windows. Here are a few that I’ve tried out and am using regularly that are 1 to 1 across Windows, OS-X, and Linux.

  • Jetbrains – as mentioned before these work across all the platforms. They’re excellent developer tools.
  • Spotify – even though it states that there hasn’t been support or what not for the app for many months, it still works seemlessly on Linux. That’s what you get when you build an app for a solid platform – one doesn’t have to fix shit every week like on OS-X or Windows.
  • Slack – Slack is available on Linux too. After all the native app (or pseudo native) is built on Electron, which at its core runs on Node.js. So thus, feature parity is pretty much 100%. If you’re going to use slack, it’s not an excuse to be stuck on Windows or OS-X. The choice of platform is yours.

Summary

me-horns-up

NOTE: Nobody paid me a damned penny to write any of this btw, I reviewed all of these things because I love writing about my nerd adventures. No shill shit here. With that stated…

I have more things to review across all of these platforms and much more to write about this mean machine from System76. However, this review has gotten long enough. The TLDR; of this is, if you’re looking for a machine then System76 definitely gets the horns from me! Highly recommended!

Home Depot Wrap Up and Job Talk

First, I will be available with a possible start date of November the 28th. I’m currently wrapping up some big projects and completing training for the Home Depot Team and the great progress we’ve made over the last year. If your company is looking for someone with my mixed array of technical skills and soft skills, you can check out my resume & details and initiate job talk with me here!

On to the rest of the news. If you’ve seen me speak lately I’ve mentioned the open source efforts we’ve had going on at Home Depot and related efforts I was working on. Some I’m working dilligently to release via the Home Depot OSS Organization on Github and I’ll still be releasing others soon via my Github account (@Adron) and blogging about it here on Composite Code.

Since this is one of those rare times in my career where I’m not 100% sold on what I’ll do next, I’m open to fielding prospects and seeing what is out there. This is a different approach for me, as I usually determine a company, particular work that needs done and go after that gap. But I’d like to get a feel for what companies feel they need at this particular time. Since I have a wide range of skills, I can step into a number of positions and immediately start to contribute to projects within a company.

Here are some positions I’d find attractive and could provide value for (or build) a team immediately!

Building or Expanding a Team

Need someone to hire, build, and create a cohesive, diverse, and powerful culture of core contributors (developers, designers, advocates, evangelists, or similar). I can knock this one out of the park for the right company. Yes, I’m a bit particular, but I’m not just going to whimsically work for any company (the best people won’t work for just any old company anyway). If you are looking to put a team together and want somebody that can do that for you, I’d like to sit down to a conversation soon. Let’s talk jobs.

Coding Architect

Have some architecture problems, that seem a bit unique or problematic? If you need someone to come in and push forward on design, patterns, practices, and actual implementation then this would also be a conversation I’d be interested in having. I’d be happy to dive into whatever the stack might be (or help decide on the stack): Java (Scala/Kotlin), Golang, Node.js or even .NET (C#/F#) for the right company. Let’s talk jobs.

Development & Operations Architect

Have some architecture that needs to go along with an application and want to build or insure a solid continuous integration and delivery pipeline (or messaging based queue for delivery to production)? This is another possibility I’d be happy to talk about. I really love working with systems to build out reliable immutable infrastructure, data storage mechanisms (distributed, RDBMS, whatever the need calls for) and insure development can continue forward with extremely high confidence levels. [Let’s talk jobs](/contact/).

Developer Advocate/OSS Project Lead

If you have an open source project I’d love to take lead on it and also provide advocacy for that project. This role is not to be confused with evangelist, as that’s a fine role for other people, but I want to be in the code and advocating from a position with the team. I’ve done this before with projects like the Iron Foundry for Cloud Foundry and others, and loved it. [Let’s talk jobs](/contact/).

Mergers & Acquisition Technical Evaluations

This is not something one sees everyday, but I’ve worked in a consulting role and have assisted others with this work before. I find it really interesting looking at prospective ROI, current run rates, but also at the specific details of whehter a product or service can even be incorporated and integrated into the acquiring company. In the case of merging, this differs from acquisition in that both entities and both companies’ products and services will both need to polymorph into a new whole. If you’re company is looking to get into some M & A’s, let’s talk about how I can help.

If any of these sound like a need you have, please reach out with additional information and I will be in contact ASAP.

Besides the above theoretical jobs above, here are a few other things that I would like in a job. Things that just make it all worthwhile, here’s a list.

Work Environ / Soft Skills / Culture

  • Flexible hours remote or remote (out of office). Whatever the case, I’d like to work with a company that has the ability and acumen to manage the workflow and efforts among team members remotely. If you’re a company that wants to upgrade the development and operational characteristics of the culture, I can also help your company incorporate highly effective remote capabilities.

Cascadia

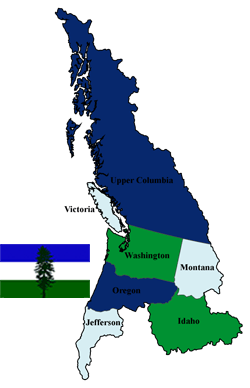
  • If there is travel, I prefer to keep it to a productively effective 10-15% of the time. Traveling dramatically decreases overall ability to contribute to actual work in an effective way. I do love to travel, speak, and get involved with the worldwide community but I always like to make sure that this involvement doesn’t stymie me from contributing to actual coding, design, and related efforts. NOTE: If travel is within the Cascadian Bioregion (see image: includes YVR, PDX, SEA, etc) it’s easy to increase my travel to 15-25% of the time as travel within the region is so easy. I probably should include SFO too, it’s super easy to get there and doesn’t cause disruption to daily workflow. (i.e. < 2 hr trip)
  • Design, build, and communicate. These are the things I like to do. I like to create what will work for high volume or high speed systems, then build prototypes and communicate how these work. Maybe I would be the one deploying to production, maybe the system is production that I’m deploying, but whatever the case is I’m happy to lead efforts on architecture and work with teams to build that architecture.
  • I love to provide leadership for teams, I love to build teams, and I like working with teams. Albeit I’m particular about team diversity and culture, I can bring my own skills and the ability to bring people together on a team and expand teams. If the culture is off kilter, I can help with that. If the culture is spot on, I can work effectively with that. Whatever the case, I’m a high communication, GSD type of guy provided the right environment and reigns removed.

Google Cloud Platform

Technical Skills

  • I’ve found Google Cloud Platform (GCP) a pleasure to work with lately. That combined with Terraform, Packer, and related HashiCorp tooling has been a lot of fun and provided an extremely high value for us at Home Depot.

HashiCorp

  • AWS has been another I’ve worked with that has been of stellar value, not particularly at Home Depot but at multitudes of startups and during consulting. AWS is still for many things my go to cloud provider option.
  • Azure is another I’ve used that would be an interesting service to use again. It’s been well over 2 years since I worked with or provided Azure support or consulting. I’ve got a soft spot in my heart for this cloud provider since I led teams back in 2010 writing some of the first white papers for the service!
  • I’m comfortable with C#, JavaScript, Java (mostly), and am looking forward to writing more Golang and happily will dive into Scala, Erlang, F#, and a whole host of other languages.
  • I’m happy to work with container tech (Rocket/CoreOS) or Docker and I’ll also help keep your company grounded that it might not be the panacea you’re looking for. But they definitely have lots of awesome uses!
  • I’d prefer a Unix/Linux environment to work in, but I’ll happily help remove Windows Servers from deployment requirements! 😉

Contact me or let’s talk jobs, cheers!