Writing Swift Like a Pro: Clean Code, Separation of Concerns, and AI-Assisted Development

Swift is a powerful, multi-paradigm language that blends object-oriented programming (OOP), protocol-oriented programming (POP), and functional programming (FP). With the rise of artificial intelligence (AI) tools such as GitHub Copilot, Cursor, and Tabnine, it has become easier than ever to generate code quickly. However, while AI accelerates development, it does not replace software craftsmanship. If you already have strong coding practices and discipline, AI can be a valuable assistant. If you rely on AI blindly, you risk generating unreadable, unmaintainable, and inefficient code at scale.

Writing high-quality Swift code requires discipline in applying good naming conventions, maintaining a clear separation of concerns (SoC), following the five principles of SOLID design (Single Responsibility, Open/Closed, Liskov Substitution, Interface Segregation, and Dependency Inversion), and ensuring maintainability through best practices. While AI-generated code can be useful, it must be refactored and reviewed for clarity and correctness.

Naming Conventions and the Importance of Readability

One of the most overlooked yet essential aspects of clean Swift code is the use of proper naming conventions. Names communicate the intent behind variables, functions, and types. Poorly chosen names introduce ambiguity and cognitive overload, requiring developers to pause and decipher meaning. While AI tools can generate functions with reasonable names, they frequently default to generic and unclear names such as processData() or handleTask(), which offer no real insight into what the function actually does.

To ensure clarity, variable and function names should be descriptive and follow Swift’s established conventions. Variables and functions should use camel case formatting, meaning the first word starts with a lowercase letter, and subsequent words are capitalized (e.g., isUserLoggedIn). Type names, including structs and classes, should use Pascal case formatting, where all words start with uppercase letters (e.g., UserProfile). Boolean variables should be phrased as natural language questions to make their purpose explicit. A variable such as isActive is preferable to active because it clearly indicates a true or false state.

Abbreviations should be used sparingly and only when they are widely recognized. For example, fetchUserData() is more readable than fUsrDta(). Clarity should always take precedence over brevity. If a name does not clearly express its intent, it should be reconsidered. AI-generated suggestions should be manually reviewed to ensure they conform to these principles.

Object-Oriented Swift and When to Use Structs or Classes

Swift supports multiple programming paradigms, but it is important to use object-oriented programming (OOP) only when necessary. AI-generated code often defaults to class-based implementations due to the influence of languages such as Java and C#. However, Swift encourages the use of value types, such as structs, in most scenarios.

Structs are preferred when the data being represented does not require shared mutable state. Because structs are value types, they are copied rather than referenced when assigned to new variables or passed to functions. This behavior eliminates many concurrency issues and makes data management more predictable.

Classes should be used when reference semantics are required. Objects instantiated from classes are reference types, meaning that multiple instances can share and modify the same data. This is useful when objects represent entities with identity, such as view controllers or persistent storage models. However, excessive reliance on classes can lead to complex inheritance chains, increasing code coupling and reducing maintainability.

AI-generated code frequently misuses classes in situations where structs would be more appropriate. When reviewing AI-assisted code, it is essential to refactor unnecessary class-based implementations into structs to ensure immutability and better memory management.

The Role of Separation of Concerns in Maintainable Code

Separation of concerns (SoC) is a foundational software design principle that ensures that different parts of an application have distinct responsibilities. Without a clear separation between data models, business logic, and user interface (UI) components, codebases become difficult to maintain and test. AI-generated code often violates SoC by mixing multiple concerns in a single file, leading to monolithic and unstructured implementations.

To maintain a clean Swift codebase, SoC should be enforced through clear layering:

The model layer is responsible for defining the data structure and business logic of the application. It should not include UI or networking logic. A User struct, for example, should simply define a user’s attributes and behaviors without managing data fetching or UI updates.

The service layer handles data retrieval, including network requests, database interactions, and local storage. It abstracts data sources so that the rest of the application does not need to manage low-level networking or database operations.

The view model layer acts as an intermediary between the model layer and the UI. It processes and formats data for presentation while ensuring that UI components do not contain business logic. This separation simplifies testing and promotes reusability.

The UI layer is responsible for rendering the user interface and reacting to state changes. It should not contain business logic or directly manipulate the data model.

AI tools often generate code that blends these concerns together, requiring developers to refactor and properly separate responsibilities. Enforcing SoC ensures that code remains modular and adaptable to future changes.

The Importance of SOLID Principles in Swift

The five SOLID principles (Single Responsibility, Open/Closed, Liskov Substitution, Interface Segregation, Dependency Inversion) provide a structured approach to writing maintainable and scalable Swift code. AI-generated code frequently violates these principles, leading to poor design choices that hinder extensibility and testability.

Single Responsibility Principle (SRP) dictates that a class or struct should have only one reason to change. If a UserManager class is responsible for both fetching users from an API and handling authentication, it violates SRP. Instead, separate UserService and AuthenticationService components should be created to handle each concern independently.

Open/Closed Principle (OCP) states that code should be open for extension but closed for modification. AI-generated code often requires modifying existing classes to add functionality. Instead, Swift extensions should be used to extend behavior without altering existing implementations.

Liskov Substitution Principle (LSP) requires that subclasses should be interchangeable with their base class. AI-generated class hierarchies sometimes introduce dependencies that break substitutability, making the code inflexible. Instead, favor protocol-oriented programming (POP) to define reusable behaviors.

Interface Segregation Principle (ISP) emphasizes that interfaces should be specific to their purpose. AI-generated protocols often include excessive methods that are unrelated to a given implementation. Instead, protocols should be minimal and focused on a single aspect of functionality.

Dependency Inversion Principle (DIP) promotes reliance on abstractions rather than concrete implementations. AI-generated code often introduces tight coupling between dependencies. By using protocols and dependency injection, Swift applications remain flexible and testable.

AI-Assisted Development and the Future of Clean Code

AI coding assistants can be powerful tools, but they do not replace software engineering best practices. The ability to generate code quickly does not guarantee correctness, maintainability, or efficiency. While AI tools help with boilerplate code, syntax suggestions, and repetitive tasks, they cannot enforce good software design principles.

Developers must critically evaluate AI-generated code, refactoring it to ensure that it adheres to naming conventions, separation of concerns, and SOLID principles. AI should be viewed as an enhancement rather than a shortcut. By maintaining high coding standards, developers can leverage AI effectively without sacrificing maintainability.

References

Acronyms and Abbreviations

  • AI (Artificial Intelligence)
  • DIP (Dependency Inversion Principle)
  • FP (Functional Programming)
  • ISP (Interface Segregation Principle)
  • LSP (Liskov Substitution Principle)
  • OCP (Open/Closed Principle)
  • OOP (Object-Oriented Programming)
  • POP (Protocol-Oriented Programming)
  • SoC (Separation of Concerns)
  • SOLID (Single Responsibility, Open/Closed, Liskov Substitution, Interface Segregation, Dependency Inversion)
  • SRP (Single Responsibility Principle)
  • UI (User Interface)

Additional Reading

By following these principles, developers can write Swift code that remains clear, scalable, and maintainable, regardless of AI assistance.
Swift Coding Conventions: Writing Maintainable, Readable, and Elegant Code

Swift – Apple’s slick and safety-focused (? still not sure I’m bought in on that phrasing) programming language – has become the backbone of Apple’s development. Whether you’re hacking on an indie app or shipping production-grade enterprise software, writing consistent, readable, and idiomatic Swift is non-negotiable. Swift has a robust set of guidelines to follow, and I wrote a thing or three about it’s style of OOP, POP, and FP rolled into one language here, but let’s cut through the noise and hit the key conventions that will level up your Swift code.

Naming Things Well

Naming in Swift follows camelCase convention. Class names and structs should use UpperCamelCase, while variables and function names stick to lowerCamelCase.

Example:

struct Spaceship { }
let maxSpeed = 9000
func accelerate(to speed: Int) { }

Apple’s naming conventions emphasize clarity and intent over brevity. No cryptic abbreviations.

  • Avoid: let ms = 9000
  • Do: let maxSpeed = 9000

Constants Over Variables

Swift encourages immutability. Use let instead of var wherever possible to make your code safer and more predictable.

Example:

let planetsInSolarSystem = 8  // Immutable
var spaceshipFuel = 100       // Only use 'var' when mutation is required

Learn more about constants and variables in the Swift Language Guide.

Function Signatures

Functions should be descriptive yet concise, using parameter labels to improve readability.

Example:

func fly(to destination: String) { }

Compare that to:

func fly(_ d: String) { }  // Hard to understand

More details are available in Apple’s Swift Function Guide.

Structs vs. Classes

Swift loves value types. Use structs over classes whenever possible because they’re safer and don’t come with reference-sharing side effects.

Use Structs When Use Classes When
Data is immutable or simple Objects require identity
No need for inheritance Need to subclass
Value semantics (copy behavior) Reference semantics (shared instance)

Apple provides more details on value vs. reference types.

Optionals and Safely Handling Nil

Swift forces you to think about nullability upfront with optionals (?) and safely unwrapping values.

Example:

var optionalSpaceship: Spaceship?
if let spaceship = optionalSpaceship {
    print("We have a spaceship: \(spaceship)")
} else {
    print("No spaceship available.")
}

Unwrapping can be done with if let, guard let, or force-unwrapping (!)—though force unwrapping should only be used when you’re absolutely sure the value exists. For more on this, see Optionals.

Guard for Early Exits

Instead of piling on nested if statements, Swift encourages using guard for cleaner flow control.

Example:

func launch(spaceship: Spaceship?) {
    guard let spaceship = spaceship else {
        print("No spaceship available!")
        return
    }
    print("Launching \(spaceship)")
}

This keeps the happy path unindented and prevents excessive nesting. More on guard.

Protocols Over Inheritance

Inheritance leads to tight coupling. Swift encourages protocol-oriented programming, where behavior is shared via protocols instead of deep class hierarchies.

Example:

protocol Flyable {
    func fly()
}

struct Rocket: Flyable {
    func fly() { print("🚀 Rocket launching!") }
}

Protocols help keep code modular and reusable. Learn more about this in the Protocols Guide.

Leverage Swift’s Type Inference

You don’t always need to explicitly declare types. Swift’s type inference handles it for you.

Example:

let earth = "Planet Earth"  // Swift knows it's a String

Explicitly stating the type is only necessary when clarity is needed. More on Swift type inference.

Extensions for Organization

Instead of cluttering a class or struct with all functionality, break it up using extensions.

Example:

extension Spaceship {
    func startEngine() { print("Engine started.") }
}

This keeps related behavior grouped and makes code more modular. More details can be found in Extensions.

Write Swift-y Code

Avoid writing Swift like Java or C#. For example, don’t use overly verbose getters and setters.

Example of what not to do (Java-style):

class Spaceship {
    private var _speed: Int = 0
    func getSpeed() -> Int { return _speed }
    func setSpeed(speed: Int) { _speed = speed }
}

Do this instead (Swift-style):

class Spaceship {
    var speed: Int = 0
}

This leverages Swift’s computed properties instead of unnecessary methods.

Final Thoughts

Following Swift’s best practices isn’t just about writing cleaner code—it’s about making your code more maintainable, scalable, and idiomatic. By sticking to these conventions, you’ll not only improve collaboration with other developers but also make future-you thankful when revisiting your old code. Clean code means fewer headaches, fewer bugs, and better long-term results.

References

Got a Swift convention you live by? Drop it in the comments or shoot me a message. That’s what I’ve got so far, may you have the best composite thrashing code, cheers!

Swift: A Multi-Paradigm Powerhouse—OOP, POP, and FP

Swift is a versatile toolkit that lets you solve problems in multiple ways. Whether you’re leveraging the familiar object-oriented principles, diving into Swift’s protocol-oriented magic, or harnessing the power of functional programming, Swift has you covered. In my latest swift dive I’ve put together a break down of these paradigms per Swift usage.

Object-Oriented Programming (OOP)

OOP is all about organizing your code around objects and classes. In Swift, you can create classes with properties, methods, inheritance, and polymorphism. This approach helps in modeling real-world entities and their behaviors.

Core Elements & Example per Swift:

// Define a base class with properties and methods.
class Vehicle {
    var currentSpeed: Double = 0.0

    func accelerate() {
        currentSpeed += 10.0
        print("Accelerating: \(currentSpeed) mph")
    }
}

// Inheritance: Create a subclass that extends Vehicle.
class Car: Vehicle {
    var model: String

    init(model: String) {
        self.model = model
        super.init()
    }

    override func accelerate() {
        currentSpeed += 20.0  // Cars accelerate faster!
        print("\(model) car accelerating: \(currentSpeed) mph")
    }
}

let myCar = Car(model: "Swiftster")
myCar.accelerate()  // Output: Swiftster car accelerating: 20.0 mph

Swift’s OOP support is clear and concise. Classes, inheritance, and method overriding are all built into the language, allowing you to model complex relationships in a way that’s both readable and maintainable.

Protocol-Oriented Programming (POP)

Protocol-oriented programming is one of Swift’s standout features. Rather than relying solely on class inheritance, Swift encourages you to define protocols that specify what methods and properties a type must implement. You can then extend these protocols to provide default implementations, making your code more modular and composable.

Core Elements & Example per Swift:

// Define a protocol that outlines a contract.
protocol Drivable {
    var speed: Double { get set }
    func drive()
}

// Provide a default implementation using an extension.
extension Drivable {
    func drive() {
        print("Driving at \(speed) mph")
    }
}

// Conform to the protocol with a struct.
struct Bicycle: Drivable {
    var speed: Double
}

let bike = Bicycle(speed: 15.0)
bike.drive()  // Output: Driving at 15.0 mph

With protocols and protocol extensions, Swift lets you compose behaviors without the constraints of a rigid class hierarchy. This encourages cleaner code reuse and a more flexible architecture.

Functional Programming (FP)

Functional programming in Swift emphasizes immutability, first-class functions, and expressive higher-order functions. It’s all about writing code that’s predictable and easy to test by treating functions as values and avoiding side effects.

Core Elements & Example per Swift:

// A simple array of numbers.
let numbers = [1, 2, 3, 4, 5]

// Using higher-order functions: map, filter, and reduce.
let squaredNumbers = numbers.map { $0 * $0 }
let evenNumbers = numbers.filter { $0 % 2 == 0 }
let sum = numbers.reduce(0, +)

print("Squared: \(squaredNumbers)")  // Output: Squared: [1, 4, 9, 16, 25]
print("Evens: \(evenNumbers)")       // Output: Evens: [2, 4]
print("Sum: \(sum)")                 // Output: Sum: 15

Closures in Swift are concise and powerful, letting you pass functionality around like any other value. This is the essence of FP—treating functions as first-class citizens and focusing on transformations rather than mutable state.

Bringing It All Together

Swift’s versatility truly shines when you start combining paradigms. Imagine building a networking, or web module that handles HTTP ingress and egress using the best of object-oriented programming (OOP), protocol-oriented programming (POP), and functional programming (FP). Below is a basic example that demonstrates how these paradigms come together to create a clean, maintainable, and flexible web module.

Let’s break down the implementation:

  • OOP: We begin with a base class that represents a network request. This class encapsulates properties like the URL, HTTP method, headers, and body. By modeling a request as an object, you can later subclass it or extend it for specialized behaviors (e.g., GET vs. POST requests).
  • POP: Instead of stuffing all behaviors into a single class hierarchy, Swift encourages you to define protocols for cross-cutting concerns—such as logging and caching. Protocols allow you to declare a contract for these behaviors, and with protocol extensions, you can supply default implementations. This approach makes it simple to mix these behaviors into any type that needs them.
  • FP: For asynchronous networking, closures are your best friend. They let you handle responses in a functional style, mapping or filtering the resulting data before it even reaches the caller. This keeps your code both declarative and testable.

Below I’ve slung together a simple implementation that brings these concepts together:

import Foundation

// OOP: Base class for network requests
class NetworkRequest {
    let url: URL
    let httpMethod: String  // "GET", "POST", "PUT", "DELETE", etc.
    var headers: [String: String]
    var body: Data?

    init(url: URL, httpMethod: String = "GET", headers: [String: String] = [:], body: Data? = nil) {
        self.url = url
        self.httpMethod = httpMethod
        self.headers = headers
        self.body = body
    }

    func asURLRequest() -> URLRequest {
        var request = URLRequest(url: url)
        request.httpMethod = httpMethod
        request.allHTTPHeaderFields = headers
        request.httpBody = body
        return request
    }
}

// POP: Protocol for logging behavior
protocol Loggable {
    func log(_ message: String)
}
extension Loggable {
    func log(_ message: String) {
        print("LOG: \(message)")
    }
}

// POP: Protocol for caching behavior
protocol Cacheable {
    func cacheResponse(_ data: Data, for request: URLRequest)
    func cachedResponse(for request: URLRequest) -> Data?
}
extension Cacheable {
    func cacheResponse(_ data: Data, for request: URLRequest) {
        // In a real implementation, you might write to disk or memory.
        print("Caching response for \(request.url?.absoluteString ?? "unknown URL")")
    }

    func cachedResponse(for request: URLRequest) -> Data? {
        // For our example, we simulate a cache miss.
        return nil
    }
}

// FP & OOP: HTTP client using closures for asynchronous responses
class HTTPClient: Loggable, Cacheable {
    let session: URLSession = URLSession.shared

    // This method sends a network request and handles the result using a closure.
    func send(request: NetworkRequest, completion: @escaping (Result<Data, Error>) -> Void) {
        let urlRequest = request.asURLRequest()

        // Check if we already have a cached response.
        if let cachedData = cachedResponse(for: urlRequest) {
            log("Returning cached response for \(urlRequest.url?.absoluteString ?? "unknown URL")")
            completion(.success(cachedData))
            return
        }

        log("Sending \(urlRequest.httpMethod ?? "UNKNOWN") request to \(urlRequest.url?.absoluteString ?? "unknown URL")")

        // FP: Use a closure to handle the asynchronous response.
        session.dataTask(with: urlRequest) { data, response, error in
            if let error = error {
                self.log("Error: \(error.localizedDescription)")
                completion(.failure(error))
                return
            }

            guard let data = data else {
                let error = NSError(domain: "HTTPClientError", code: 0, userInfo: [NSLocalizedDescriptionKey: "No data received"])
                self.log("Error: No data received")
                completion(.failure(error))
                return
            }

            self.log("Received data for \(urlRequest.url?.absoluteString ?? "unknown URL")")
            self.cacheResponse(data, for: urlRequest)

            // FP: At this point, you could use map or filter on the data if needed.
            // For example, you might transform the JSON response:
            // let transformedData = try? JSONDecoder().decode(MyModel.self, from: data)
            completion(.success(data))
        }.resume()
    }
}

// Example usage of the networking module:

// Create a sample GET request.
guard let url = URL(string: "https://api.example.com/data") else {
    fatalError("Invalid URL")
}
let getRequest = NetworkRequest(url: url, httpMethod: "GET")

// Instantiate the HTTP client.
let client = HTTPClient()

// Send the request and handle the response using a closure (FP style).
client.send(request: getRequest) { result in
    switch result {
    case .success(let data):
        // FP: Use map/filter to transform data as needed.
        do {
            if let jsonObject = try JSONSerialization.jsonObject(with: data, options: []) as? [String: Any] {
                print("Parsed JSON: \(jsonObject)")
            } else {
                print("Unexpected data format.")
            }
        } catch {
            print("JSON parsing error: \(error)")
        }

    case .failure(let error):
        print("Request failed with error: \(error)")
    }
}

How It All Comes Together

  • OOP: The NetworkRequest class encapsulates the details of an HTTP request. By centralizing properties like the URL, HTTP method, and headers, you make it easy to extend and manage your requests. If you later need specialized requests (say, a PostRequest with multipart data), you can subclass or modify this base class.
  • POP: Instead of bloating your network client with logging and caching logic, you define the Loggable and Cacheable protocols. By providing default implementations via protocol extensions, you can mix these behaviors into any class without forcing a rigid inheritance structure. This makes your code modular and easier to maintain.
  • FP: The HTTPClient uses closures to handle asynchronous network responses, a hallmark of functional programming. This approach makes it straightforward to chain transformations on your data. For instance, once the data is returned, you might use higher-order functions (like map or filter) to transform JSON into your app’s domain models, keeping side effects to a minimum and your code highly composable.

Final Thoughts

This example shows how Swift’s design allows you to mix paradigms to best suit your problem domain. By leveraging OOP for modeling, POP for behavior composition, and FP for handling asynchronous data flows, you create a networking module that’s both powerful and flexible. Whether you’re handling HTTP verbs for ingress (incoming data) or egress (sending data), Swift’s multi-paradigm nature gives you the tools to build robust, elegant solutions.

Happy thrashing code, keep it churning! 😜

CAP Theorem Insights for Apache Kafka and Flink

In this article, I’ll explore CAP Theorem and its implications on distributed systems, particularly focusing on Apache Kafka, Apache Flink, and Apache Cassandra. I’ll then dissect how CAP influences these systems in real-world scenarios, delve into some of the edge cases like split-brain scenarios, and offer actionable strategies to mitigate challenges. Finally, a wrap up with deployment strategies for self-hosted environments and discuss how Confluent Cloud tackles CAP-related challenges.

What is the CAP Theorem?

The CAP Theorem, introduced by Eric Brewer, states that in a distributed data system, you can only guarantee two out of the following three properties:

  • Consistency (C): Every read receives the most recent write or an error.
  • Availability (A): Every request receives a response, even if it’s not the most recent write.
  • Partition Tolerance (P): The system continues to function despite network partitions.

This means that distributed systems inherently make trade-offs, and understanding these trade-offs is key to designing robust architectures.

Apache Kafka

Apache Kafka is a distributed event streaming platform, and its architecture must navigate CAP trade-offs. Kafka primarily emphasizes Availability and Partition Tolerance, especially in scenarios where brokers and clients span different network regions.

  • Consistency trade-offs: Kafka does not guarantee strict consistency but offers tunable consistency through configurations like acks and replication factors. For example:
    • acks=all ensures that data is written to all replicas, increasing consistency but potentially sacrificing availability during partitions.
    • acks=1 prioritizes availability, allowing data to be acknowledged by a single replica, but risks data loss during partitions.

Apache Flink, a real-time stream processing framework, interacts with CAP in a nuanced way since it relies on external state backends like Kafka or Cassandra. Flink’s checkpointing mechanism introduces a form of eventual consistency. While processing, Flink aims for Consistency and Partition Tolerance, but it can’t guarantee immediate availability if partitions disrupt checkpointing.

CAP Theorem and Apache Cassandra

Apache Cassandra is a CP system with tunable consistency. While its architecture inherently emphasizes Partition Tolerance, it offers significant flexibility to configure consistency:

  • Consistency levels: You can configure read and write consistency levels (e.g., ONE, QUORUM, ALL).
  • Split-brain scenarios: During a network partition, Cassandra nodes may diverge in state, leading to temporary inconsistencies. When the partition is resolved, Cassandra uses mechanisms like hinted handoff, read repair, and anti-entropy repairs to reconcile data.

However, it’s worth noting that in extreme scenarios, such as prolonged partitions or client-side misconfigurations, the perception of availability might degrade if consistency settings are too strict.

1. Kafka in a Split-Brain Scenario When a Kafka cluster experiences a network partition, it can form two isolated groups of brokers. Producers and consumers connected to different partitions might produce and consume data independently, leading to inconsistency when the partition resolves.

  • Impact:
    • Data duplication or loss may occur as brokers compete to elect new leaders.
    • Producers connected to one partition may succeed in writing data that is not replicated to the other partition.
  • Mitigation Strategies:
    • Configure an appropriate replication factor to ensure data durability.
    • Use partition reassignment tools judiciously to avoid leader conflicts.
    • Monitor leader elections and enforce quorum policies for write consistency.

2. Flink State Management During Failures Apache Flink’s distributed nature means its state is often managed in external systems, like Kafka topics or durable stores. During a network partition or backend failure, Flink’s checkpointing mechanism might be interrupted.

  • Impact:
    • Failed checkpoints can result in replaying of events, leading to duplicate processing.
    • Recovery might take longer if the state backend is unavailable.
  • Mitigation Strategies:
    • Implement high-availability state backends using distributed file systems or cloud storage.
    • Configure incremental checkpointing to minimize recovery time.
    • Use Flink’s Exactly-Once processing guarantees when paired with compatible state backends like Kafka compacted topics.

3. Combined Kafka-Flink Pipelines In scenarios where Kafka is both the source and sink for Flink, CAP trade-offs in Kafka propagate downstream, complicating Flink’s processing logic. For instance, Kafka’s availability settings (e.g., acks=1) may lead to data loss, which Flink’s state cannot reconcile.

  • Impact:
    • Event order may become inconsistent, causing downstream processing errors.
    • Flink’s state checkpoints might include partial or duplicate records from Kafka.
  • Mitigation Strategies:
    • Align Kafka’s consistency guarantees with Flink’s checkpointing configurations to ensure end-to-end Exactly-Once semantics.
    • Leverage idempotent producers in Kafka to eliminate duplicates.
    • Configure Kafka consumers in Flink with isolation.level=read_committed to process only committed records.

Confluent Cloud and CAP Management

Confluent Cloud abstracts much of the operational complexity of Kafka, focusing on maximizing Availability and Partition Tolerance while providing tools to enhance Consistency:

  • Schema Registry: Ensures data compatibility across producers and consumers.
  • Multi-region replication: Addresses partitioning by replicating data across regions, reducing the impact of regional failures.
  • Monitoring and SLAs: Confluent Cloud provides detailed metrics and service-level agreements to help users understand system behavior during edge cases.

User Mitigations on Confluent Cloud

  • Replication policies: Leverage Confluent’s multi-region support for fault tolerance.
  • Producer acknowledgments: Configure acks=all for critical workloads to ensure data consistency.
  • Topic configurations: Use compacted topics to reduce the impact of eventual consistency.

When deploying Kafka and Flink yourself, consider the following:

Apache Kafka

  • Use a minimum of three brokers to ensure quorum-based leader elections.
  • Carefully configure replication factors and partitions to balance throughput and fault tolerance.
  • Enable monitoring with tools like Prometheus and Grafana to identify partitions early.

Apache Flink

  • Deploy Flink clusters with job and task managers separated for scalability.
  • Configure high-availability setups with Zookeeper or Kubernetes.
  • Use external durable state backends (e.g., Kafka, Cassandra) with proper consistency settings.

Combined Pipelines

  • Synchronize checkpoint intervals between Flink and Kafka to minimize latency.
  • Implement retry logic for failed Kafka writes in Flink.
  • Test failure scenarios rigorously to fine-tune configurations.

Conclusion

The CAP Theorem is a foundational concept that continues to shape distributed system design (albeit some spirited argument to the contrary). By understanding its implications on tools like Apache Kafka, Flink, and Cassandra, and leveraging managed services like Confluent Cloud, we can make informed architectural decisions that balance consistency, availability, and partition tolerance effectively. Whether you’re self-hosting or using managed services, robust configurations and a clear understanding of CAP trade-offs are key to building resilient systems.

What is the SITREP on Apache Kafka & Flink?

I’ve worked with (** references at end of article) a number of Apache projects over the years, often pretty closely; Apache Cassandra, Apache Flink, Apache Kafka, Apache Zookeeper and numerous others. But the last few years I’ve not been immediately hands on with the technology. A few questions popped up recently, that fortunately I was able to answer based on existing knowledge, but it made me real curious about what the SITREP (Situational Report) is for the Apache Kafka and Flink Projects for TODAY, i.e. rolling into 2025! The following is a quick dive into the history and then the latest details (and drama?) with Apache Kafka, Flink, and tangentially some other projects (Zookeeper?).

Apache Projects – Context & Quick Details

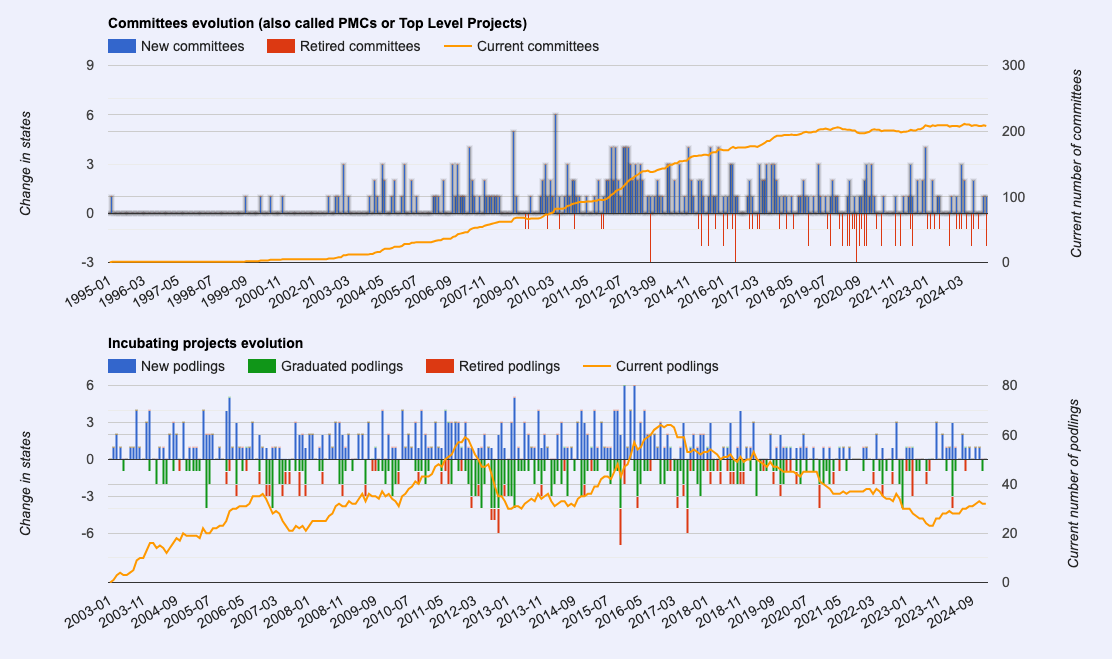
If you’re unfamiliar with the Apache Projects in a general sense, I highly suggest going and checking out the Apache Project Directory and Apache Projects List. There you will find all sorts of fascinating information about the organization itself, how the projects are organized, and the trend of committees and related details. For example, I always love checking out the initial charts on retired and active that show on the directory page, as I’ve snapshotted below.

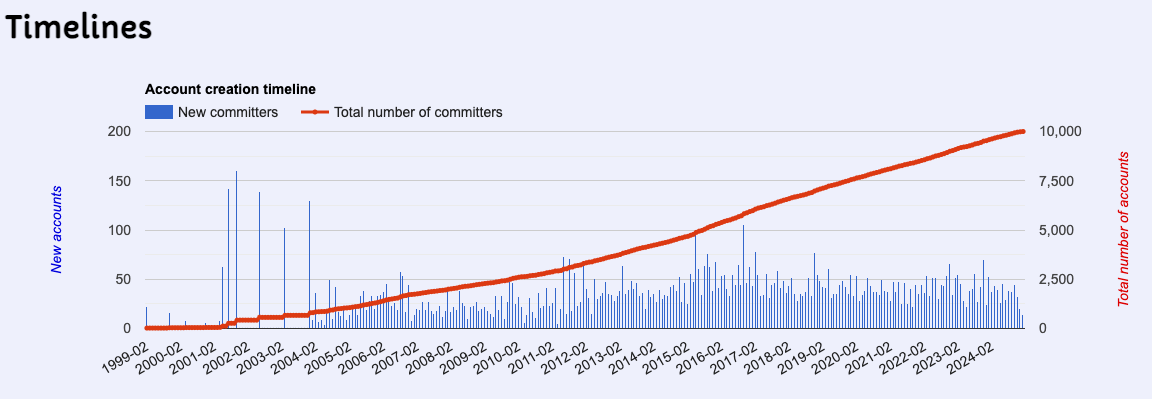
Another favorite chart is this one, which I’ll write some thoughts on in the very near future.

Tangential Projects

When checking up on Kafka & Flink and getting back up to speed, I’d be remiss if I didn’t include some of the key tangential projects, here is a list with links to important projects. These are related in the sense they either are used directly with or tangentially with Kafka or Flink. (Note: If I missed any, please leave a comment on the post and I’ll add it to this list!)

  1. Apache Zookeeper

    • Role: Originally used for managing Kafka’s metadata and ensuring distributed consensus.
    • Relationship: Kafka is moving toward a Zookeeper-less architecture with the KRaft protocol, but Zookeeper remains important for legacy deployments.
  2. Apache Kafka Connect

    • Role: A framework for integrating Kafka with external systems (databases, cloud services, etc.).
    • Relationship: Extends Kafka’s usability by enabling easy ingestion and egress of data.
  3. Apache Avro

    • Role: A data serialization system often used with Kafka for schema management.
    • Relationship: Enables efficient serialization and deserialization of messages sent over Kafka topics.
  4. Apache Camel

    • Role: An integration framework that provides numerous connectors.
    • Relationship: Used for integrating Kafka with diverse endpoints and implementing routing logic.
  5. Apache Storm

    • Role: A stream processing system.
    • Relationship: While Flink has overtaken Storm in many scenarios, Storm can still work alongside Kafka in legacy pipelines.
  6. Apache Samza

    • Role: A stream processing framework developed by LinkedIn.
    • Relationship: Like Flink, Samza can process Kafka streams but has a more niche adoption.
  7. Apache NiFi

    • Role: A data flow management system.
    • Relationship: Frequently used with Kafka to design, schedule, and monitor complex data flows.
  1. Apache Hadoop

    • Role: A distributed storage and processing framework.
    • Relationship: Flink can read and write data from/to Hadoop Distributed File System (HDFS) for batch and stream processing.
  2. Apache Beam

    • Role: A unified programming model for defining batch and stream processing pipelines.
    • Relationship: Flink serves as one of Beam’s execution engines, enabling portability across environments.
  3. Apache Pulsar

    • Role: A distributed messaging system and Kafka alternative.
    • Relationship: Pulsar can act as an event source for Flink, much like Kafka, and supports Flink’s connectors.
  4. Apache Cassandra

    • Role: A distributed NoSQL database.
    • Relationship: Frequently used as a sink for Flink’s stream processing jobs or as part of a pipeline originating in Kafka.
  5. Apache Hudi

    • Role: A data lake framework for managing datasets stored in HDFS or cloud storage.
    • Relationship: Works well with Flink for streaming updates and incremental processing in a data lake.
  6. Apache Iceberg

    • Role: A table format for large-scale, petabyte-scale analytics.
    • Relationship: Flink integrates with Iceberg for performing stream processing on large datasets.
  7. Apache Druid

    • Role: A real-time analytics database.
    • Relationship: Often paired with Flink for real-time ingestion and with Kafka for data streaming into analytics workloads.
  8. Apache Kafka Streams

    • Role: A stream processing library for Kafka.
    • Relationship: While Flink is more powerful for complex use cases, Kafka Streams is a simpler alternative for stream processing, often compared to Flink.
  1. Apache Kafka Connectors for Flink

    • Flink provides native connectors for reading from and writing to Kafka, enabling seamless integration between the two systems.
  2. Apache Flink Stateful Functions (StateFun)

    • A framework for building stateful applications with event-driven functions.
    • Relationship: Integrates well with Kafka for triggering stateful computations and workflows.
  3. Apache Pinot

    • Role: A real-time distributed OLAP datastore.
    • Relationship: Kafka provides real-time ingestion, while Flink processes and transforms data before storing it in Pinot for analytics.

Complementary Tools

  1. Schema Management:

  2. Orchestration and Management:

    • Apache Airflow for orchestrating workflows that include Kafka and Flink jobs.
    • Apache Oozie for managing workflows, especially in Hadoop environments.
  3. Observability:

    • Apache SkyWalking for monitoring and analyzing the performance of distributed systems, including Kafka and Flink.

Now for getting up to speed with the latest news of where Apache Flink and Apache Kafka are. Hopefully this section of my article will provide some insight for those looking to get into or get back into using or developing for or against these technologies. The idea, this will give you some context of where the tools have been in their development path and where they are now, and where they’re headed.

  • 2010
    • Apache Flink: Initiated as the “Stratosphere” research project, a collaboration between Technische Universität Berlin, Humboldt-Universität zu Berlin, and Hasso-Plattner-Institut Potsdam.
  • 2011
    • Apache Kafka: Developed at LinkedIn to address scalability issues with real-time data feeds and open-sourced.
  • 2012
    • Apache Kafka: Graduated from the Apache Incubator on October 23 and became a top-level project.
  • 2014
    • Apache Flink: Forked from Stratosphere’s distributed execution engine and entered the Apache Incubator in March.
    • Apache Flink: Graduated as a top-level Apache project in December.
  • 2015
    • Apache Flink: Released version 0.9.0 on June 24 and version 0.10.0 on November 16.
  • 2016
    • Apache Flink: Released version 1.0.0 on March 8, introducing backward compatibility for APIs. Released version 1.1.0 on August 8.
  • 2017
    • Apache Flink: Released versions 1.2.0 (February 6), 1.3.0 (June 1), and 1.4.0 (December 12).
    • Apache Kafka: Released version 1.0.0, marking its maturity as a platform.
  • 2018
    • Apache Flink: Released versions 1.5.0 (May 25), 1.6.0 (August 8), and 1.7.0 (November 30).
  • 2019
    • Apache Flink: Released versions 1.8.0 (April 9) and 1.9.0 (August 22).
  • 20* 20
    • Apache Flink: Released versions 1.10.0 (February 11), 1.11.0 (July 6), and 1.12.0 (December 10).
  • 2021
    • Apache Flink: Released versions 1.13.0 (May 3) and 1.14.0 (September 29).
  • 2022
    • Apache Flink: Released versions 1.15.0 (May 5) and 1.16.0 (October 28).
  • 2023
    • Apache Flink: Released versions 1.17.0 (March 23) and 1.18.0 (October 24).
  • 2024
    • Apache Flink: Plans for version 1.19.0 in March * 2024 and Flink 2.0 with a disaggregated storage architecture for cloud-native capabilities.
    • Apache Kafka: The community continues development toward Kafka 4.0, with plans to make KRaft mode the default and remove ZooKeeper dependencies.

2024 Highlights

In 2024, the data streaming ecosystem witnessed significant advancements, particularly surrounding Apache Flink and Apache Kafka. These developments encompassed major software releases, influential conferences, emerging trends, and notable industry movements.

Major Software Releases

  • Apache Flink 2.0 Preview: Marking its first major version change in eight years, the Apache Flink community unveiled a preview of Flink 2.0 in October 2024. This release introduced innovative features and improvements, setting the stage for the future of stream processing.
  • Confluent’s Integration of Flink and Iceberg: In March 2024, Confluent enhanced its hosted Kafka service by integrating Apache Flink and Apache Iceberg. This integration aimed to provide developers with robust tools for real-time data processing and analytics.

Conferences and Events

  • Flink Forward Berlin 2024: Celebrating the 10-year anniversary of Apache Flink, this conference took place from October 21-24, 2024. It featured speakers from industry leaders such as Apple, Alibaba, Mercedes-Benz, and Uber, highlighting Flink’s impact across various sectors.
  • Kafka Summit London 2024: Held in March 2024, this summit attracted over 3,500 attendees, both in-person and online. The event showcased the latest developments in Apache Kafka, with discussions on its integration with Apache Flink and the evolving data streaming landscape.
  • Current 2024: On September 17-18, 2024, Austin, Texas, hosted Current 2024, bringing together the data streaming community to discuss advancements in Apache Kafka and Apache Flink. The event featured insights from tech leaders and industry giants on real-time event streaming.

The year saw several key trends shaping the data streaming domain:

  • Data Sharing and Data Contracts: Emphasis on data sharing across business units and the implementation of data contracts became prevalent, aiming to enhance data governance and policy enforcement.
  • Serverless Stream Processing: The adoption of serverless architectures for stream processing gained traction, offering scalability and ease of deployment for real-time applications.
  • Integration with Generative AI: The convergence of data streaming platforms with Generative AI technologies, such as large language models, opened new avenues for intelligent data processing and analytics.

Industry Movements

  • Confluent’s Growth: Confluent, a key player in the data streaming industry, reported a 400% earnings growth in Q3 2024, with sales rising to $250.2 million. The company’s partnerships with tech giants like Amazon, Microsoft, and Google underscored its pivotal role in facilitating real-time data streaming and AI applications.

Stable and Development Versions

  • Apache Flink:
    • Latest Stable Version:** 1.* 20.0, released August 2, * 2024.
    • Development Version:** Flink 2.0 (preview release announced October 23, * 2024).
  • Apache Kafka:
    • Latest Stable Version:** 3.8.1, released November * 2024.
    • Development Version:** Kafka 4.0 (under active development).

References & Article Addendums

  1. Apache Flink History
  2. Wikipedia: Apache Flink
  3. The Evolution of Kafka
  4. Confluent’s History of Kafka
  5. Wikipedia: Apache Kafka
  6. Apache Kafka Incubator Graduation
  7. Flink in the Apache Incubator
  8. Apache Flink Graduation Announcement
  9. Apache Flink 0.9.0 Release Notes
  10. Apache Flink 0.10.0 Release Notes
  11. Apache Flink 1.0.0 Announcement
  12. Apache Flink 1.1.0 Announcement
  13. Apache Flink 1.2.0 Release Notes
  14. Apache Flink 1.3.0 Release Notes
  15. Apache Flink 1.4.0 Release Notes
  16. Kafka 1.0.0 Release Blog
  17. Apache Kafka Release Notes
  18. Apache Flink 1.5.0 Release Notes
  19. Apache Flink 1.6.0 Release Notes
  20. Apache Flink 1.7.0 Release Notes
  21. Apache Flink 1.8.0 Release Notes
  22. Apache Flink 1.9.0 Release Notes
  23. Apache Flink 1.10.0 Announcement
  24. Apache Flink 1.11.0 Announcement
  25. Apache Flink 1.12.0 Announcement
  26. Apache Flink 1.13.0 Announcement
  27. Apache Flink 1.14.0 Announcement
  28. Apache Flink 1.15.0 Announcement
  29. Apache Flink 1.16.0 Announcement
  30. Apache Flink 1.17.0 Announcement
  31. Apache Flink 1.18.0 Announcement
  32. Apache Flink 2.0 Preview Announcement
  33. Apache Kafka Downloads
  34. Apache Kafka Blog
  35. Apache Flink History on Wikipedia
  36. Apache Kafka History on Wikipedia
  37. Preview Release of Apache Flink 2.0
  38. Confluent Adds Flink, Iceberg to Hosted Kafka Service
  39. Highlights from Flink Forward Berlin 2024
  40. Data Streaming Platforms, Gen AI, and Apache Flink at Kafka Summit London 2024
  41. Current 2024: What’s on Tap in Data Streaming
  42. Top 5 Trends for Data Streaming with Kafka and Flink in 2024
  43. The Top Five Trends for Data Streaming in 2024
  44. AI Nerve Center – And 400% Growth – Fuel This Google, Amazon, Microsoft Partner

The ** at the beginning of this article I added, as to be specific. I have not directly, emphasis on directly contributed to the open source code bases of these Apache projects. I have however used, deployed, and even consulted on and discussed architecture and design of the projects over the years. One of these days I may sling some code into a repository or two!