Eliminating Machine Bias w/ Mary Ann Brennan & Getting from Machine Learning Outputs to Decisions… timely things!

Meet Mary Ann Brennan (@mabmierau) presenting…

Eliminating Machine Bias
mary-ann-brennan

Mary Ann is a jack-of-all-trades software engineer with background in iOS and full-stack web at a bunch of startups you’ve probably never heard of. She’s currently using her extended maternity leave to refresh her studies in Artificial Intelligence, the concentration for her master’s in Computer Science at Stanford. She recently completed Coursera’s Deep Learning specialization.

Mary Ann will give a quick overview of the machine bias problem. She’ll provide a definition (and contrast with statistical bias) and show examples like criminal justice system algorithms with racial bias and machine translation algorithms with gender bias.

Mary Ann will also pull an example from the Deeplearning.ai courses that shows how to remove gender bias from word representations. She’s been surprised how simple and manageable it was to do and hopes this will help inspire people to take the extra step to consider how they might eliminate bias in their work. Time permitting, she’ll also aim to round the talk out with other techniques and more info on what to look for in your own data.

In Brennan’s talk, there may even be a code up of web-based interactive before and after view of word representations that you can check out, maybe. Be sure to ask about it, as it might be in under construction!

Meet Robert Dodier (@robert-dodier) presenting…

Getting from Machine Learning Outputs to Decisions
robert-dodier

Robert is interested in Bayesian inference and decision analysis, among many other topic. He’s got a background in math, computer science, and engineering. He also wrote his PhD dissertation on Bayesian network models applied to engineering problems. Since then he’s worked on statistical analysis, including machine learning, in different domains and also worked for some years on a agent-based system for control of distributed energy resources.

You’ve set up a machine learning pipeline and it’s delivering predictions and estimates in real time just as you hoped it would! Now, what can you do with those numbers? Intuitively, we think that if we compute a prediction that an event A is more likely than another event B, we should probably take an A-related action instead of a B-related action. But not if the A-action is really expensive compared to the B-action; then we’d hesitate unless we’re very sure about A. We could set up some rules to post-process the predictions to figure out which action to take. That sounds kind of hackish.

But wait! The good news is that we can formalize the decision problem in terms of statements of beliefs (i.e., probabilities) and values or preferences (i.e., utilities). Typical machine learning algorithms can produce probabilities, which we’ll take as the inputs for the decision-making step. Given fairly broad assumptions, the right way to make a decision is to take the action which maximizes expected (i.e., weighted average) utility. This gives a straightforward recipe for deriving actions from beliefs and preferences. Typically the expected utility calculation is much simpler than the belief calculation, so we can easily a devise a decison-making back end for our machine learning pipeline.

In this talk, Robert will pose some real-world decision problems and then talk about the features they have in common. He’ll describe a framework for finding best actions for such problems in general, and show how the framework applies to the problems he posed at the beginning of the talk. He’ll emphasize the idea that a formal decision making analysis gives an obvious way to inject business logic into the pipeline in a clear and easily-modified way.

Now, Kirsten Westeinde & Rich Jolly

Processed with VSCO with c1 presetUsing Your Data to Give Your Customers Superpowers

Kirsten Westeinde (@kmkwesteinde) is a technology enthusiast and a lifelong learner. Currently a senior software engineer at Shopify, where she solves challenging web development problems on the daily. She’s toiled and built apps and services with Ruby on Rails for greater than 5 years and is constantly adding new tools to her tool belt. In the important realm of building us humans, she is passionate about building diverse teams, mentoring & teaching, and gaining new perspectives through travel & cross cultural communication.

Being a software developer who recently started working on a machine learning project that serves over 600,000 merchants at Shopify, Kirsten had to quickly bootstrap her machine learning skills. Being the intelligent and capable soul she is, it hasn’t been all that complicated or scary for her! Certain problems are inherently good candidates to be solved with machine learning. She’s planning to start off by discussing how to identify them, including some real life examples from my organization. Once identified, she’ll guide the audience through how to define their problem as a machine learning model: identifying their features & labels. Once the model has been defined she will discuss how to “productionize” it, describing their current setup, how they got there, and some of the challenges the team faces: monitoring/alerting, “online” training, and changing model features as data changes.

This talk intentionally treats model training as a black box, as it is the most well documented step of the ML process. The most challenging and nuanced aspects are identifying problems, defining a model, and productionizing it. Kirsten will walk the audience through these steps in detail, using real life examples, and they should leave feeling better prepared to tackle some machine learning problems of their own.

richard-jollyBreaking the Barriers to ML in Your Organization

Rich (@rich_jolly) is VP of Data Science at the Hawes Group, a small/medium business supplying services and software products in the accounts receivable space. Rich lives in Portland and is excited to join in and support my community.

You’ve been hearing incredible talks for ML4ALL learning how to apply machine learning. Great. But, there’s another critical piece to the puzzle – now that you can do machine learning, how can you initiate a ML project in your organization? To the dismay of those working at Amazon, Apple, Google and Facebook, many companies, especially small and medium businesses, have not ‘seen the light’ yet on the value of ML. As you head back to work, your management may well barrage you with reasons why doing an ML project is not a good idea. Rich will supply you with ideas and more to get past each and every objection and get your organization on the path machine learned winning wins. Objections he’ll address:

  • But we don’t have the software or compute power to do that!
  • But we can’t afford to hire an army of PhDs!
  • BI, AI, ML, Analytics, I don’t even know how to think about it!
  • But what should we work on? Will it have an ROI (return on investment)?
  • Even if we have some success, how can we sustain it?

Action!

I’m getting ramped and am really looking forward to all of these solid speakers and topics at ML4ALL! To get your tickets navigate over to ML4ALL here. Also check out the previously introduced speakers:

Say Hello to Jon and Amy @ML4ALL!

Welcome the next two speakers I’m introducing: Jon Oropeza and Amy Cheng!

jon-oropezaML Spends A Year In Burgundy

Jon (@joropeza) is coming to Portland from Portland to speak to us about Cote d’Or in Burgundy! He’s a hacker, grape lover, and Portlander that loves a good smooth wine made out of those grapes he loves!

Jon being a both a weather nerd and a wine nerd, he was curious if machine learning could be applied to vintages in an area where a) quality of wine varies greatly by year b) most of that variance has to do with weather patterns and different aspects of temperature and precipitation c) there are known, reasonably-objective classifications or ‘scores’ of each vintage, such that we could say that such-and-such year with such-and-such weather produced wines of good/bad/mediocre quality.

With that in mind, Jon pulled down a ton of weather data for the Cote d’Or region in Burgundy, France, prepped it, ran a few supervised models over it, chose the one that seemed to work best, and arrived at something that he thinks might be really cool to share with people. I’m betting it’ll be pretty freakin’ rad! With the conference being in late May, he’s even noted we’ll be able to look at some insights into whether 2018 is shaping up to be a good, great, or terrible year! 🙂

amy-chengMachine Learning, Art and JavaScript

Amy Cheng (@am3thyst) is going to arrive in Portland from the small hip village of Brooklyn ready to impart some knowledge about JavaScript with some art among it all! She’s a full-stack web dev who likes to explore the creative and expressive possibilities of code. She’s intrigued by machine learning because of all the questions about art it inspires. Such as, what does art mean in an age when computers can create new work based off old masters? Can a computer learn to be creative or can it only propagate existing human biases and tastes? Is there such a thing as neural aesthetics?

Machine learning can seem like an inaccessible subject, filled with complicated mathematical algorithms. In this talk, Amy will show that you don’t need a high-level degree in computer science or access to a cluster of supercomputers in order to experiment with machine learning. All you need is JavaScript and the web browser.

Amy will teach us the core concepts of machine learning by observing how a computer makes art, specifically how style transfer works. How does a computer learn to look at the world and then recreate what it sees? How does a computer paint like Van Gogh? Using available JavaScript toolkits, libraries, and APIs, she’ll show how creating neural networks in code can lead a computer to paint like Van Gogh.

I’m super stoked to find out what, and see these two present at ML4ALL! Maybe they’ll even join the bike ride I’ll lead and enjoy a bit of Portland on Sunday before the conference kicks off! To checkout ML4ALL and get your tickets navigate over to ML4ALL here!

My First LinkedIn Learning Course Experience

The first week of April I went to spend a week recording content for LinkedIn Learning in Carpinteria, California. While there I recorded a new course on Terraform. I’m not sure exactly when the release date will be, but I’ll be sure to make a post here and on LinkedIn when it gets released.

Currently I’m also working on a subsequent course, on more advanced Terraform and also a Go course focused around site reliability work and the usage of Go to write CLIs and related uses. I’ve got a little bit of the curriculum outline done and am chomping at the bit to get going. This post however is for future new authors or those interested, about the experience of the workflow when going into the LinkedIn Learning Studio down in Carpinteria. To summarize real quick, it was awesome. So if you just wanted to know that then you’re done with this post. Otherwise, read on for the details!

Travel: Getting to Carpinteria

I rarely travel based on standard US convention of herd onto plane at point A and go quickly to point B, reverse process for return and be done. I make my travel to and from almost everything an experience, and this trip down to Carpinteria afforded me some really great experiences. For some of the experience check out the post I wrote for the trip down “California to Carpinteria” and “Carpinteria and Santa Barbara“.

Once in Carpinteria, the commute everyday involved either a ~28 minute walk, a ~12 minute bike ride, or a ~5 minute bus ride. Whatever the case, it was super relaxed. This always put me in a good head space to work on the course. During these commutes I got to enjoy the beach front, parks, and other amenities along the way. It was only about 2 miles, but that 2 miles had a lot of beauty and pleasantness packed into it.

IMG_4206-X5

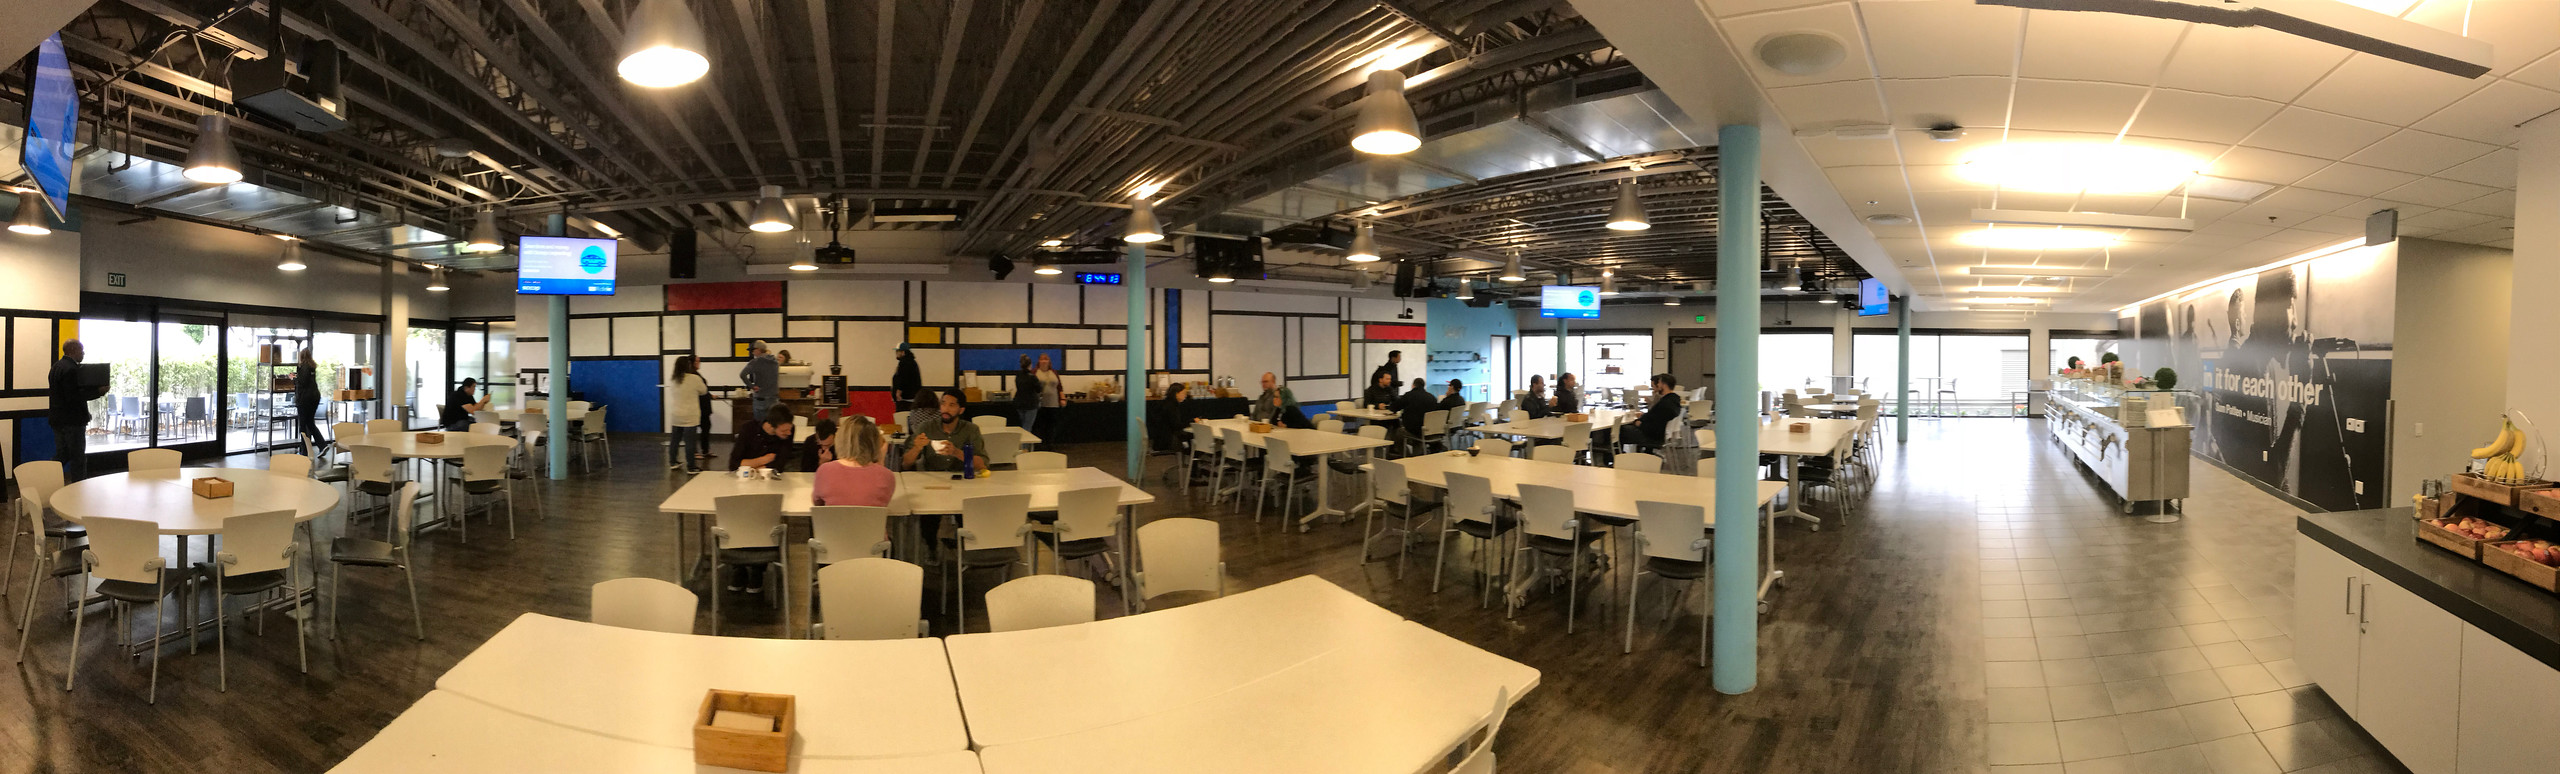
LinkedIn @ Carpinteria

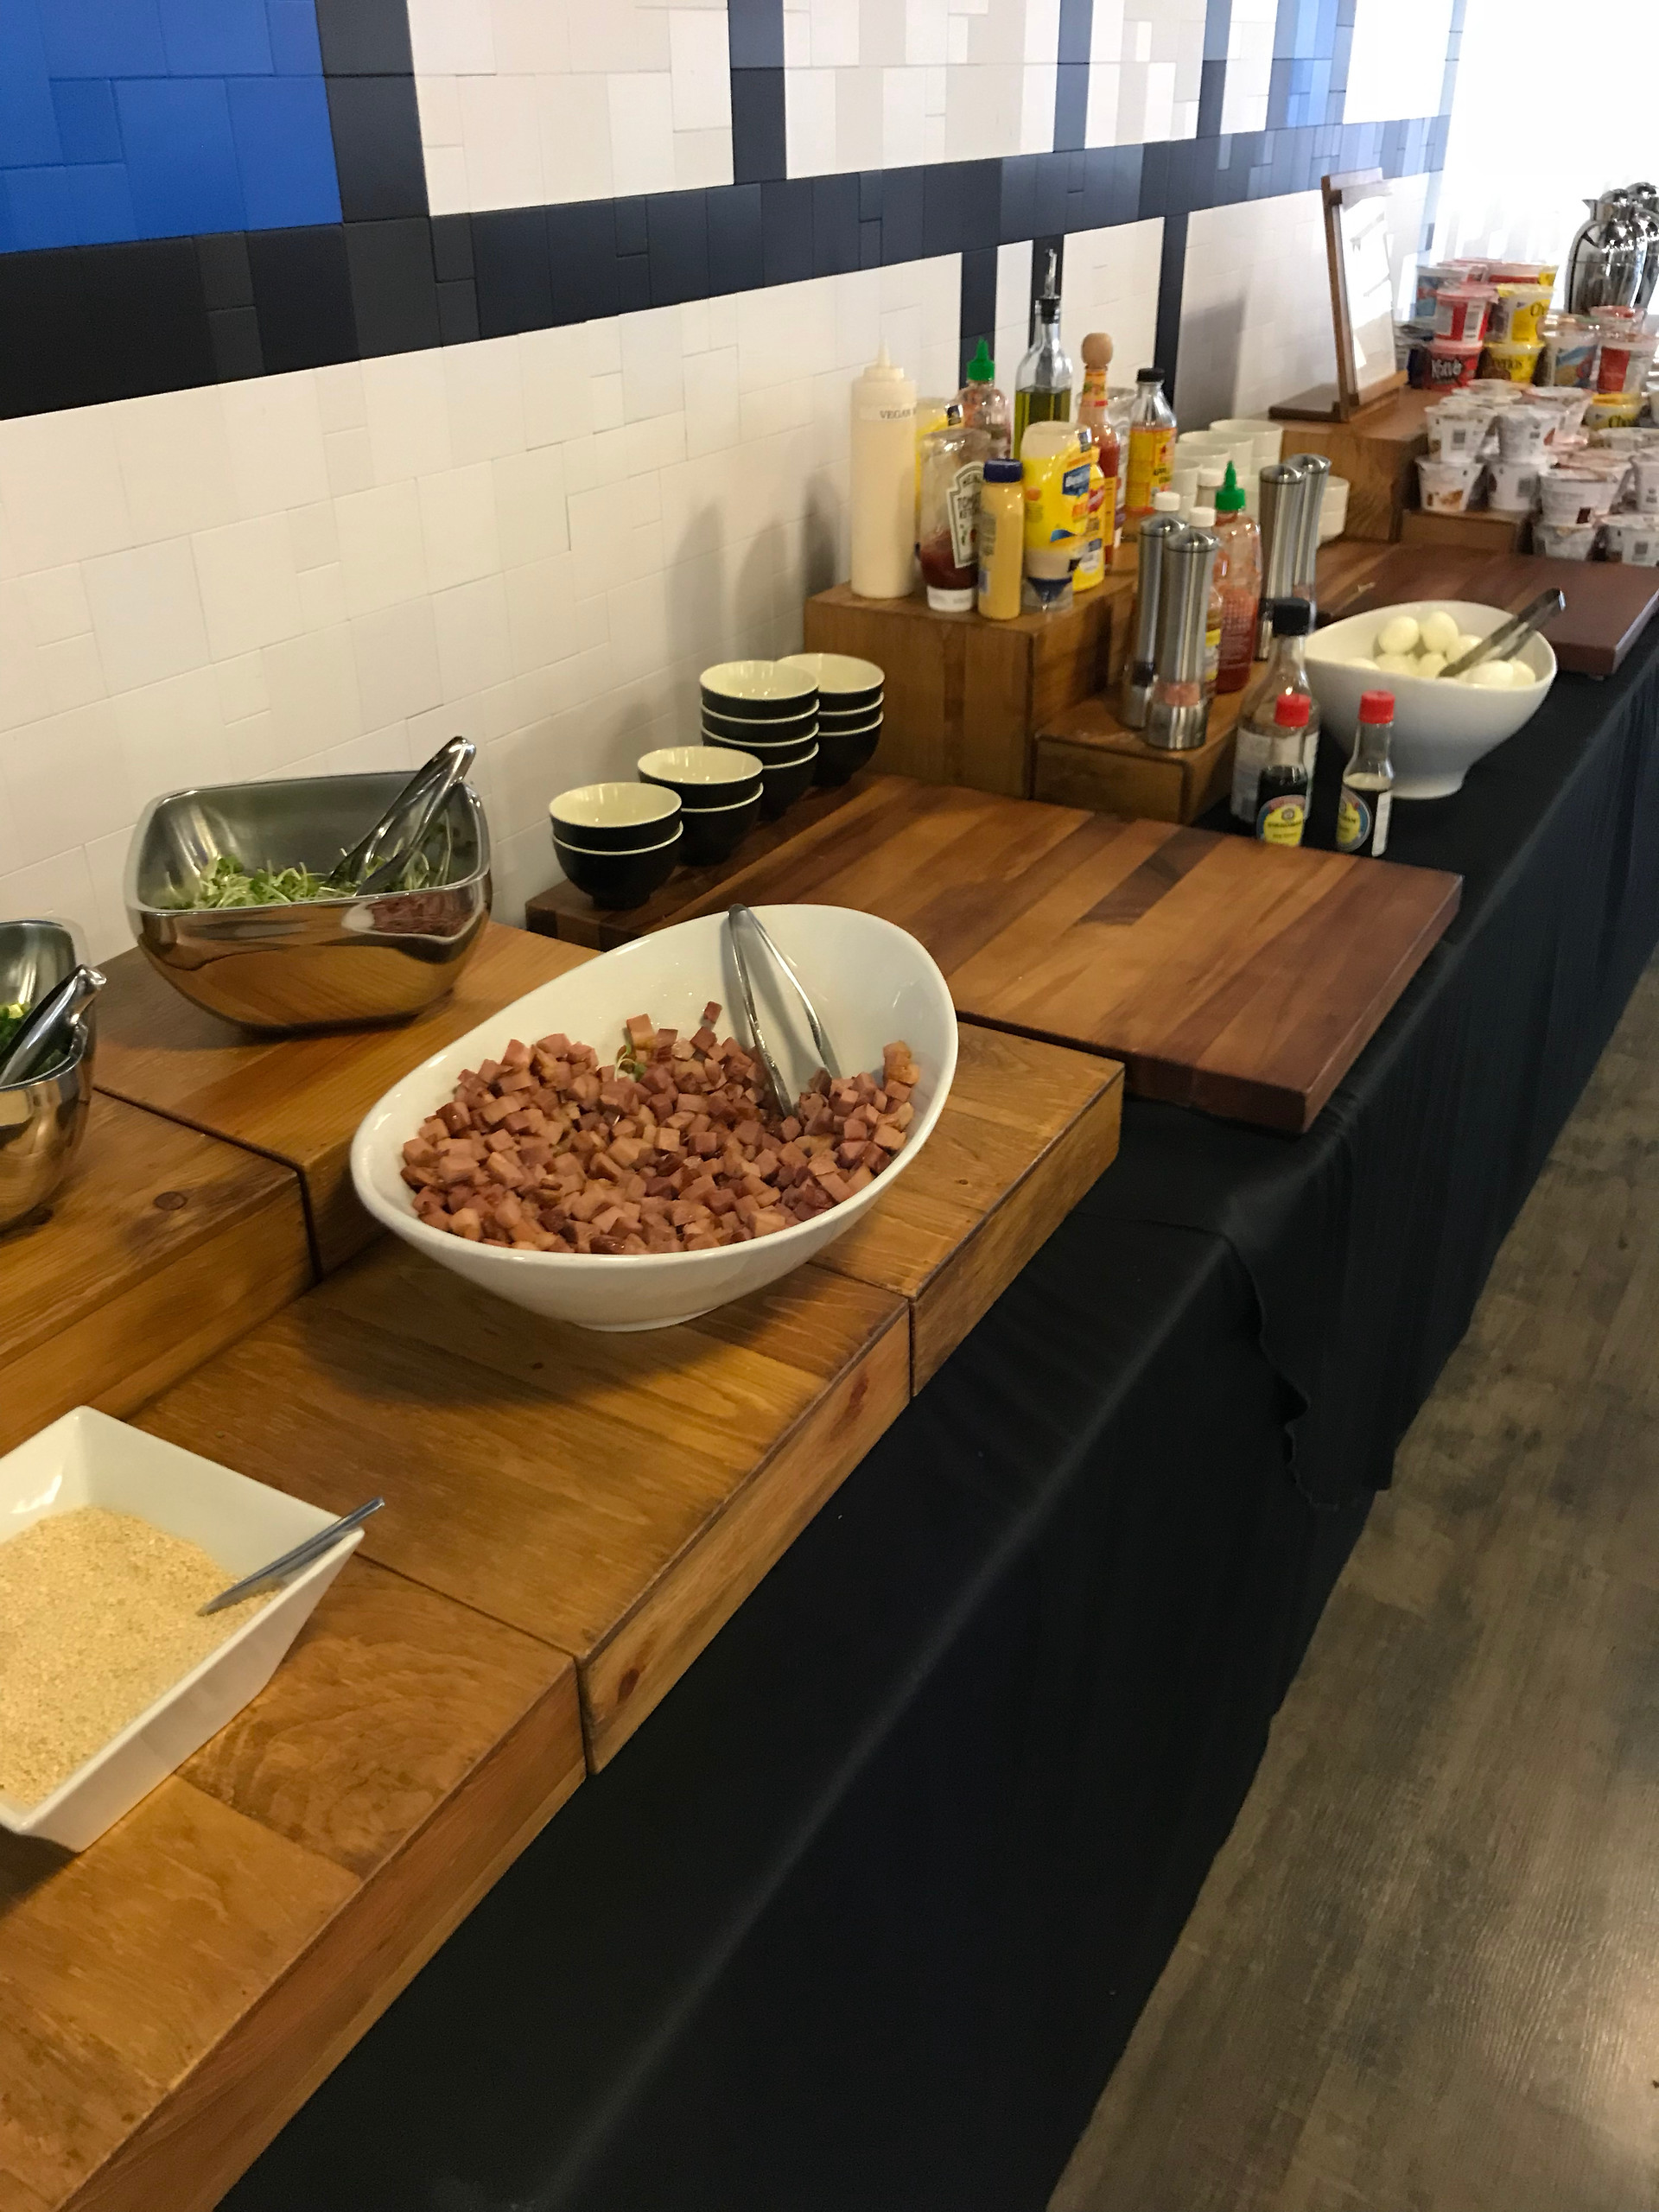
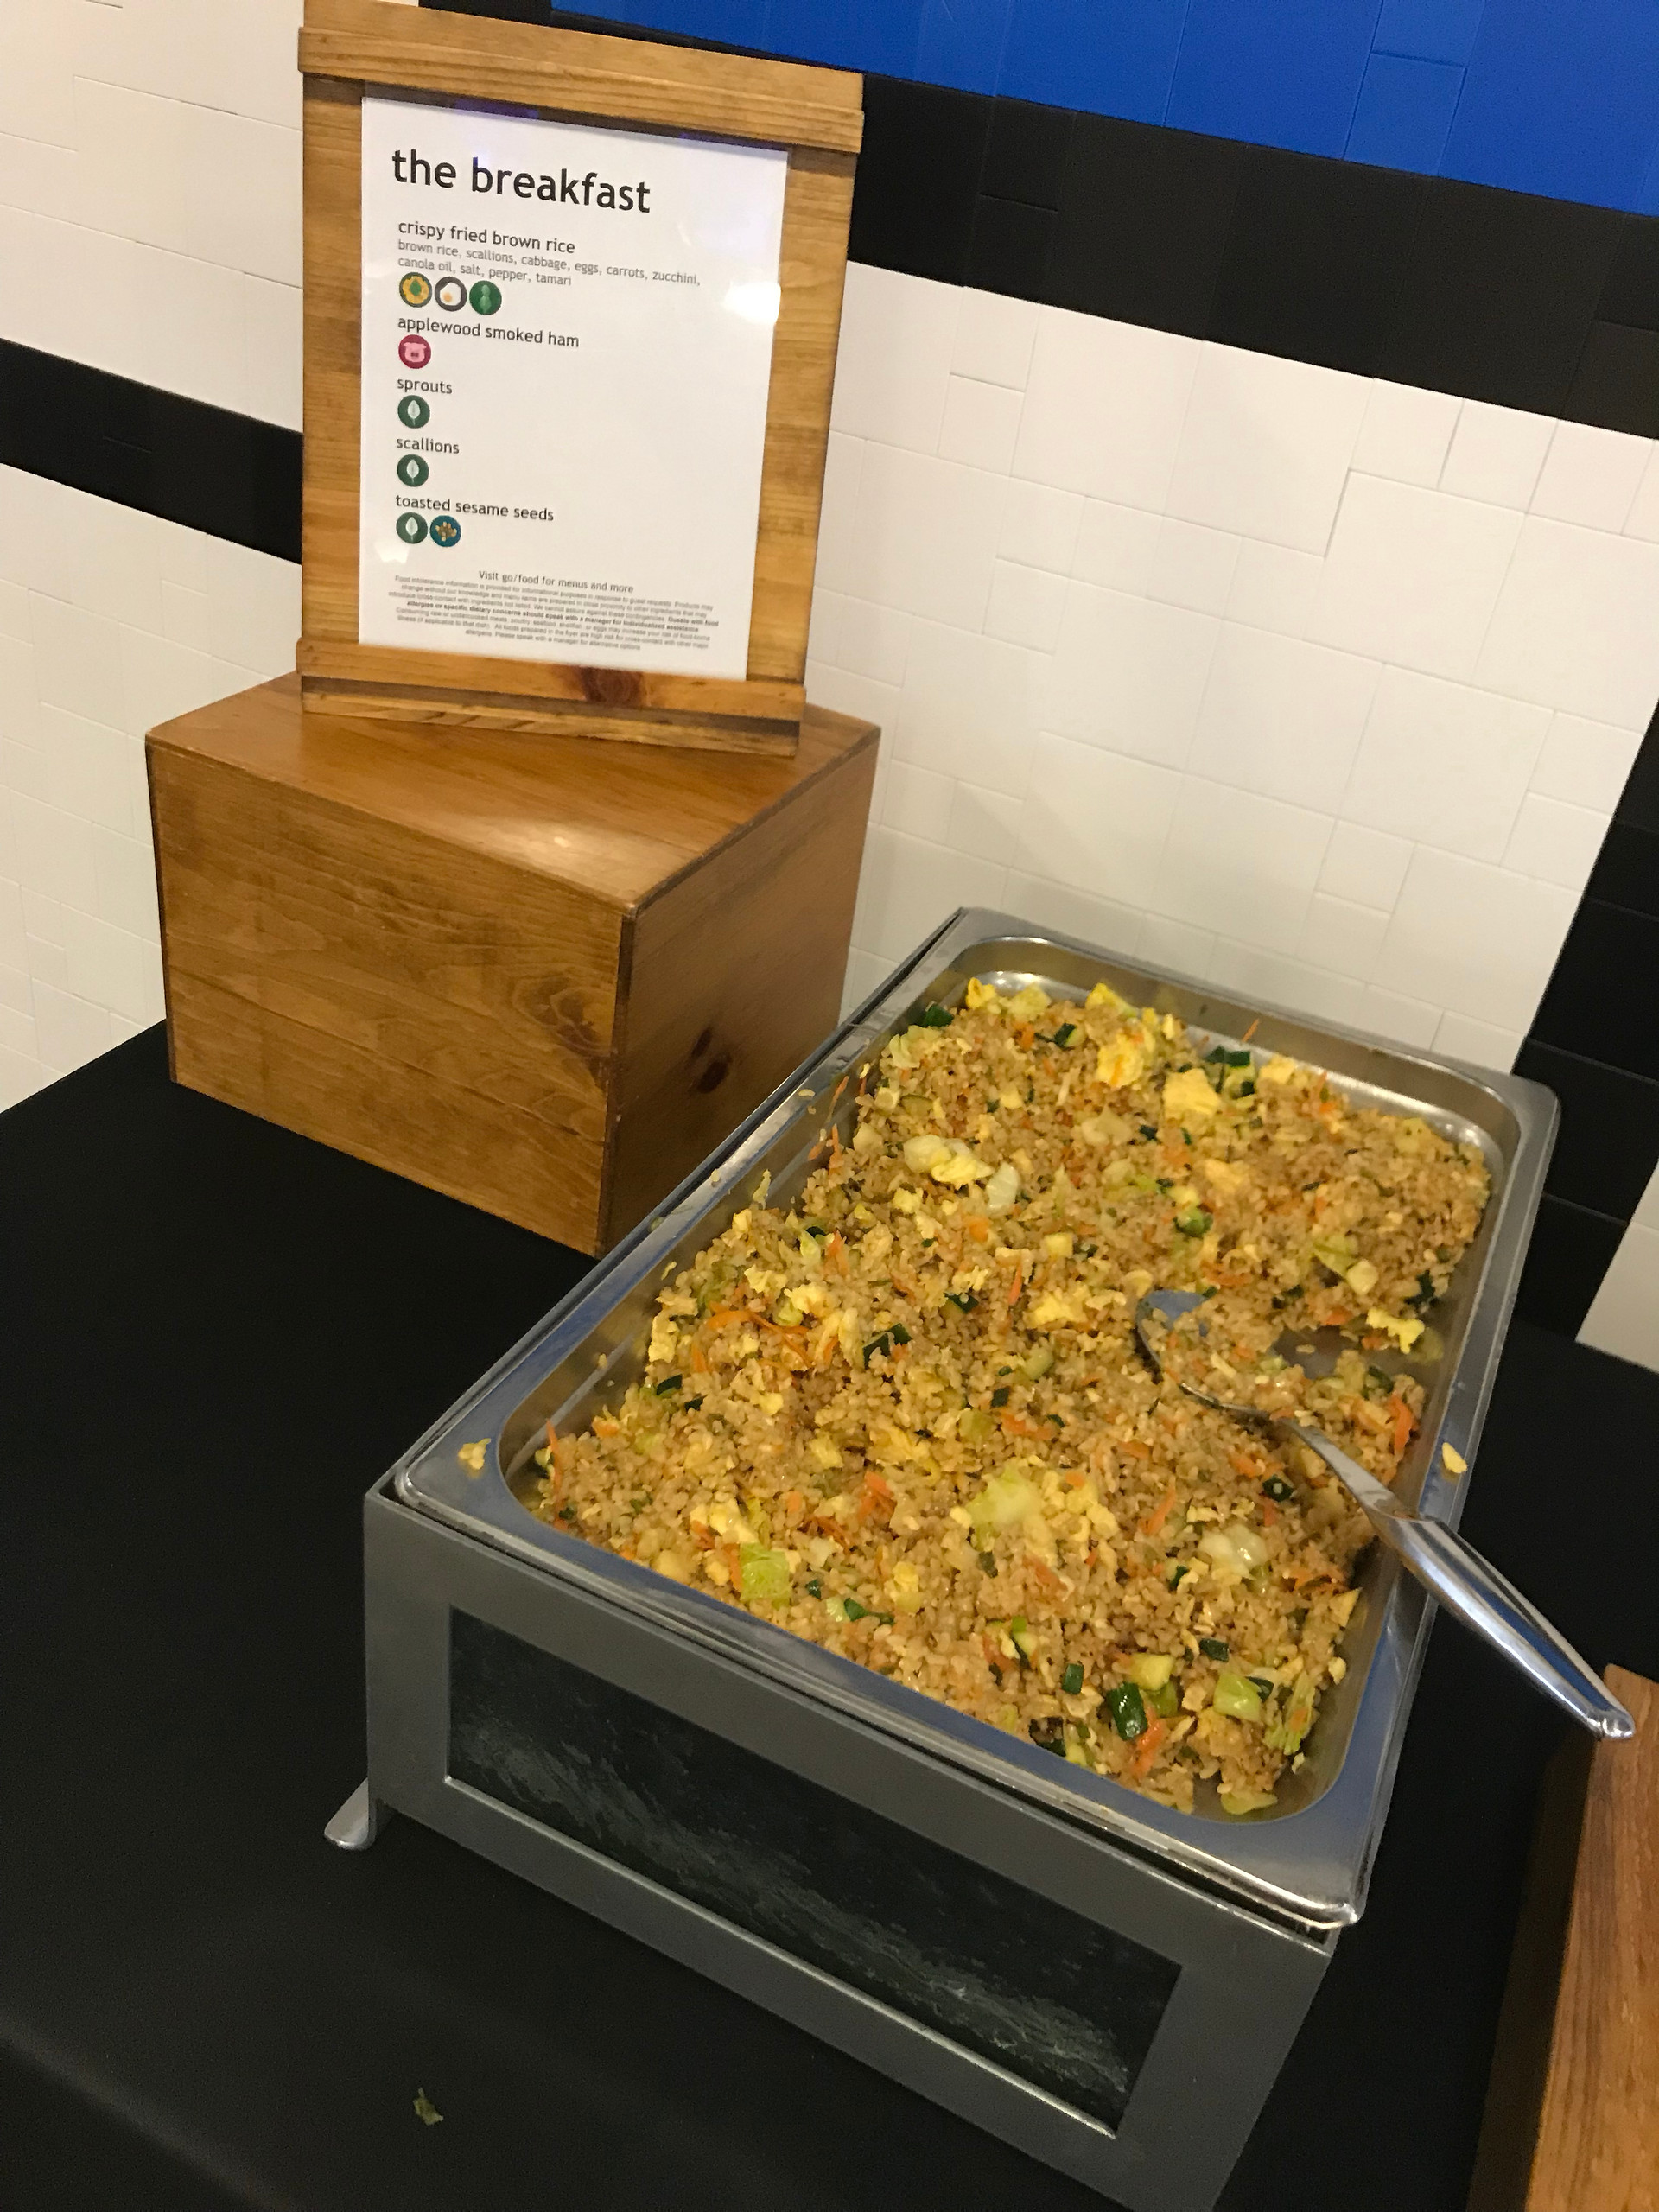
The next step right after the commute involved a short stop into the LinkedIn Learning Cafeteria. On the first day the Cafeteria crew dissuaded me from the morning Starbucks food! The reason was simple, the Cafeteria crew provided some excellent fried rice along with other treats for breakfast. Each subsequent day they provided something else light and energy focused, which sets one up for a productive day of recording.

IMG_4209-X5

IMG_4208-X5

IMG_4207-X5

The LinkedIn Learning Crew

While onsite I got to work with a number of people. From security, who loaned me a lock for the LinkedIn Learning Bike I borrowed for the week, to producers, editors, and stage crew. Everybody, and I do mean ever single person, that I interacted with was helpful, friendly, and one could tell they were enjoying their work. This type of environment really makes it easy to be focused, positive, and set on putting together course material.

My producer sat in with me every day, in the studio, helping me work through the course. Even with material and scripts ready, one always breaks a little bit from whatever one prepares. The recording, timing it takes, and related specifics always makes things just a little different then what one imagines. For instance, I would record something that I originally thought would take 1-2 minutes, and then 4 minutes into it I realized I had much more to say then I had planned. So we switch a few things around, fit it in, add a section, or otherwise.

It’s hard to detail exactly how, once in studio, how many ways the process is actually pretty zen like. Compared to my previous experiences recording courses where I was responsible for every single element including video, editing, production, and other reasons this was a practical vacation of high end professionalism. Every morning, around 9, we’d get started. Most days I just reviewed my material, then dove right into the next section. Before recording, another review to ensure each screen, code snippet, piece of tech was installed and in the correct place just before and after each. This was the flow throughout the week, and it was indeed a good flow.

The biggest thing that sat in my mind during and after this process was how much I’d get to focus on the material instead of toying around with things that aren’t my professional expertise. I had producers, editors, content creators, and others to help out with the slide decks, the flow of content, the actual cutting and editing of video, sound, and the other aspects of recording. These are all things I can do given enough time, but I don’t do them in any professional sense so it takes me the extra time to do them, but these LinkedIn Learning Pros can easily knock this stuff out! The fact I get to focus on core content instead of tweaking the bylines and audio or slide deck pieces is a huge plus to me.

In the end, this was a spectacular trip and honestly the best experience I’ve had recording screencast learning material. Will do it again, and am already working up some new course topics. When the course goes live, I’ll be sure to post a link out to it and related material here on my Composite Thrashing Code blog.

More @ML4ALL Intros: Meet Igor & Carol! Also, the bike ride map!

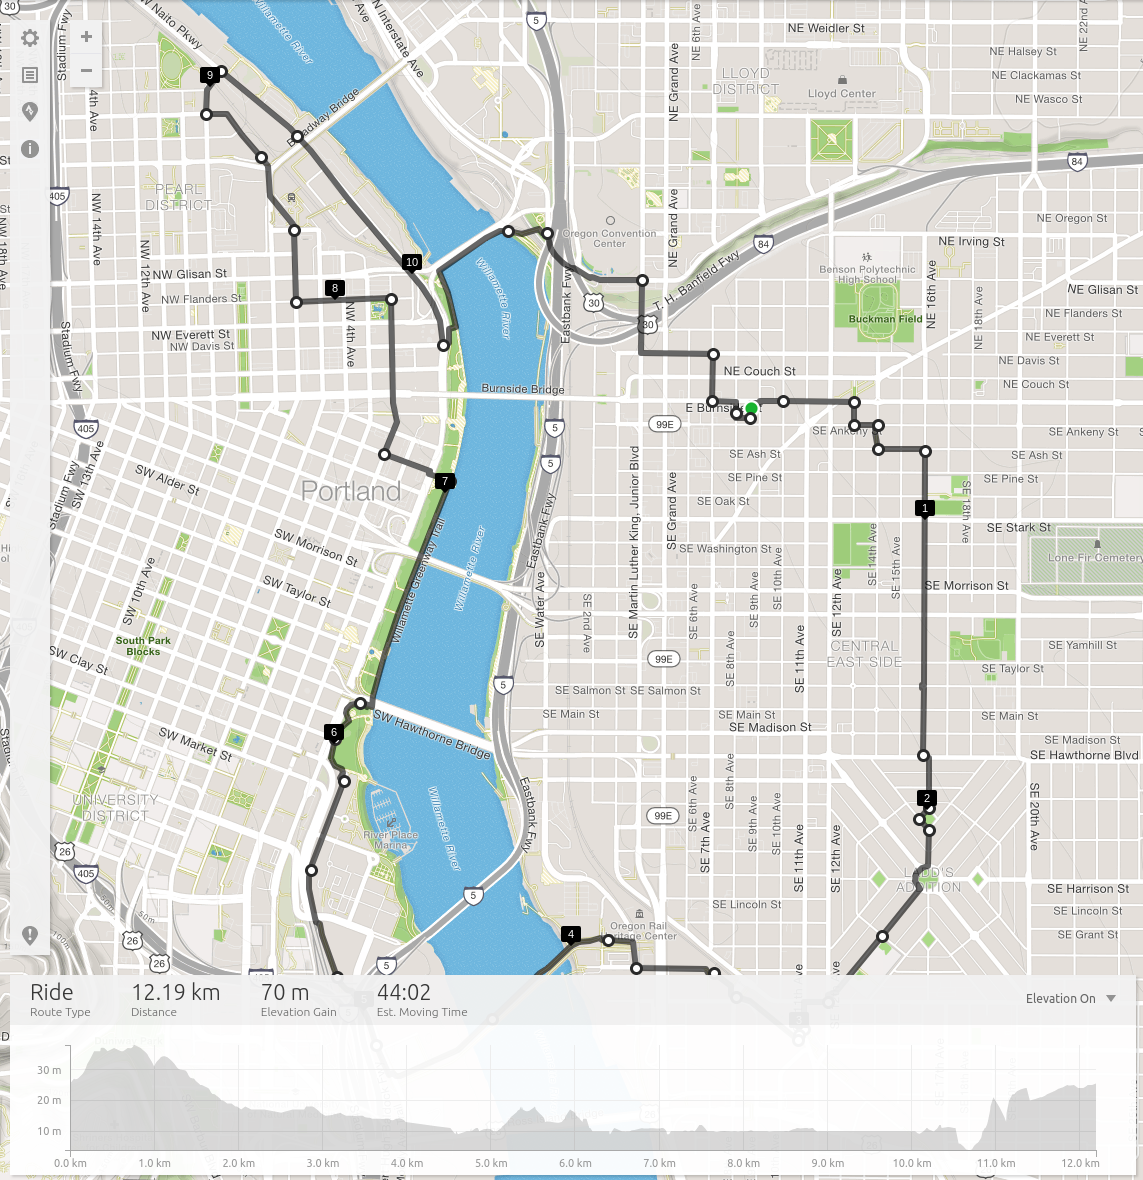
Ride a bike, machine learn the path, have a beer, see Portland, or come to find the artificial intelligence you’ve been looking for on our ML4ALL Ride! Ok, fancy word play aside, we’ll be having a ride the Sunday of the conference in Portland, and I’ve put together the route below. I’ll have more information about the ride real soon and look forward to others joining me for the slow roll. Stay tuned and I’ll have a LOT more details, but now, meet two more of our upcoming speakers; Igor and Carol!

ML4ALL Ride

ML4ALL Ride

igor-dziubaTeach Machine To Teach: Personal Tutor For Language Learners

Have you ever learned a foreign language? If yes, you’ve probably written translations of new words on pieces of paper or saved them in digital text documents. What happened thereafter? I guess you would rarely read these vocabulary lists more than a few times, if ever, but you’d still continue making “new words” lists anyway. Writing down and forgetting, making new lists and forgetting again.

How can we help ourselves learn faster and significantly reduce number of words immediately disappearing from our memory? What if you had someone who would remember all your translation history and prepare for you a list of recommended articles and videos based on words you translated? Let’s explore how Machine Learning can be applied to help simplify the process of learning a new language! In this talk, I will be glad to show you how to implement this kind of recommendation system using Machine Learning!”

Meet Igor Dziuba (@dziubaigor) is a founder of Store Translate, lead Big Data Engineer at EPAM Systems with Scala/Java as primary programming languages.

carol-reileyTBD

Alright, so the talk Carol (@Robot_MD) is going to provide, so far, is top secret! But let me introduce Carol and her work!

Carol is an entrepreneur, roboticist, and executive, currently delving into ideas around AI, healthcare, and diversity. She’s also a cofounder and board member of drive.ai, an artificial intelligence self-driving vehicle startup.

She’s also an NSF Graduate Research Fellow, did her graduate academic research and worked as an instructor of intersession courses at Johns Hopkins University. Not just that, she’s also got eight technical patents, is the author of a dozen plus papers on scientific conference proceedings, refereed journals, and conferences. Needless to say, Carol has a long long long list of awesome accomplishments and cool projects, which you can check out at http://creiley.com.

I’m super stoked to find out what, and see her present at ML4ALL! To checkout ML4ALL and get your tickets navigate over to ML4ALL here!