Schedule Updates: Coding, Meetups, Twitch Streams, Etc. Starting Monday 7th

Another updated schedule for the coming weeks starting September 26th onward.

Series: Thrashing Code General Calamity

This is going to be a mix of tech this week. Probably some database hacking, code hacking, samples, and setup of even more examples for use throughout your coding week!

Series: Meetups!

Series: Emerald City Tech Conversations

Join me and several guests, on several different days to get into particulars about programming, coding, hacking, ops, devops, or whatever comes up. Ask questions, inquire, infer, or inform we’re here for the conversation. Join my guests and I!

Wat?! Ugh Terraform State is Complicated Sometimes! ‘url has no host’

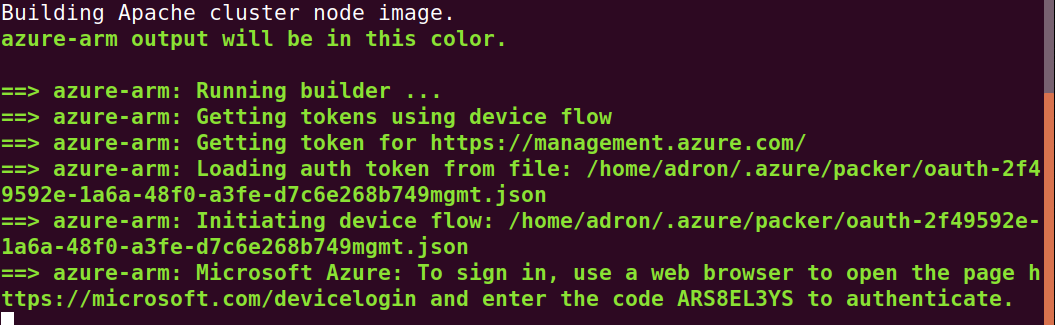
As I’ve been working through the series (part 1, 2, 3, and 4 so far), a number of issues come up (like this one), and this seemed like a good one to post too. As I’ve been working through I started stumbling into this error around destroying images via terraform destroy . Now, I’m not just creating them with terraform apply and then trying to destroy them. I’m creating the images via Packer, then importing the state (see part 4 for the series for details) and then when I clean up the environment trying to terraform destroy which shows this error.

[…lost image…]

I had taken the default azurerm_image resource configuration from the Hashicorp docs site that I tweaked just a little bit.

resource "azurerm_image" "basedse" {
  name = "basedse"
  location = "West US"
  resource_group_name = azurerm_resource_group.imported_adronsimages.name

  os_disk {
    os_type = "Linux"
    os_state = "Generalized"
    blob_uri = "{blob_uri}"
    size_gb = 30
  }
}

The thing causing the error is the “{blog_uri}”. Which in general, I’d assume that this should be pulled or derived from the existing image created by packer when imported. But the syntax above just doesn’t cut it for actions post-import of the image state.

Time Consuming Troubleshooting

To troubleshoot and confirm this issue takes a long time. Create the image, which is ~15-20 minutes, then run an apply. The apply, even if most of the creation is minimized to imports and the few other things that are created, takes several minutes in Azure. Then a destroy takes several minutes. So all in all, one test cycle is about ~30 minutes.

The First Tricky Fix

I went through several iterations of attempting to get that part of the import of the state pulled in. That didn’t work out so well. What did though, was the simplist of actions, I deleted blob_uri = "{blog_uri}"!  Then upon terraform apply or terraform destroy I got a full cycled application of changes, etc, after adding the state and on destroy terraform wiped out everything as expected!

Problem Fixed, Problem Created

On to the next things! But oh wait, there is another problem. Now if I setup a VM to be created based off of the image, the state doesn’t have the blog_uri. Great, back to square one right? Not entirely, subscribe, keep reading and I’ll have the next steps for this coming real soon!

Development Workspace with Terraform on Azure: Part 4 – DSE w/ Packer + Importing State 4 Terraform

The next thing I wanted setup for my development workspace is a DataStax Enterprise Cluster. This will give me all of the Apache Cassandra database features plus a lot of additional features around search, OpsCenter, analytics, and more. I’ll elaborate on that in some future posts. For now, let’s get an image built we can use to add nodes to our cluster and setup some other elements.

1: DataStax Enterprise

The general installation instructions for the process I’m stepping through here in this article can be found in this documentation. To do this I started with a Packer template like the one I setup in the second part of this series. It looks, with the installation steps taken out, just like the code below.

{
  "variables": {
    "client_id": "{{env `TF_VAR_clientid`}}",
    "client_secret": "{{env `TF_VAR_clientsecret`}}",
    "tenant_id": "{{env `TF_VAR_tenant_id`}}",
    "subscription_id": "{{env `TF_VAR_subscription_id`}}",
    "imagename": "",
    "storage_account": "adronsimagestorage",
    "resource_group_name": "adrons-images"
  },

  "builders": [{
    "type": "azure-arm",

    "client_id": "{{user `client_id`}}",
    "client_secret": "{{user `client_secret`}}",
    "tenant_id": "{{user `tenant_id`}}",
    "subscription_id": "{{user `subscription_id`}}",

    "managed_image_resource_group_name": "{{user `resource_group_name`}}",
    "managed_image_name": "{{user `imagename`}}",

    "os_type": "Linux",
      "image_publisher": "Canonical",
      "image_offer": "UbuntuServer",
      "image_sku": "18.04-LTS",

    "azure_tags": {
        "dept": "Engineering",
        "task": "Image deployment"
    },

    "location": "westus2",
    "vm_size": "Standard_DS2_v2"
  }],
  "provisioners": [{
    "execute_command": "chmod +x {{ .Path }}; {{ .Vars }} sudo -E sh '{{ .Path }}'",
    "inline": [
        ""
    ],
    "inline_shebang": "/bin/sh -x",
    "type": "shell"
  }]
}

In the section marked “inline” I setup the steps for installing DataStax Enterprise.

        "apt-get update",
        "apt-get install -y openjdk-8-jre",
        "java -version",
        "apt-get install libaio1",
        "echo \"deb https://debian.datastax.com/enterprise/ stable main\" | sudo tee -a /etc/apt/sources.list.d/datastax.sources.list",
        "curl -L https://debian.datastax.com/debian/repo_key | sudo apt-key add -",
        "apt-get update",
        "apt-get install -y dse-full"

The first part of this process the machine image needs Open JDK installed, which I opted for the required version of 1.8. For more information about the Open JDK check out this material:

The next thing I needed to do was to get everything setup so that I could use this Azure Image to build an actual Virtual Machine. Since this process however is built outside of the primary Terraform main build process, I need to import the various assets that are created for Packer image creation and the actual Packer images. By importing these asset resources into Terraform’s state I can then write configuration and code around them as if I’d created them within the main Terraform build process. This might sound a bit confusing, but check out this process and it might make more sense. If it is still confusing do let me know, ping me on Twitter @adron and I’ll elaborate or edit things so that they read better.

check-box-64Verification Checklist

  • At this point there now exists a solidly installed and baked image available for use to create a Virtual Machine.

2: Terraform State & Terraform Import Resources

Ok, if you check out part 1 of this series I setup Azure CLI, Terraform, and the pertinent configuration and parts to build out infrastructure as code using HCL (Hashicorp Configuration Language) with a little bit of Bash as glue here and there. Then in Part 2 and Part 3 I setup Packer images and some Terraform resources like Kubernetes and such. All of that is great, but these two parts of the process are now in entirely two different unknown states. The two pieces are:

  1. Packer Images
  2. Terraform Infrastructure

The Terraform Infrastructure doesn’t know the Packer Images exist, but they are sitting there in a resource group in Azure. The way to make Terraform aware that these images exist is to import the various things that store the images. To import these resources into the Terraform state, before doing an apply, run the terraform import command.

In order to get all of the resources we need in which to operate and build images, the following import commands need issued. I wrote a script file to help me out with each of these, and used jq to make retrieval of the Packer created Azure Image ID’s a bit easier. That code looks like this:

BASECASSANDRA=$(az image list | jq 'map({name: "basecassandra", id})' | jq -r '.[0].id')
BASEDSE=$(az image list | jq 'map({name: "basedse", id})' | jq -r '.[0].id')

Breaking down the jq commands above, the following actions are being taken. First, the Azure CLI command is issued, az image list which is then piped | into the jq command of jq 'map({name: "theimagenamehere", id})'. This command takes the results of the Azure CLI command and finds the name element with the appropriate image name, matches that and then gets the id along with it. That command is then piped into another command that returns just the value of the id jq -r '.id'. The -r is a switch that tells jq to just return the raw data, without enclosing double quotes.

I also needed to import the resource group all of these are in too, which following a similar jq command style of piping one command’s results into another, issued this command to get the Resource Group ID RG-IMPORT=$(az group show --name adronsimages | jq -r '.id'). With those three ID’s there is one more element needed to be able to import these into Terraform state.

The Terraform resources that these imported pieces of state will map to need declared, which means the Terraform HCL itself needs written out. For that, there are the two images that are needed and the Resource Group. I added the images in an images.tf files and the Resource Group goes in the resource_groups.tf file.

resource "azurerm_image" "basecassandra" {
  name                = "basecassandra"
  location            = "West US"
  resource_group_name = azurerm_resource_group.imported_adronsimages.name

  os_disk {
    os_type  = "Linux"
    os_state = "Generalized"
    blob_uri = "{blob_uri}"
    size_gb  = 30
  }
}

resource "azurerm_image" "basedse" {
  name                = "basedse"
  location            = "West US"
  resource_group_name = azurerm_resource_group.imported_adronsimages.name

  os_disk {
    os_type  = "Linux"
    os_state = "Generalized"
    blob_uri = "{blob_uri}"
    size_gb  = 30
  }
}

Then the Resource Group.

resource "azurerm_resource_group" "imported_adronsimages" {
  name     = "adronsimages"
  location = var.locationlong

  tags = {
    environment = "Development Images"
  }
}

Now, issuing these Terraform commands will pull the current state of those resource into the state, which we can then issue further Terraform commands and applies from.

terraform import azurerm_image.basedse $BASEDSE
terraform import azurerm_image.basecassandra $BASECASSANDRA
terraform import azurerm_resource_group.imported_adronsimages $RG_IMPORT

Running those commands, the results come back something like this.

terraform-imports

Verification Checklist

  • At this point there now exists a solidly installed and baked image available for use to create a Virtual Machine.
  • Now there is also state in Terraform, that understands where and what these resources are.

Summary, for now.

This post is shorter than I’d like it to be. But it was taking to long for the next steps to get written up – but fear not they’re on the way! In the coming post I’ll cover more of other resource elements we’ll need to import, what is next for getting a virtual machine built off of the image that is now available, some Terraform HCL refactoring, and most importantly putting together the actual DataStax Enterprise / Apache Cassandra Clusters! So stay tuned, subscribe to the blog, and of course follow me on the Twitters @Adron.

Development Workspace with Terraform on Azure: Part 3 – Next Step Kubernetes

In part 1 of this series I setup Terraform and put together a basic setup for ongoing use. In part 2 I setup Packer and got a template started that installs Apache Cassandra 3.11.4.

In this part there’s one more key piece. Really key piece for iterating and moving quickly with development needs on a day to day basis. I need some development love with Kubernetes. Terraform is extremely well suited to spin this up in Azure! Since I setup Terraform in part 1 I’ll leave those specifics linked here.

1: Terraform ❤️ Kubernetes

There are a couple of different, and very important aspects to how and what can be done with Kubernetes with Terraform. First, which I’ll cover right here, is the creation of a Kubernetes Cluster. Later I’ll cover more material related to working with the cluster itself and managing the resources within the cluster. To a Kubernetes cluster running with Terraform there’s a singular resource we’ll need to use.

Opening up the project – same as in the previous two blog article in this series – and went straight into the main.tf file in the root and added the follow Kubernetes resource.

resource "azurerm_kubernetes_cluster" "test" {
  name                = "acctestaks1"
  location            = "${azurerm_resource_group.adrons_resource_group_workspace.location}"
  resource_group_name = "${azurerm_resource_group.adrons_resource_group_workspace.name}"
  dns_prefix          = "acctestagent1"

  agent_pool_profile {
    name            = "default"
    count           = 1
    vm_size         = "Standard_D1_v2"
    os_type         = "Linux"
    os_disk_size_gb = 30
  }

  service_principal {
    client_id     = var.clientid
    client_secret = var.clientsecret
  }

  tags = {
    Environment = "Production"
  }
}

output "client_certificate" {
  value = "${azurerm_kubernetes_cluster.test.kube_config.0.client_certificate}"
}

output "kube_config" {
  value = "${azurerm_kubernetes_cluster.test.kube_config_raw}"
}

With that I immediately applied the changes to build the environment with terraform apply and confirming with a yes.

The agent pool profile is what sets up our virtual machines that will make up our Kubernetes Cluster. In this case I’ve selected the Standard_D1_v2 just because that’s the default example, but depending on use case this may need to change. For more information about the various virtual machine sizes in Azure here are a few important links:

The Service Principal as shown is pulled from variable, as setup in part 1 and part 2 of this series.

The two output variables in the section of configuration above will print out the client cert and raw configuration which we’ll need for other uses in the future. Be sure to put both of those somewhere that can be retrieved for future use. Ideally, keep them secure! I’ll speak to this more in future posts, but for now I’m going to focus on this Kubernetes Cluster.

check-box-64Verification Checklist

  • Based on the infrastructure in part 1 and part 2 and this addition, there is now the Packer image for the Apache Cassandra 3.11.4 image, in Azure the Service Principal, Resource Group, and related collateral, and now a Kubernetes Cluster to work with.

2: Kubernetes ❤️ Terraform

Alright, with a Kubernetes (K8s) done, we can now add some more elements to it via Terraform in which to work with. Specifically let’s add a pod and then get an Nginx container up and running.

The first thing we need however is a connection to the cluster that is created in the previous step. In the HCL (HashiCorp Configuration Language) above we setup two output variables. The data in those variables is needed for our ongoing connection to Kubernetes, however we don’t particularly need to pass them via output variables. The reason we don’t need to pass them via variables into another phase of deployment is because Terraform can handle the creation of a Kubernetes cluster and the post-creation processing of creating pods and related collateral in the order it needs to occur. Since Terraform knows how to do this, there is a way to setup the connection information for the Kubernetes Provider that prevents us from needing to post output variables. Before moving on those should be removed. Once that is done add the follow provider for Kubernetes.

provider "kubernetes" {
  host                   = "${azurerm_kubernetes_cluster.test.kube_config.0.host}"
  username               = "${azurerm_kubernetes_cluster.test.kube_config.0.username}"
  password               = "${azurerm_kubernetes_cluster.test.kube_config.0.password}"
  client_certificate     = "${base64decode(azurerm_kubernetes_cluster.test.kube_config.0.client_certificate)}"
  client_key             = "${base64decode(azurerm_kubernetes_cluster.test.kube_config.0.client_key)}"
  cluster_ca_certificate = "${base64decode(azurerm_kubernetes_cluster.test.kube_config.0.cluster_ca_certificate)}"
}

In this section of configuration the host is set from the previously created Kubernetes Cluster, then the username and password, then the certificates, and key. Each of these, as you can see, is pulled from the Kubernetes Cluster resource (azurerm_kubernetes_cluster) and then from the test cluster that was created. With this addition run terraform init to get the provider downloaded and ready for use.

With the connection now set, the provider downloaded, the next step is to add the Kubernetes Pod that we’ll need to run the Nginx container. Hat tip to the HashiCorp docs for this specific example.

resource "kubernetes_pod" "nginx" {
  metadata {
    name = "nginx-example"
    labels = {
      App = "nginx"
    }
  }

  spec {
    container {
      image = "nginx:1.7.8"
      name  = "example"

      port {
        container_port = 80
      }
    }
  }
}

This will setup a pod that uses and runs a nginx:1.7.8 container image and makes it available on port 80. To make this container available as a service however there is one more step, to create a Kubernetes Service that’ll make port 80 available and mapped to the container within Kubernetes.

resource "kubernetes_service" "nginx" {
  metadata {
    name = "nginx-example"
  }
  spec {
    selector = {
      App = kubernetes_pod.nginx.metadata[0].labels.App
    }
    port {
      port        = 80
      target_port = 80
    }

    type = "LoadBalancer"
  }
}

Alright, now the setup is almost 100% complete. The last step is to create another output variable that’ll provide a way for us to navigate to and make requests against the Nginx service, we’ll need either the IP or the hostname. Depending on the cloud provider one or other other can be retrieved by asking for the load_balancer_ingress[0].ip value or the load_balancer_ingress[0].hostname. For Azure and GCP, one can retrieve the IP, for AWS you’d want to specifically get the hostname.

In the end the HCL looks like this.

provider "azurerm" {
  version = "=1.27.0"

  subscription_id = var.subscription_id
  tenant_id       = var.tenant_id

}

provider "kubernetes" {
  host                   = "${azurerm_kubernetes_cluster.test.kube_config.0.host}"
  username               = "${azurerm_kubernetes_cluster.test.kube_config.0.username}"
  password               = "${azurerm_kubernetes_cluster.test.kube_config.0.password}"
  client_certificate     = "${base64decode(azurerm_kubernetes_cluster.test.kube_config.0.client_certificate)}"
  client_key             = "${base64decode(azurerm_kubernetes_cluster.test.kube_config.0.client_key)}"
  cluster_ca_certificate = "${base64decode(azurerm_kubernetes_cluster.test.kube_config.0.cluster_ca_certificate)}"
}

resource "azurerm_resource_group" "adrons_resource_group_workspace" {
  name     = "adrons_workspace"
  location = "West US 2"

  tags = {
    environment = "Development"
  }
}

resource "azurerm_kubernetes_cluster" "test" {
  name                = "acctestaks1"
  location            = "${azurerm_resource_group.adrons_resource_group_workspace.location}"
  resource_group_name = "${azurerm_resource_group.adrons_resource_group_workspace.name}"
  dns_prefix          = "acctestagent1"

  agent_pool_profile {
    name            = "default"
    count           = 1
    vm_size         = "Standard_D1_v2"
    os_type         = "Linux"
    os_disk_size_gb = 30
  }

  service_principal {
    client_id     = var.clientid
    client_secret = var.clientsecret
  }

  tags = {
    Environment = "Production"
  }
}

resource "kubernetes_pod" "nginx" {
  metadata {
    name = "nginx-example"
    labels = {
      App = "nginx"
    }
  }

  spec {
    container {
      image = "nginx:1.7.8"
      name  = "example"

      port {
        container_port = 80
      }
    }
  }
}

resource "kubernetes_service" "nginx" {
  metadata {
    name = "nginx-example"
  }
  spec {
    selector = {
      App = kubernetes_pod.nginx.metadata[0].labels.App
    }
    port {
      port        = 80
      target_port = 80
    }

    type = "LoadBalancer"
  }
}

output "lb_ip" {
  value = kubernetes_service.nginx.load_balancer_ingress[0].ip
}
output "lb_hostname" {
value =
}

You can also check out this specific iteration of my developer workspace project on Github at the example-nginx-pod-on-kubernetes branch.

Verification Checklist

  • Based on the infrastructure in part 1 and part 2 and this addition, there is now the Packer image for the Apache Cassandra 3.11.4 image, in Azure the Service Principal, Resource Group, and related collateral, and now a Kubernetes Cluster to work with.
  • With this second segment done, there is now a pod running an nginx container. The container is then running as a service with a port mapping for port 80.

Summary

At this point in the series there are enough elements to really start to get some work done deploying, building some applications, and getting some databases deployed! So subscribe here to the blog, follow me at @Adron on Twitter, @adronhall on Twitch (for even more coding), and subscribe to my YouTube channel here. More material coming about how to get all of this wired together and running, until next post, cheers!
Schedule Updates: Coding, Meetups, Twitch Streams, Etc.

Another updated schedule for the coming weeks starting September 26th onward.

Series: Thrashing Code General Calamity

This is going to be a mix of tech this week. Probably some database hacking, code hacking, samples, and setup of even more examples for use throughout your coding week!

Series: Emerald City Tech Conversations

Join me and several guests, on several different days to get into particulars about programming, coding, hacking, ops, devops, or whatever comes up. Ask questions, inquire, infer, or inform we’re here for the conversation. Join my guests and I!

Series: DataStax’s Apache Cassandra and DSE C# Hour

I’ll probably have a few additions over the next couple of days, but for now, this is the bulk of content and coding coming up in the next couple of weeks! See ya in the code!