Go Concurrency Patterns(Fan-out/Fan-in Pattern)

Overview

The Fan-out/Fan-in pattern is a concurrency pattern that distributes work across multiple workers (fan-out) and then collects results from all workers (fan-in). This pattern is essential for parallel processing of independent tasks, load balancing, and improving throughput for CPU-intensive operations.

NOTE: For other posts on concurrency patterns, check out the index post to this series of concurrency patterns.

Implementation Details

Structure

The fan-out/fan-in implementation in examples/fan.go consists of three main components:

  1. Work Generation – Creates work items to be processed
  2. Fan-out – Distributes work across multiple workers
  3. Fan-in – Collects results from all workers

Code Analysis

func RunFan() {
    // Generate work items
    workItems := generateWorkItems(20)

    // Fan out: Distribute work across multiple workers
    numWorkers := 4
    results := fanOut(workItems, numWorkers)

    // Fan in: Collect results from all workers
    finalResults := fanIn(results)

    // Collect and display results
    for result := range finalResults {
        fmt.Printf("Processed: Item %d -> %s (by Worker %d)\n",
                   result.OriginalID, result.Processed, result.WorkerID)
    }
}

Code Breakdown:

  1. Work Generation: generateWorkItems(20) creates a channel containing 20 work items. This simulates a real-world scenario where you have a stream of data to process.
  2. Fan-out Phase: fanOut(workItems, numWorkers) launches 4 worker goroutines, each consuming from the same workItems channel. This distributes the workload across multiple concurrent workers.
  3. Fan-in Phase: fanIn(results) takes the individual result channels from each worker and merges them into a single output channel. This consolidates all results for processing.
  4. Result Processing: The final loop consumes results from the merged channel as they become available, displaying which worker processed each item.

Work Item Structure

type WorkItem struct {
    ID   int
    Data string
}

type Result struct {
    OriginalID int
    Processed  string
    WorkerID   int
}

Structure explanation:

  • WorkItem: Represents a single unit of work to be processed
    • ID: Unique identifier for tracking and debugging
    • Data: The actual data to be processed (could be a file path, URL, etc.)
  • Result: Contains the processed output and metadata
    • OriginalID: Links the result back to the original work item
    • Processed: The transformed/processed data
    • WorkerID: Identifies which worker processed this item (useful for debugging and load analysis)

Fan-out Implementation

func fanOut(jobs <-chan WorkItem, numWorkers int) []<-chan Result {
    var workers []chan Result
    var wg sync.WaitGroup

    // Create workers
    for i := 0; i < numWorkers; i++ {
        workerResults := make(chan Result)
        workers = append(workers, workerResults)

        wg.Add(1)
        go worker(i+1, jobs, workerResults, &wg)
    }

    // Close worker result channels when all workers are done
    go func() {
        wg.Wait()
        for _, workerChan := range workers {
            close(workerChan)
        }
    }()

    // Convert to read-only channels for return
    var resultChannels []<-chan Result
    for _, ch := range workers {
        resultChannels = append(resultChannels, ch)
    }

    return resultChannels
}

Detailed breakdown of fan-out:

  1. Worker Creation Loop:
    • Creates numWorkers individual result channels (one per worker)
    • Each worker gets its own channel to prevent blocking between workers
    • Uses sync.WaitGroup to track when all workers complete
  2. Goroutine Launch:
    • go worker(i+1, jobs, workerResults, &wg) starts each worker concurrently
    • All workers share the same jobs channel (fan-out)
    • Each worker writes to its own workerResults channel
  3. Cleanup Goroutine:
    • Runs in background to wait for all workers to finish
    • Closes each worker’s result channel when all work is complete
    • Prevents deadlocks and ensures proper resource cleanup
  4. Channel Type Conversion:
    • Converts internal chan Result to <-chan Result (read-only)
    • Provides encapsulation – callers can only read from channels
    • Prevents external code from accidentally closing worker channels

Worker Implementation

func worker(id int, jobs <-chan WorkItem, results chan<- Result, wg *sync.WaitGroup) {
    defer wg.Done()

    for job := range jobs {
        // Simulate processing work
        time.Sleep(time.Duration(rand.Intn(200)+100) * time.Millisecond)

        result := Result{
            OriginalID: job.ID,
            Processed:  fmt.Sprintf("processed-%s-by-worker-%d", job.Data, id),
            WorkerID:   id,
        }

        fmt.Printf("Worker %d processed item %d\n", id, job.ID)
        results <- result
    }
}

Worker function breakdown:

  1. Function Signature:
    • id: Unique worker identifier for tracking and debugging
    • jobs <-chan WorkItem: Read-only channel for receiving work
    • results chan<- Result: Write-only channel for sending results
    • wg *sync.WaitGroup: For signaling completion
  2. Resource Management:
    • defer wg.Done() ensures the worker signals completion even if it panics
    • Automatic cleanup when the function exits
  3. Work Processing Loop:
    • for job := range jobs continuously processes jobs until the channel closes
    • Each worker competes for jobs from the shared channel (automatic load balancing)
    • When the jobs channel closes, all workers naturally exit the loop
  4. Simulated Processing:
    • time.Sleep(time.Duration(rand.Intn(200)+100) * time.Millisecond) simulates variable processing time
    • Random delay between 100-300ms mimics real-world processing variance
    • Makes concurrency visible in output (workers process at different speeds)
  5. Result Creation and Sending:
    • Creates a Result struct with original ID, processed data, and worker ID
    • results <- result sends the result to the worker’s dedicated channel
    • Non-blocking because each worker has its own channel

Fan-in Implementation

func fanIn(inputs []<-chan Result) <-chan Result {
    out := make(chan Result)
    var wg sync.WaitGroup

    // Function to forward results from one input channel
    forward := func(c <-chan Result) {
        defer wg.Done()
        for result := range c {
            out <- result
        }
    }

    wg.Add(len(inputs))
    for _, input := range inputs {
        go forward(input)
    }

    // Close output channel when all inputs are done
    go func() {
        wg.Wait()
        close(out)
    }()

    return out
}

Fan-in function breakdown:

  1. Setup:
    • Creates a single output channel out that will receive all results
    • Uses sync.WaitGroup to track when all forwarding goroutines complete
  2. Forward Function:
    • forward is a closure that forwards results from one input channel
    • defer wg.Done() ensures proper cleanup
    • for result := range c reads all results from its assigned input channel
    • out <- result forwards each result to the unified output channel
  3. Goroutine Launch:
    • Launches one goroutine per input channel using go forward(input)
    • Each goroutine handles one worker’s results independently
    • Non-blocking – if one worker is slow, others can still forward results
  4. Cleanup Goroutine:
    • Waits for all forwarding goroutines to complete
    • Closes the output channel when all inputs are exhausted
    • Prevents deadlocks and signals to consumers that no more results are coming
  5. Return Value:
    • Returns <-chan Result (read-only) for encapsulation
    • Callers can only consume results, not close the channel

How It Works

  1. Work Generation: Creates a stream of work items to be processed
  2. Fan-out: Launches multiple worker goroutines, each consuming from the same job channel
  3. Worker Processing: Each worker processes jobs independently and sends results to its own result channel
  4. Fan-in: Multiple goroutines forward results from worker channels to a single output channel
  5. Result Collection: The main function consumes all results from the fan-in channel

The pattern enables true parallel processing – multiple workers can process different jobs simultaneously, and results are collected as they complete.

Why This Implementation?

Channel-based Distribution

  • Automatic Load Balancing: Workers naturally consume jobs as they become available
  • Backpressure: If workers are slow, the job channel provides natural backpressure
  • Fair Distribution: All workers have equal access to jobs

Individual Result Channels

  • Isolation: Each worker has its own result channel, preventing blocking
  • Order Independence: Results can be collected in any order
  • Scalability: Easy to add or remove workers

WaitGroup Synchronization

  • Proper Cleanup: Ensures all workers complete before closing channels
  • Resource Management: Prevents goroutine leaks
  • Coordinated Shutdown: All workers finish before fan-in completes

Goroutine-per-Forward

  • Non-blocking Collection: Each worker’s results are forwarded independently
  • Concurrent Collection: Results are collected as soon as they’re available
  • Efficient Resource Usage: No worker blocks waiting for others

Key Design Decisions

  1. Shared Job Channel: All workers read from the same job channel, providing automatic load balancing
  2. Individual Result Channels: Each worker has its own result channel to prevent blocking
  3. Read-only Channel Returns: The fan-out function returns read-only channels for safety
  4. Simulated Processing Time: Random delays simulate real work and make concurrency visible
  5. Structured Results: Results include metadata about which worker processed each item

Common Use Cases

Parallel Data Processing

  • Image Processing: Process multiple images simultaneously
  • Document Processing: Parse, analyze, or transform multiple documents
  • Data Validation: Validate large datasets across multiple workers

API Request Handling

  • Microservice Calls: Make concurrent API calls to multiple services
  • Data Aggregation: Fetch data from multiple sources simultaneously
  • Load Testing: Simulate multiple concurrent users

Batch Processing

  • File Processing: Process multiple files in parallel
  • Database Operations: Execute multiple queries concurrently
  • Report Generation: Generate multiple reports simultaneously

Real-time Systems

  • Sensor Data Processing: Process data from multiple sensors
  • Log Analysis: Analyze logs from multiple sources
  • Monitoring: Collect metrics from multiple systems

Machine Learning

  • Model Training: Train multiple models in parallel
  • Feature Processing: Process features across multiple workers
  • Hyperparameter Tuning: Test multiple parameter combinations

The fan-out/fan-in pattern is particularly effective when you have independent tasks that can be processed in parallel and when you want to maximize resource utilization while maintaining result collection order.

The final example implementation looks like this:

package examples

import (
	"fmt"
	"math/rand"
	"sync"
	"time"
)

// Fan demonstrates the fan-out/fan-in pattern
func RunFan() {
	fmt.Println("=== Fan-out/Fan-in Pattern Example ===")

	// Generate work items
	workItems := generateWorkItems(20)

	// Fan out: Distribute work across multiple workers
	numWorkers := 4
	results := fanOut(workItems, numWorkers)

	// Fan in: Collect results from all workers
	finalResults := fanIn(results)

	fmt.Printf("Distributing %d work items across %d workers...\n", 20, numWorkers)
	fmt.Println()

	// Collect and display results
	count := 0
	for result := range finalResults {
		fmt.Printf("Processed: Item %d -> %s (by Worker %d)\n", result.OriginalID, result.Processed, result.WorkerID)
		count++
	}

	fmt.Printf("\nFan-out/Fan-in completed! Processed %d items.\n", count)
}

// WorkItem represents a unit of work
type WorkItem struct {
	ID   int
	Data string
}

// Result represents the processed work item
type Result struct {
	OriginalID int
	Processed  string
	WorkerID   int
}

// Generate work items
func generateWorkItems(count int) <-chan WorkItem {
	out := make(chan WorkItem)
	go func() {
		defer close(out)
		for i := 0; i < count; i++ {
			item := WorkItem{
				ID:   i,
				Data: fmt.Sprintf("data-%d", i),
			}
			fmt.Printf("Generated work item: %d\n", i)
			out <- item
			time.Sleep(50 * time.Millisecond)
		}
	}()
	return out
}

// Worker function that processes work items
func worker(id int, jobs <-chan WorkItem, results chan<- Result, wg *sync.WaitGroup) {
	defer wg.Done()

	for job := range jobs {
		// Simulate processing work
		time.Sleep(time.Duration(rand.Intn(200)+100) * time.Millisecond)

		result := Result{
			OriginalID: job.ID,
			Processed:  fmt.Sprintf("processed-%s-by-worker-%d", job.Data, id),
			WorkerID:   id,
		}

		fmt.Printf("Worker %d processed item %d\n", id, job.ID)
		results <- result
	}
}

// Fan out: Distribute work across multiple workers
func fanOut(jobs <-chan WorkItem, numWorkers int) []<-chan Result {
	var workers []chan Result
	var wg sync.WaitGroup

	// Create workers
	for i := 0; i < numWorkers; i++ {
		workerResults := make(chan Result)
		workers = append(workers, workerResults)

		wg.Add(1)
		go worker(i+1, jobs, workerResults, &wg)
	}

	// Close worker result channels when all workers are done
	go func() {
		wg.Wait()
		for _, workerChan := range workers {
			close(workerChan)
		}
	}()

	// Convert to read-only channels for return
	var resultChannels []<-chan Result
	for _, ch := range workers {
		resultChannels = append(resultChannels, ch)
	}

	return resultChannels
}

// Fan in: Collect results from multiple channels
func fanIn(inputs []<-chan Result) <-chan Result {
	out := make(chan Result)
	var wg sync.WaitGroup

	// Function to forward results from one input channel
	forward := func(c <-chan Result) {
		defer wg.Done()
		for result := range c {
			out <- result
		}
	}

	wg.Add(len(inputs))
	for _, input := range inputs {
		go forward(input)
	}

	// Close output channel when all inputs are done
	go func() {
		wg.Wait()
		close(out)
	}()

	return out
}

To run this example, and build the code yourself, check out this and other examples in the go-fluency-concurrency-model-patterns repo. That’s it for this topic, tomorrow I’ll post on the worker pools pattern.
Go Concurrency Patterns(Pipeline Pattern)

Overview

The Pipeline pattern is a fundamental concurrency pattern that connects multiple stages of processing where each stage processes data and passes it to the next stage. This pattern is particularly useful for data transformation workflows, stream processing, and multi-step computations.

NOTE: For other posts on concurrency patterns, check out the index post to this series of concurrency patterns.

Implementation Details

Structure

The pipeline implementation in examples/pipeline.go consists of three main stages:

  1. Generate Numbers – Creates random numbers
  2. Square Numbers – Squares each number
  3. Add Ten – Adds 10 to each squared number

Each of these just provides an example of what a workload would look like within the overall pipeline.

Code Analysis

func RunPipeline() {
    // Stage 1: Generate numbers
    numbers := generateNumbers(10)

    // Stage 2: Square the numbers
    squared := square(numbers)

    // Stage 3: Add 10 to each number
    result := addTen(squared)

    // Collect and display results
    for num := range result {
        fmt.Printf("Result: %d\n", num)
    }
}

Step-by-step breakdown:

  1. Stage 1: Number Generation:
    • numbers := generateNumbers(10) creates the first stage of the pipeline
    • The function returns a channel that will receive 10 random numbers
    • This stage runs in its own goroutine and generates data asynchronously
    • The channel provides the connection to the next stage
  2. Stage 2: Number Squaring:
    • squared := square(numbers) creates the second stage of the pipeline
    • Takes the output channel from Stage 1 as input
    • Squares each number as it receives it from the previous stage
    • Returns a new channel with the squared results
  3. Stage 3: Adding Ten:
    • result := addTen(squared) creates the third stage of the pipeline
    • Takes the output channel from Stage 2 as input
    • Adds 10 to each squared number
    • Returns the final channel with the processed results
  4. Result Collection:
    • for num := range result consumes all results from the final stage
    • The range loop automatically exits when the channel is closed
    • fmt.Printf("Result: %d\n", num) displays each final result
    • This is the consumer that drives the entire pipeline

Stage Implementation

Each stage follows the same pattern:

func generateNumbers(count int) <-chan int {
    out := make(chan int)
    go func() {
        defer close(out)
        for i := 0; i < count; i++ {
            num := rand.Intn(10) + 1
            fmt.Printf("Generated: %d\n", num)
            out <- num
            time.Sleep(100 * time.Millisecond) // Simulate work
        }
    }()
    return out
}

Stage implementation breakdown:

  1. Function Signature:
    • func generateNumbers(count int) <-chan int defines a function that returns a read-only channel
    • count int specifies how many numbers to generate
    • <-chan int indicates the function returns a channel that can only be read from
    • This provides encapsulation – callers can only consume, not produce
  2. Channel Creation:
    • out := make(chan int) creates an unbuffered channel for output
    • Unbuffered channels provide natural synchronization between stages
    • Each stage waits for the next stage to be ready before sending data
    • This creates a natural flow control mechanism
  3. Goroutine Launch:
    • go func() { ... }() launches the stage processing in a background goroutine
    • This allows the function to return immediately while processing continues
    • The stage runs independently and can process data concurrently with other stages
    • This is the key to achieving true pipeline concurrency
  4. Resource Management:
    • defer close(out) ensures the output channel is closed when the goroutine exits
    • This signals to downstream stages that no more data is coming
    • Proper cleanup prevents goroutine leaks and channel deadlocks
    • The defer statement guarantees cleanup even if the function panics
  5. Data Generation Loop:
    • for i := 0; i < count; i++ generates exactly the specified number of items
    • num := rand.Intn(10) + 1 creates random numbers between 1 and 10
    • fmt.Printf("Generated: %d\n", num) logs the generation for debugging
    • out <- num sends the number to the output channel
  6. Work Simulation:
    • time.Sleep(100 * time.Millisecond) simulates processing time
    • This makes the concurrent nature of the pipeline visible
    • Without this delay, the pipeline would run too fast to observe
    • The delay also demonstrates how stages can work at different speeds

Pipeline Flow

Let’s trace through a single number’s journey through the pipeline:

  1. Stage 1 (Generate): Creates number 7, sends to Stage 2
  2. Stage 2 (Square): Receives 7, squares it to 49, sends to Stage 3
  3. Stage 3 (Add Ten): Receives 49, adds 10 to get 59, sends to consumer
  4. Consumer: Receives 59 and displays “Result: 59”

While this is happening, Stage 1 can already be generating the next number, creating true concurrency.

Concurrent Processing Benefits

The pipeline pattern enables several key benefits:

  1. Overlapped Processing: While Stage 2 is squaring number 7, Stage 1 can be generating number 3
  2. Resource Utilization: Multiple CPU cores can be utilized simultaneously
  3. Throughput: Overall processing time is reduced compared to sequential processing
  4. Scalability: Each stage can be optimized or scaled independently

Channel-based Synchronization

The unbuffered channels provide natural synchronization:

  • Stage 1 blocks when sending if Stage 2 isn’t ready to receive
  • Stage 2 blocks when sending if Stage 3 isn’t ready to receive
  • Stage 3 blocks when sending if the consumer isn’t ready to receive
  • This creates a natural backpressure mechanism that prevents memory buildup

Error Handling and Cleanup

The pipeline design includes several safety features:

  1. Deferred Channel Closing: Each stage properly closes its output channel
  2. Goroutine Management: Each stage runs in its own goroutine for isolation
  3. Resource Cleanup: Channels are automatically cleaned up by Go’s garbage collector
  4. Flow Control: Unbuffered channels prevent memory leaks from unbounded buffering

Key Design Patterns:

  1. Channel-based Communication: Each stage communicates through channels, providing natural backpressure and synchronization.
  2. Goroutine-per-Stage: Each stage runs in its own goroutine, enabling true concurrent processing.
  3. Unbuffered Channels: Ensures each stage processes one item at a time and provides natural flow control.
  4. Deferred Channel Closing: Each stage properly closes its output channel when done, signaling completion to downstream stages.
  5. Read-only Channel Returns: Functions return <-chan int for encapsulation and safety.
  6. Simulated Work: The time.Sleep() calls simulate real processing time, making the concurrent nature more visible.
  7. Pipeline Composition: Stages can be easily composed and modified without affecting other stages.

How It Works

  1. Stage 1 starts generating random numbers and sending them to its output channel
  2. Stage 2 receives numbers from Stage 1, squares them, and sends results to its output channel
  3. Stage 3 receives squared numbers, adds 10, and sends final results
  4. Main function consumes the final results from Stage 3

The pipeline processes data concurrently – while Stage 2 is processing the first number, Stage 1 can be generating the second number, and so on.

Why This Implementation?

Channel-based Design

  • Natural Flow Control: Channels provide built-in backpressure
  • Thread Safety: Channels handle synchronization automatically
  • Composability: Easy to add/remove stages or modify processing logic

Goroutine-per-Stage

  • True Concurrency: Each stage can process independently
  • Resource Efficiency: Better CPU utilization
  • Scalability: Can easily scale individual stages

Unbuffered Channels

  • Synchronization: Ensures proper coordination between stages
  • Memory Efficiency: No buffering overhead
  • Predictable Flow: Each stage processes one item at a time

Common Use Cases

I wrote these up via bullet points just so you, dear reader, could have a quick list to review and put to memory.

Data Processing Pipelines

  • ETL (Extract, Transform, Load): Extract data from source, transform it, load to destination
  • Image Processing: Resize → Filter → Compress → Save
  • Text Processing: Parse → Clean → Analyze → Generate Report

Stream Processing

  • Log Processing: Parse → Filter → Aggregate → Store
  • Sensor Data: Collect → Validate → Process → Alert
  • Financial Data: Receive → Validate → Calculate → Store

API Processing

  • Request Pipeline: Authenticate → Validate → Process → Respond
  • Data Pipeline: Fetch → Transform → Cache → Return

Real-time Systems

  • IoT Data: Collect → Process → Analyze → Act
  • Trading Systems: Receive → Validate → Execute → Confirm
  • Monitoring: Collect → Analyze → Alert → Log

The pipeline pattern is particularly effective when you have a series of transformations that can be performed independently and when you want to maximize throughput through concurrent processing.

The final example implementation looks like this:

package examples

import (
	"fmt"
	"math/rand"
	"time"
)

// Pipeline demonstrates a multi-stage data processing pipeline
func RunPipeline() {
	fmt.Println("=== Pipeline Pattern Example ===")

	// Stage 1: Generate numbers
	numbers := generateNumbers(10)

	// Stage 2: Square the numbers
	squared := square(numbers)

	// Stage 3: Add 10 to each number
	result := addTen(squared)

	// Collect and display results
	fmt.Println("Pipeline stages:")
	fmt.Println("1. Generate numbers")
	fmt.Println("2. Square numbers")
	fmt.Println("3. Add 10")
	fmt.Println()

	for num := range result {
		fmt.Printf("Result: %d\n", num)
	}

	fmt.Println("Pipeline completed!")
}

// Stage 1: Generate random numbers
func generateNumbers(count int) <-chan int {
	out := make(chan int)
	go func() {
		defer close(out)
		for i := 0; i < count; i++ {
			num := rand.Intn(10) + 1
			fmt.Printf("Generated: %d\n", num)
			out <- num
			time.Sleep(100 * time.Millisecond) // Simulate work
		}
	}()
	return out
}

// Stage 2: Square the numbers
func square(in <-chan int) <-chan int {
	out := make(chan int)
	go func() {
		defer close(out)
		for num := range in {
			squared := num * num
			fmt.Printf("Squared %d -> %d\n", num, squared)
			out <- squared
			time.Sleep(150 * time.Millisecond) // Simulate work
		}
	}()
	return out
}

// Stage 3: Add 10 to each number
func addTen(in <-chan int) <-chan int {
	out := make(chan int)
	go func() {
		defer close(out)
		for num := range in {
			result := num + 10
			fmt.Printf("Added 10 to %d -> %d\n", num, result)
			out <- result
			time.Sleep(100 * time.Millisecond) // Simulate work
		}
	}()
	return out
}

To run this example, and build the code yourself, check out this and other examples in the go-fluency-concurrency-model-patterns repo. That’s it for this topic, tomorrow I’ll post on the fan-in fan-out pattern.

Concurrency Patterns in Go: A *Short* Deep Dive Series

Introduction

Concurrency is one of those topics that can make even experienced developers break out in a cold sweat. It’s like trying to juggle flaming chainsaws while riding a unicycle on a tightrope. But here’s the thing – in today’s world of multi-core processors, distributed systems, and high-performance applications, understanding concurrency isn’t just a nice-to-have skill; it’s absolutely essential.

Go, with its goroutines and channels, makes concurrency more approachable than most languages. But just because it’s easier doesn’t mean it’s easy. You still need to understand the patterns, the pitfalls, and the best practices to build robust, scalable systems.

That’s what this series is about. We’re going to dive deep into the concurrency patterns that every Go developer should know. Not just the theory – we’ll look at real, working code examples that you can run, modify, and learn from. This blog post is going to also act as the index to the posts, with today starting with the Pipeline Pattern.

What You’ll Learn

This series covers 12 essential concurrency patterns, each with practical examples and detailed explanations. Here’s what’s coming:

1. Pipeline Pattern

The pipeline pattern is like an assembly line for data processing. We’ll explore how to chain operations together, where each stage processes data and passes it to the next. Perfect for ETL operations, data transformation workflows, and stream processing.

2. Fan-out/Fan-in Pattern

This pattern distributes work across multiple workers and then collects the results. Think of it as having multiple chefs working on different parts of a meal, then combining everything at the end. Essential for parallel processing and load balancing.

3. Worker Pools Pattern

Worker pools maintain a fixed number of workers that process jobs from a shared queue. It’s like having a team of specialists ready to handle whatever comes their way. Great for controlling resource usage and handling bursty workloads.

4. Producer-Consumer Pattern

This pattern decouples data production from consumption using a shared buffer. Producers generate data, consumers process it, and the buffer handles the flow between them. Perfect for handling variable production and consumption rates.

5. Supervisor/Restart Pattern

The supervisor pattern monitors workers and automatically restarts them when they fail. It’s like having a manager who ensures critical tasks keep running, no matter what. Essential for building resilient, fault-tolerant systems.

6. Publish-Subscribe (Pub/Sub) Pattern

Pub/Sub decouples message producers from consumers. Publishers send messages to topics, and all subscribers to that topic receive the messages. Perfect for event-driven architectures and broadcasting messages to multiple consumers.

7. Timeouts and Cancellation Pattern

This pattern uses context and channels to control the lifecycle of concurrent operations. It’s about preventing goroutines from running indefinitely and gracefully shutting down operations. Critical for building responsive applications.

8. Rate Limiting Pattern

Rate limiting controls the frequency of operations to prevent resource exhaustion. We’ll explore both fixed-rate and token bucket approaches. Essential for API throttling, resource protection, and preventing DoS attacks.

9. MapReduce Pattern

MapReduce processes large datasets by breaking work into map and reduce phases. It’s like having a team of workers who each process a piece of data, then combining all the results. Perfect for data analytics and batch processing.

10. Singleflight Pattern

Singleflight ensures that only one execution of a function is in-flight for a given key at a time. Duplicate callers wait for the result instead of executing the function again. Great for preventing duplicate expensive operations and API call deduplication.

11. Event Loop Pattern

The event loop processes events from multiple sources in a single thread. It’s like having a central dispatcher that handles all incoming events in a controlled, sequential manner. Perfect for handling multiple event sources efficiently.

12. Resource Pooling Pattern

Resource pooling manages reusable resources like database connections and HTTP clients. Instead of creating and destroying resources frequently, we maintain a pool of ready-to-use resources. Essential for performance optimization and resource management.

Why These Patterns Matter

These patterns aren’t just academic exercises. They’re the building blocks of real-world systems. Whether you’re building:

  • Web services that need to handle thousands of concurrent requests
  • Data processing pipelines that need to scale with your data
  • Real-time applications that need to respond quickly to events
  • Distributed systems that need to be fault-tolerant and resilient

Understanding these patterns will help you make better architectural decisions and build more robust, scalable systems.

What’s Included

For each pattern, you’ll get:

  • Working code examples that you can run and experiment with
  • Detailed explanations of how the pattern works
  • Real-world use cases where the pattern is most effective
  • Performance considerations and best practices
  • Common pitfalls and how to avoid them

Getting Started

All the code examples are available in the concurrency-model-patterns repository. You can run them individually or use the CLI tool to explore different patterns:

go run main.go --pattern pipeline
go run main.go --pattern fan
# ... and so on

Who This Series Is For

This series is for Go developers who want to:

  • Deepen their understanding of concurrency patterns
  • Build more robust systems that can handle real-world challenges
  • Improve their code with proven patterns and best practices
  • Prepare for system design interviews where concurrency is often a key topic

Whether you’re a junior developer looking to level up or a senior developer wanting to refresh your knowledge, there’s something here for you. All of this is written in context of elaborating on the series around maintaining fluency in Go (and other languages) in the face of agentic – AKA vibe – programming.

Let’s Get Started

Ready to dive in? Let’s start with the Pipeline Pattern and work our way through each pattern. By the end of this series, you’ll have a solid understanding of the concurrency patterns that power modern, scalable systems. Maybe you’ll conjure up another one to add? Repo is open sourced over here.

Remember, concurrency is like learning to ride a bike – it might feel wobbly at first, but once you get it, you’ll wonder how you ever lived without it.

Happy thrashing coding!

Implementing Datadog in iOS: A SwiftUI vs UIKit Perspective

I’ve been diving deep into implementing Datadog in iOS applications and wanted to share my experience with both SwiftUI and UIKit approaches and the related elements of the work. Let’s break this down into what works, what doesn’t, and why you might choose various options when using Datadog (or deciding not to use Datadog).

The Setup

First things first, you’ll need these Datadog SDK packages:

dependencies: [
    .package(url: "https://github.com/DataDog/dd-sdk-ios", from: "2.27.0")
]

The core packages we’re using:

  • DatadogCore
  • DatadogLogs
  • DatadogRUM
  • DatadogCrashReporting

The Security Configuration Maze

One of the most frustrating experiences I’ve had with Datadog is managing all the different keys and tokens and the documentation surrounding where, which ones, and what is needed where. Here’s what you need to know:

Required Credentials

  1. Client Token
    • Used for sending data to Datadog
    • Found in: Organization Settings > API Keys
    • Different from API keys (confusing, I know)
  2. Application ID
    • Used for RUM tracking
    • Found in: RUM > Applications
    • Not the same as your client token
  3. API Keys
    • Used for programmatic access
    • Different from client tokens
    • Found in: Organization Settings > API Keys

With that break down, hopefully you won’t run into the problems I ran into. But just so you can identify the problems instantly, here are the confusion points that I stumbled with a few times.

Common Confusion Points

  • Client tokens vs API keys
  • Application IDs vs Client tokens
  • Organization vs User API keys
  • Different keys for different environments
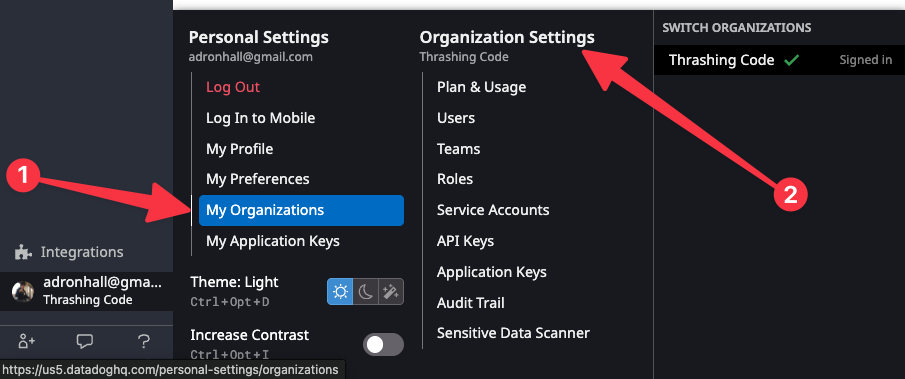
  • Also the “Organization Settings” isn’t under “My Organizations” nor does it lead to the other. Note that tokens also aren’t listed under Organization Settings unless you click on Organization Settings and then it is an option on that screen. All rather disorganized and confusing to sort out, especially giving more than a few docs point incorrectly to just “Organizations” or “Organization” without specifying which. Image to point that out, 1 is very different than 2 in spite of the name “Organization” or “Organizations” being in both.

Screenshot showing Datadog Personal and Organization Settings menu with highlighted 'My Organizations' and 'Application Keys' sections.

If at any point these elements become confusing, stop what you’re doing, back up a step, regroup, recollect your thoughts, and review where you’re at. There is always a good chance you’ve swapped a key or a token or something somewhere in the process of wiring things up.

Best Practices for Key Management

enum Config {
    enum Datadog {
        static let clientToken: String = {
            guard let token = ProcessInfo.processInfo.environment["DATADOG_CLIENT_TOKEN"] else {
                fatalError("DATADOG_CLIENT_TOKEN environment variable is not set")
            }
            return token
        }()

        static let applicationId: String = {
            guard let id = ProcessInfo.processInfo.environment["DATADOG_APPLICATION_ID"] else {
                fatalError("DATADOG_APPLICATION_ID environment variable is not set")
            }
            return id
        }()
    }
}

The UX Experience

Let’s be honest: Datadog’s interface is powerful but not exactly user-friendly. Here’s what I’ve noticed, and have researched realizing I’m not the only one, there is a lot of community feedback too, and they generally think:

The Good

  • Comprehensive monitoring capabilities
  • Powerful query language
  • Extensive customization options
  • Good documentation

The Not-So-Good

  1. Interface Complexity
    • Steep learning curve
    • Overwhelming number of options
    • Non-intuitive navigation
    • Too many clicks to get things done
  2. Dashboard Creation
    • Tedious widget configuration
    • Complex query building
    • Limited drag-and-drop functionality
    • Time-consuming setup
  3. Common Pain Points
    • Finding the right settings
    • Understanding the pricing
    • Managing multiple environments
    • Setting up alerts

Suggested Workarounds

  1. Create templates for common dashboards
  2. Use the API for automation (throw some AI scripting in there to get shit done and you’ll be golden!)
  3. Set up team training sessions

The UIKit vs SwiftUI Implementation

When implementing Datadog in an iOS application, the choice between UIKit and SwiftUI significantly impacts how we approach monitoring and logging. Let’s explore both approaches in detail.

UIKit Implementation: The Traditional Approach

UIKit’s imperative nature requires a more hands-on approach to view lifecycle management and event tracking. Here’s a detailed implementation:

class ViewController: UIViewController {
    // MARK: - Properties
    private let rum = RUMMonitor.shared()
    private let viewKey = "view_controller"

    // MARK: - Lifecycle Methods
    override func viewDidLoad() {
        super.viewDidLoad()
        // Initialize view and setup UI components
        setupUI()
    }

    override func viewWillAppear(_ animated: Bool) {
        super.viewWillAppear(animated)
        // Start tracking when view appears
        // This is crucial for accurate session tracking
        rum.startView(
            key: viewKey,
            name: "ViewController",
            attributes: [
                "screen_type": "main",
                "user_type": "standard"
            ] as [String: any Encodable]
        )
    }

    override func viewWillDisappear(_ animated: Bool) {
        super.viewWillDisappear(animated)
        // Stop tracking when view disappears
        // This ensures clean session boundaries
        rum.stopView(key: viewKey)
    }

    // MARK: - User Actions
    @IBAction func userActionTapped(_ sender: UIButton) {
        // Track user interactions with custom attributes
        rum.addUserAction(
            type: .custom,
            name: "button_tapped",
            attributes: [
                "button_id": sender.tag,
                "action_type": "tap"
            ] as [String: any Encodable]
        )
    }

    // MARK: - Error Handling
    private func handleError(_ error: Error) {
        // Track errors with detailed context
        rum.addError(
            error: error,
            source: .custom,
            attributes: [
                "error_type": "network",
                "retry_count": 3
            ] as [String: any Encodable]
        )
    }
}

This UIKit implementation demonstrates several key aspects:

  • Explicit lifecycle management through view controller methods
  • Manual tracking of view appearances and disappearances
  • Direct access to the RUM monitor for custom event tracking
  • Detailed error handling with contextual information
  • Clear separation of concerns between UI setup and monitoring

SwiftUI Implementation: The Modern Approach

SwiftUI’s declarative nature allows for a more elegant and maintainable implementation. Here’s how we can implement the same functionality:

// MARK: - RUM View Modifier
struct RUMViewModifier: ViewModifier {
    let name: String
    let attributes: [String: any Encodable]
    @StateObject private var loggingService = DatadogLoggingService.shared

    func body(content: Content) -> some View {
        content
            .onAppear {
                // Start tracking when view appears
                // The modifier handles all the tracking logic
                let rum = RUMMonitor.shared()
                rum.startView(
                    key: name,
                    name: name,
                    attributes: attributes
                )
            }
            .onDisappear {
                // Stop tracking when view disappears
                // Clean and automatic cleanup
                let rum = RUMMonitor.shared()
                rum.stopView(key: name)
            }
    }
}

// MARK: - View Extension
extension View {
    func trackRUMView(
        name: String,
        attributes: [String: any Encodable] = [:]
    ) -> some View {
        modifier(RUMViewModifier(name: name, attributes: attributes))
    }
}

// MARK: - Example View Implementation
struct ContentView: View {
    @StateObject private var viewModel = ContentViewModel()

    var body: some View {
        VStack {
            // View content
            Button("Perform Action") {
                handleUserAction()
            }
        }
        .trackRUMView(
            name: "ContentView",
            attributes: [
                "screen_type": "main",
                "user_type": "standard"
            ]
        )
    }

    private func handleUserAction() {
        // Track user actions with automatic view context
        let rum = RUMMonitor.shared()
        rum.addUserAction(
            type: .custom,
            name: "button_tapped",
            attributes: [
                "action_type": "tap",
                "timestamp": Date()
            ] as [String: any Encodable]
        )
    }
}

The SwiftUI implementation offers several advantages:

  • Declarative tracking through view modifiers
  • Automatic lifecycle management
  • Reusable tracking components
  • Cleaner, more maintainable code
  • Better integration with SwiftUI’s state management

Key Implementation Differences

The fundamental difference between these approaches lies in how they handle view lifecycle and state management. UIKit requires explicit tracking at each lifecycle point, while SwiftUI provides a more automated approach through its view modifier system.In UIKit, we must manually track view appearances and disappearances, which can lead to more boilerplate code but offers greater control over the tracking process. This is particularly useful in complex applications where you need fine-grained control over what gets tracked and when.SwiftUI, on the other hand, handles much of this automatically through its view modifier system. The RUMViewModifier encapsulates all the tracking logic, making it easy to add tracking to any view with a single line of code. This approach is more maintainable and less prone to errors, but it may be less flexible in certain edge cases.

Performance and Debugging Considerations

When it comes to performance, UIKit’s explicit tracking can be more efficient in complex scenarios where you need to carefully manage what gets tracked. However, this comes at the cost of more boilerplate code and potential for errors.SwiftUI’s automated tracking is more convenient but may introduce some overhead in complex view hierarchies. The key is to use appropriate sampling rates and batch tracking when possible to minimize this impact.Debugging tracking issues in UIKit is generally more straightforward due to the explicit nature of the implementation. You can easily add breakpoints and inspect the tracking state at each lifecycle point. SwiftUI’s more automated approach can make debugging more challenging, but proper logging and error handling can help mitigate this.

Migration and Hybrid Approaches

For teams transitioning from UIKit to SwiftUI, a hybrid approach is often the most practical solution. You can maintain the existing UIKit tracking while gradually introducing SwiftUI components with their own tracking implementation. This allows for a smooth transition while ensuring consistent monitoring throughout the application.The key to successful implementation in either framework is maintaining consistent tracking patterns and proper documentation. Whether you’re using UIKit, SwiftUI, or a combination of both, clear guidelines and best practices will help ensure effective monitoring and debugging capabilities.

The Verdict

If you’re starting a new project, I’d recommend going with SwiftUI. The declarative nature makes implementing Datadog tracking much cleaner and less error-prone. However, if you’re working with an existing UIKit codebase, the UIKit approach is perfectly valid and gives you more granular control.

The key is to be consistent with whichever approach you choose. In my implementation, I’ve gone with SwiftUI because:

  1. Less boilerplate code
  2. Better state management
  3. Automatic lifecycle handling
  4. More maintainable in the long run

A Few Best Practices

  1. Environment Variables
    • Keep sensitive data out of the code
    • Use proper configuration management
    • Document your setup process
  2. Logging
    • Use appropriate log levels
    • Include relevant context
    • Don’t log sensitive data
    • Batch when possible
  3. Performance
    • Monitor memory usage
    • Use appropriate sampling
    • Keep an eye on network calls
  4. Maintenance
    • Regular SDK updates
    • Monitor log volume
    • Review and adjust as needed

The Cost Factor

Let’s talk about the elephant in the room: Datadog’s pricing structure. It’s… complicated. Here’s what you need to know:

Base Pricing

  • Free tier: Limited to 5 hosts, 1-day data retention
  • Pro tier: Starts at $15/host/month
  • Enterprise tier: Custom pricing

What You’re Actually Paying For

I must add a caveat here. The following is based on quick RTFMing and Reddit reading, plus some other research. However some of this data I’m not sure if it is up to date, or what you might get in their Enterprise oriented options, or in some other scenarios. It’s all kind of confusing really, so YMMV based on your consumption of and relationship with Datadog. I’m not the price guy so some of this might be off by one or just wrong.

  1. Log Management
    • $0.10 per million log events
    • Additional cost for longer retention periods
    • Indexed logs cost more than non-indexed
  2. RUM (Real User Monitoring)
    • $1.50 per 1,000 sessions
    • Additional costs for custom events
    • Session replay features cost extra
  3. APM (Application Performance Monitoring)
    • Included in host-based pricing
    • Additional costs for custom metrics
    • Trace ingestion costs extra

Hidden Costs to Watch Out For

  • Data transfer costs
  • Storage costs for longer retention
  • Custom metrics and events
  • Team member seats
  • Support level costs

Cost Optimization Tips

  • Implement log sampling
  • Use appropriate log levels
  • Set up log retention policies
  • Monitor your usage regularly
  • Consider using the free tier for development

Wrapping Up

Whether you choose UIKit or SwiftUI, Datadog provides powerful monitoring capabilities for your iOS app. The key is to implement it in a way that makes sense for your project’s architecture and team’s expertise.

For my part, I’ve found the SwiftUI implementation to be more maintainable and less error-prone, but your mileage may vary depending on your specific needs and constraints.

Let me know if you’ve got any questions or want to dive deeper into any particular aspect!

References

This implementation is part of my simply-swiftly-logging project, where you can find the complete code and more detailed documentation.

Stop Wasting Time on Teams: 3 Additional Hacks for Fixes You Need

Here’s an unvarnished truth: if you’re still clicking around Teams like it’s 2010, you’re wasting time. Stop complaining and learn these three hacks your future self will thank you.

NOTE: No, I’m not becoming a Microsoft Teams blogger, it’s just these along with a few other prospective features can help when stuck dealing with Microsoft Teams. Since I have to be tortured with such an app, I’m just offering this meager help via blog entries. Otherwise, you can rest assured I’ll be back to regularly scheduled software development and related technical topics very soon!

1 » Stop Clicking » Use Slash Commands & Keyboard Shortcuts

  • What to do: Hit Ctrl + E (Win) or ⌘ + E (Mac) to jump to the command bar (yeah, there’s a command line, also see docs), then type / and a command:
    • /dnd to set Do Not Disturb
    • /call [name] to ring someone immediately
    • /files to see your recent docs
  • Plus: Memorize the basics:
    • Ctrl + Shift + M to mute/unmute
    • Ctrl + Shift + O to toggle your camera
    • Ctrl + N to start a new chat
  • Why it matters: Teams is famously sluggish, stop letting the UI slow you down. If you can’t spare ten minutes to learn these, fine then keep clicking.

2 » Pop-Out Chats and Meetings into Their Own Windows

  • What to do: Right-click any chat, channel conversation or meeting entry and choose “Pop out”, or hit the little diagonal-arrow icon in the top-right of a chat.
  • Why it matters: One giant, tab-filled window is a productivity killer. Pop-outs let you spread chats and meetings across monitors, so you’re not constantly Alt-Tabbing. Microsoft buries this feature but it’s a required feature if you want to really negate Microsoft Teams negative impact.

3 » Tame the Notification Beast with Filters & Tags

  • Notification Settings:
    • Go to Settings → Notifications and mute every channel mention, reaction, or thread you don’t absolutely need.
    • Set your Activity feed to show “Mentions & replies only” via the filter dropdown to stop drowning in the chaos.
  • Use Tags (if you can, more nightmares IYKYK):
    • Create Tags like @dev, @design, @QA so you only get pinged when someone tries to rope in your team.
    • Pro-tip: Don’t go overboard with too many tags = just as much noise as channels. Also, too many as with many things (like Outlook) can lead to other calamity like app crashes.
  • Why it matters: By default Teams spams you for everything. Prune ruthlessly or you’ll never see the messages that actually matter.

That’s another three hacks for you that will actually work. If you’re still griping about Teams being “so clunky,” take five minutes right now to set these up and it’ll free up time for finding the other features (or lack of) to gripe about with Teams. Otherwise, keep losing hours every week to menu-diving and ping overload. Zoom zoom! (pun not particularly intended)