Learning Go Episode 1 – Environment, Go Workspace, GOPATH/GOROOT, Types, and more Introduction

Episode Post & Video Links:  1 (this post), 2, 3, 4, 5, 6, 7, and 8. Non-linked are in the works! Videos available now on Youtube however, so check em’ out!

This is episode one of a multi-part series on “The Go Programming Language“. Not necessary, but if you’d like to follow along you can also pick up the book “The Go Programming Language” by Alan A. A. Donovan and Brian W. Kernighan. At the bottom of the description I have a link to the book publisher’s website and the respective book. I’ll be using that as a guideline and using a number of examples from the book. However I’ll also be adding a lot of additional material around Goland IDE from Jetbrains and Visual Studio Code. The video link to this session is at the bottom of the post, scroll all the way down and it’s waiting for you there.

3:28 – Getting started, introducing that the session I’m starting with a completely new Ubuntu Linux load so that I ensure we cover all of the steps to get up and running. These steps, even though they’re on Linux are reproducible on Windows 10 and MacOS, so any operating system is usable to follow along with, with only minor discrepancies.

5:04 – Introducing the book that I’ll be using as a guideline reference so that viewers can also follow along with a physical book. I’m a big fan of multisensory learning, so between a book, the stream, being able to ask questions in the channel, it’ll give viewers a chance to learn and undertake their coding adventures in Go using all sorts of methods.

Book Reference: “The Go Programming Language” by Alan A. A. Donovan and Brian W. Kernighan

6:58 – Discussing where Go is located on the web related to Github and the golang.org site that is useful in that one can even try out little snippets of Go code itself, on the site! Github: https://github.com/golang/go Golang: https://golang.org 10:40 – Setting export in the .bashrc file (or .bash_profile on MacOS or environment variables on Windows 10). Speaking of Windows 10 specifically, Linda Gregier wrote up a great blog post on getting Go setup on Windows specifically. 14:50 – Setting up the Go workspace path for GOPATH using the standard Go convention. From here I get into the first “Hello World!” with Go. 15:34 – Mention of setting up Go on a Docker container and how it is easier, but we’re staying focused on setting it up completely from scratch. 18:20 – Starting first code, a standard “Hello World” program. 19:50 – First build of that “Hello World” program. 20:34 – Here I introduce go run and how to execute a singular file instead of building an entire project. 21:32 – Installing some IDE’s to use for developing Go applications. The first two up for installation is Visual Studio Code and JetBrains Goland. 29:00 – A first variable, what is it, and how to declare one in Go in one of the ways one can declare a variable in Go! 31:08 – Introducing the terminal in Visual Studio Code. 37:12 – A little example of OBS, how I’m using it, and how I interact back and forth with chat and related tooling plus the virtual machine itself. 42:36 – Changing themes and adding plugins for Goland. In the plugins I also find the most epic of status bars, the Nyan Cat! 59:00 – Here I start to get back into some more specific Go details. Starting off with a Go command line parsing application. At this point I also cover several additional ways to declare variables, speak more about short declarations, and other ways to declare, assign, and use variables in Go.

At this point I also go through a number of examples to exemplify how to go about declaring variables, build, run, and explore the details of the code. Further along I also get into string formatting, concatenating, and related string manipulation with Go.

Other details include taking a look at extra ways to figure out Go code using autocomplete inside Goland and other exploratory features. Eventually before wrapping up I broach pointers, tuple declaration techniques, and how to declare additional functions beyond func main(). 1:58:40 – Adding dependencies and generating random data. At this point I bring in a dependency. But before pulling in the dependency, after introducing it, I show how to go about doing. 2:00:10 – New machine, and I run into git not being available. The go get command uses git to pull dependencies so I go about why this is needed and the steps to install on Ubuntu. 2:09:20 – Introduction to more concepts around dependencies, what go get does versus managing dependencies with Go Dep. 2:10:00 – Installing Go Dep; MacOS, using curl, Linux installation, and a question sort of remains to get it running on Windows. The easiest method is using chocolatey however, so check that out if you’re going the Windows route. 2:15:20 – Setting up Go Dep integration with Goland. 2:23:55 – Showing off Goland’s commit dialog and some of the respective options.
4 Discovered Axioms of #DevRel

The idea of DevRel, or Developer Relations and the position of Developer Advocates in the industry has become more defined in the last decade than it traditionally has been. In getting to this point there are several key points that have come up that are practical axioms in industry. Some people don’t agree with all of these, and I’d infer that they’re probably just wrong, but the vast majority in industry and specifically working in DevRel itself have these axioms that they’d often stand by. If not march up on the hill to fight for!

  1. Developer Advocates and Developer Relations should NOT exist under any marketing hierarchy.Microsoft killed off this organizational structure, Google never let it happen, and AWS also insured this isn’t how this operated. If anything it’s either it’s own branch feeding directly into the executive team under the CTO, or it is a breakout of the engineering group usually under a VP of engineering or related structural organization. Having Developer Advocates under marketing tends to bring out bad habits (forced talks at trade shows that are just the company spiel) or topics that just don’t align to anything (like talks on X feature that nobody uses implemented in a way that is broken). The end product of having Developer Advocates and Developer Relations work and report up to a marketing leadership hierarchy devalues their work, what they can and indeed do provide that is valuable, and can diminish the credibility that advocates have to fight for so diligently in the first place. For further ideas around this axiom, Francine Hardaway also wrote a great post on just this issue, asking where DevRel should exist.
  2. DevRel & Developer Advocates need to be self-disciplined, build, show, and be technically inclined as much as any software engineer, coder, hacker, or related individual is expected to be. I’m not talking about “make nonsense deadlines and work to death” like some development teams get stuck with, but we advocates do need to build solutions that parallel or innovate on the designs that are in place, in production, and giving us value today. Developer Relations at its core is there to bring value and show value in what X solution can do but needs to provide example and take what exists in industry and build on it.
  3. Developer Advocates serve a two way street of communication, one to developers and users and one back to the internal engineers, product, and leadership working on building products and services. Advocates collect, or as I sometimes call it, perform reconnoiter or reconnaissance, and bring that data back to the various teams within company to determine actions to take. I personally love this part of the job, since I like to make sure that the development teams have the information they need to build products and services that are really needed, valuable, and will get the most bang for the buck. I’ve also never met a developer that doesn’t want to know the direction their developing in is the right direction. This kind of direct data is an invaluable information base for the development teams.
  4. Developer Advocates do not always work directly with customers, but we do indeed and should be communicating with them on a regular basis. Helping to organize discussions, conversations, and future directions of research for product and services usage is very important. We can act as that individual or team for companies that often don’t have enough time to put somebody on a research project, where as we can do that, and provide general information deducting what is or isn’t’ the right path to travel. As developer advocates we have the freedom to often take the path of risky research. We provide an extremely valuable service to the companies we work for, the customers we communicate with, and the industry as a whole by doing this research and making it available (i.e. blog it!)

Got anymore axioms you see in industry around DevRel work? I’d be happy to put together a larger list, this is just the beginning so far as I begin the first steps of a journey into understanding future directions and detailed specifics about how advocacy can increase its value for company, customer, and personal efforts.

Let’s Talk Top 7 Options for Database Gumbo

When one starts to dig into databases things get really complex really fast. There’s not only a whole plethora of database companies and projects, but database types, storage engines, and other options and functionality to choose from. One place to get a start is just to take a look at the crazy long list of databases on db-engines. In this post I’m going to take a look at a few of the top database engines to create a starting point – which I’ll reference – for future video streaming coding sessions (follow me @ twitch.tv/adronhall).

My Options for Database Gumbo

  1. Apache Cassandra / DataStax Enterprise
  2. Postgresql
  3. SQL Server
  4. Elasticsearch
  5. Redis
  6. SQLite
  7. Dynamo DB

The Reasons

Ok, so the list is as such, and as stated it’s my list. There are a lot of databases, and of course some are still more used such as Oracle. However here’s some of the logic and reasoning behind my choices above.

Oracle

First off I feel like I need to broach the Oracle topic. Mostly because of their general use in industry. I’m not doing anything with Oracle now, nor have I for years for a long, long, LONG list of reasons. Using their software tends to be buried in bureaucratic, oddly broken and unnecessary usage today anyway. They use predatory market tactics, completely dishonorable approach to sales and services, as well as threatening and suing people for doing benchmarks, and a host of other practices. In face to face experiences, Oracle tends to give off experiences, that Lawrence from Office Space would say, “naw man, I think you’d get your ass kicked for that!” and I agree. Oracle’s practices are too often disgusting. But even from the purely technical point of view, the Oracle Database and ecosystem itself really isn’t better than other options out there. It is indeed a better, more intelligently strategic and tactical option to use a number of alternatives.

Apache Cassandra / DataStax Enterprise

This combo has multiple reasons and logic to be on the list. First and foremost, much of my work today is using DataStax Enterprise (DSE) and Apache Cassandra since I work for DataStax. But it’s important to know I didn’t just go to DataStax because I needed a job, but because I chose them (and obviously they chose me by hiring me) because of the team and technology. Yes, they pay me, but it’s very much a two way street, I advocate Cassandra and DSE because I personally know the tech is top tier and solid.

On the fact that Apache Cassandra is top tier and solid, it is simply the remaining truly masterless distributed database that provides a linear path of scalability on the market that you can use, buy support for, and is actually actively and knowingly maintained not just by DataStax but by members of the community. One could make an argument for MongoDB but I’ll maybe elaborate on that in the future.

In addition to being a solid distributed database there are capabilities inherent in Apache Cassandra because of the data types and respective the CQL (Cassandra Query Language) that make it a great database to use too. DataStax Enterprise extends that to provide spatial (re: GIS/Geo Data/Queries), graph data, analytics engine, and more built on other components like SOLR and related technology. Overall a great database and great prospective combinations with the database.

Postgresql

Postgres is a relational database that has been around for a long time. It’s got some really awesome features like native JSON support, which I’m a big fan of. But I digress, there’s tons of other material that lays out thoroughly why to use Postgres which I very much agree with.

Just from the perspective of the extensive and rich data types Postgres is enough to be put on this list, but considering there are a lot of reasons around multi-tenancy, scalability, and related characteristics that are mostly unique to Postgres it’s held a solid position.

SQL Server

This one is on my list for a few reasons that have nothing to do with features or capabilities. This is the first database I was responsible for in its entirety. Administration, queries, query tuning, setup, and developer against with the application tier. I think of all my experience, this database I’ve spent the most time with, with Apache Cassandra being a close second, then Postgres and finally Riak.

Kind of a pattern there eh? Relational, distributed, relational, distributed!

The other thing about SQL Server however is the integrations, tooling, and related development ecosystem around SQL Server is above and beyond most options out there. Maybe, with a big maybe, Oracle’s ecosystem might be comparable but the pricing is insanely different. In that SQL Server basically can carry the whole workload, reporting, ETL, and other feature capabilities that the Oracle ecosystem has traditionally done. Combine SQL Server with SSIS (SQL Server Integration Services), SSRS (SQL Server Reporting Services), and other online systems like Azure’s SQL Database and the support, tooling, and ecosystem is just massive. Even though I’ve had my ins and outs with Microsoft over the years, I’ve always found myself enjoying working on SQL Server and it’s respective tooling options and such. It’s a feature rich, complete, solidly, and generally well performing relational database, full stop.

Elasticsearch

Ok, this is kind of a distributed database of sorts but focused more exclusively (not totally since it’s kind of expanded its roles) search engine. Overall I’ve had good experiences with Elasticsearch and it’s respective ELK (or Elastic ecosystem) of tooling and such, with some frustrating flakiness here and there over the years. Most of my experience has come from an operational point of view with Elasticsearch. I’ve however done a fair bit of work over the years in supporting teams that are doing actual software development against the system. I probably won’t write a huge amount about Elasticsearch in the coming months, but I’ll definitely bring it up at certain times.

Redis / SQLite / DynamoDB

These I’ll be covering in the coming months. For Redis and DynamoDB I have wanted to dig in for some comparison analysis from the perspective of implementing data tiers against these databases, where they are a good option, and determining where they’re just an outright bad option.

For SQLite I’ve used it on and off for many years, but have wanted to sit down and just learn it and try out some of its features a bit more.

‘bash’ A.K.A. The Solution for Everything – Passed Variables & The Script Filename

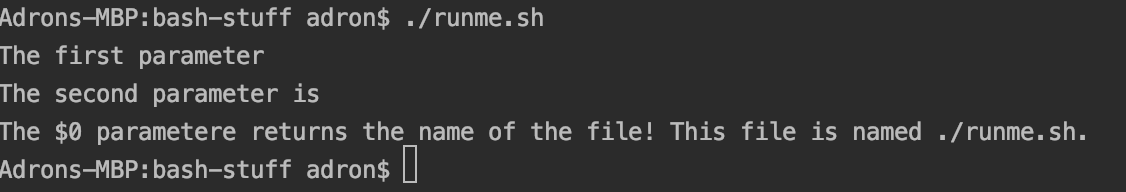
When writing a script in bash you can pass parameters into that script to work with. For example, let’s say I have a script file called runme.sh and I want to pass in my name and today’s date. I could do that like this.

./runme.sh "Adron Hall" "12/27/2018"

Inside the script I can get access to the parameters by using the bash param variables of $1, $2, and so on. With a little bash code written up like this.

echo "The first parameter $1"

echo "The second parameter is $2"

echo "The \$0 parametere returns the name of the file! This file is named $0."

View the gist on GitHub

dghubble:go-twitter- Go Twitter REST and Streaming API v1.1 2

It’s 2019. Resolutions.

2018 might have been the first year I setup some resolutions. I honestly find them pretty silly. However I have joined the band wagon, and by doing so here are my thoughts on resolutions for 2019.

New Resolutions

Alright, these are entirely new for this year. It seems wise that I’ll just put together three, listed below, since I have a number of failings from 2018 that I’ll need to slot into my continuing resolutions list, and of course turn those into successes this year!

  1. Increase my streaming (specifically with Twitch) and the correlative videos around coding, systems, and related technologies. Possibly, even throw in some *gaming*!
  2. Go office-less again. My aim is to not be tied to a desktop, an office, or related physical place and again go roaming coder again (also one of the inspirations behind getting a new laptop). This way I can also ensure I get out and to more meetups, hackathons, or whatever events that look good.
  3. Compose and record some music. I would say record more music, but I haven’t recorded any music in ages so I’m going to remedy this at some point this year.

A few other things, which I wouldn’t declare as failures if I don’t get them finished this year, but the likelihood I start writing a book is pretty high. I’ll also organize more than a few larger type events (i.e. beyond a user group meetup, such as more conferences like ML4ALL or maybe a open spaces conf).

Continuing Resolutions

Heyo I sound like Congress now! The resolutions are from the previous year that I will be continuing to either succeed at or aim to succeed at. For specifics on each of these just navigate back to yesterday’s retrospective.

  1. Write More Code, Build Patterns, & Algorithms (Previous Year‘s Status: failed)
  2. Make OSS Workable for Me (Previous Year‘s Status: failed)
  3. Get More Active (Previous Year‘s Status: failed)
  4. Self Health (Previous Year‘s Status: failed)
  5. Improve Local Communities (Previous Year‘s Status: failed)
  6. Beer (Previous Year‘s Status: Succes!)
  7. Communications Improvements (Previous Year‘s Status: Succes!)
  8. Cell Phone Disruption (Previous Year‘s Status: Succes!)

Done Resolutions

These resolutions are resolutions that I’ve just decided I’m done with. Not going to do anymore or maybe they were just one offs, things that were a do once thing, such as “see Within Temptation play a show“.

  1. Re-initiate in Industry – This was really the only one off resolution from 2018. I managed to really get it done too. As for continuing to be involved in industry that’s kind of covered, easily, by continuing resolutions above.

With that, whether we’re ready for it or not, here’s 2019! Cheers!