The article examines the CAP Theorem and its impact on distributed systems, focusing on Apache Kafka, Flink, and Cassandra. It discusses trade-offs in consistency, availability, and partition tolerance, especially during network partitions. Moreover, it provides deployment strategies and mitigation techniques for challenges within these systems, including insights on Confluent Cloud’s management of CAP issues. Continue reading →
Over the past few months I’ve picked up a number of libraries in the Go ecosystem to help me get work done around database engineering. These libraries are ones that I have used to do a range of work primarily around Apache Cassandra, DataStax Enterprise, PostgreSQL, and to a lesser degree MS SQL Server, MySQL,... Continue reading →
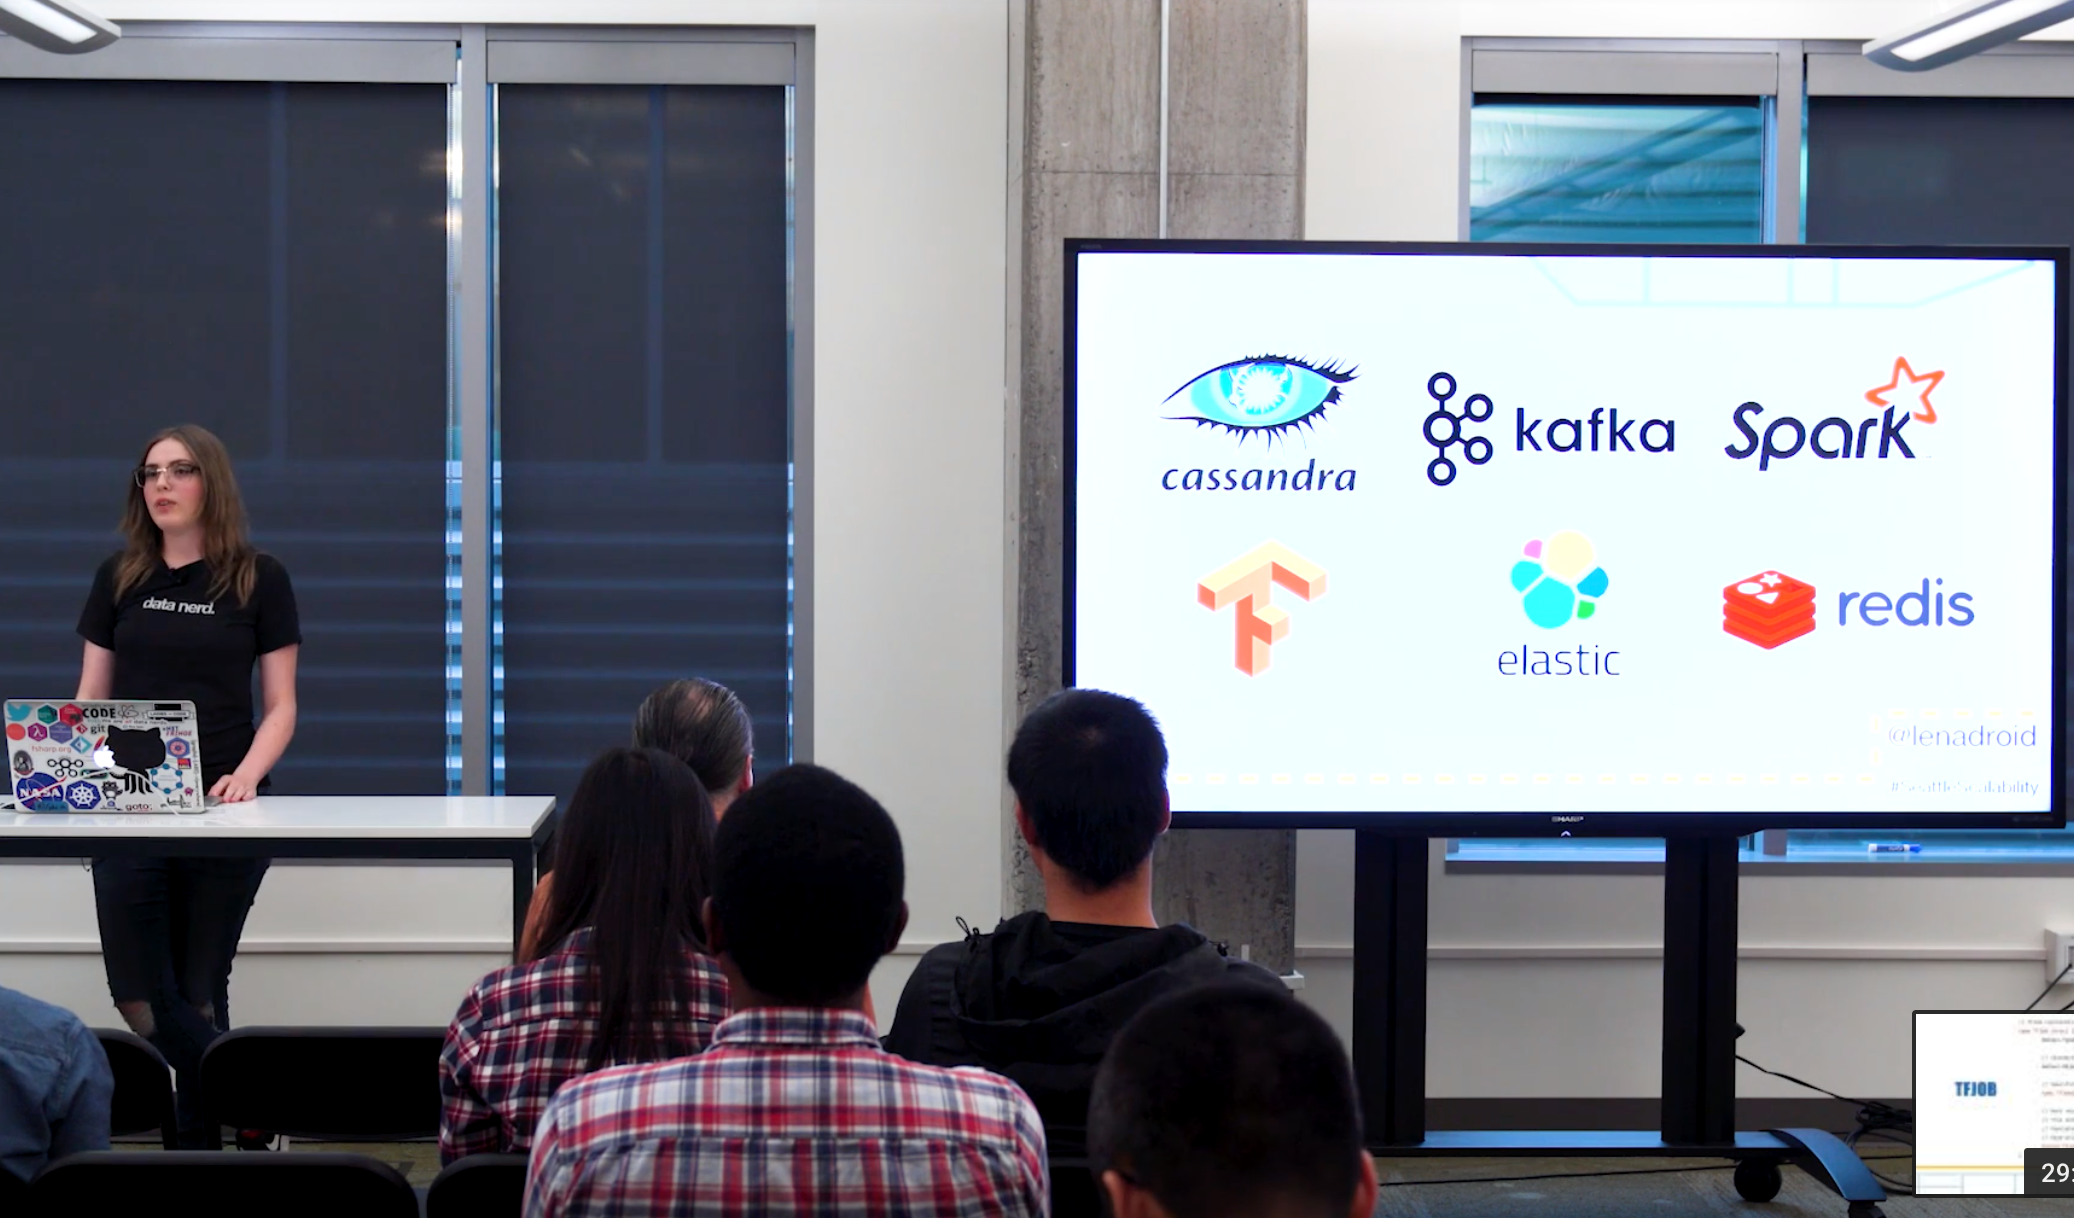
If you’re interested in running data-intensive systems (think Apache Cassandra, DataStax Enterprise, Kafka, Spark, Tensorflow, Elasticsearch, Redis, etc) in Kubernetes this is a great talk. @Lenadroid covers what options are available in Kubernetes, how architectural features around pods, jobs, stateful sets, and replica sets work together to provide distributed systems capabilities. Other features she continues... Continue reading →